
Вы здесь
Новости LessWrong.com


Live disagreements with people around me
I’m pretty interested in conveying the costs of letting AI development proceed unchecked to the general public. In relation to this, I feel like I run into a lot of disagreements with people around me.
Misc very quickly written points on which my own impression has seemed very different from others in recent months:
1. It’s way, way, way more important that we stop dangerous AI soon than that we ensure that we don’t stop AI too much
I have the sense the sophisticated and worldly position here is to be very concerned about ‘over-regulation’ and about not doing exactly the right regulations. But it’s an obvious pragmatic fact that the stakes of overregulation are minuscule compared to the stakes of underregulating here. And the stakes of mis-regulation are very often going to be unintended slowing, which is in the same bucket.
2. If we stopped AI development, the risk of not starting up again for an extremely long time is low
This one just feels kind of crazy to me, like I may be missing something. In combination with the above point, it feels like if I met someone who was on fire, and they didn’t want me to put out the fire, in case they couldn’t figure out how to get warm again, ever. Like, forever is a long time, and if this thing is so great, you’re probably not going to forget about it! It’s like you think the current instantiation of yourself (or society) is so much more agentic than your future selves, that it’s worth huge costs to keep power in the current version’s hands.
3. Getting the public involved is not very dangerous
Some people seem to think of the public as like a kind of wild and crazy god one could awaken, with very high variance results. I think this doesn’t give them nearly enough credit. While I disagree with the public on quite a lot of points, I think disagreements are a lot more salient than agreements. We might disagree a lot on exactly how the FDA proceeds or who gets in how much trouble for doing what with which drugs. But we agree that broadly medical interventions and drugs are dangerous for people, and on wanting more safety around things that kill people, and I bet a lot of the details I don’t notice are better than nothing. And in a specific case where the default is insanely dangerous, bringing more people with power into the room, who are liable to stop things that are dangerous, and couldn’t really at this point make it much worse, seems pretty safe.
4. Public comms is not that rife with downside risks
There is a general sense that it is riskier to donate to groups hoping to talk to the public, because they can have large scale effects and make everyone look bad. So people donate their money to ‘safe bets’ such as e.g. technical safety. I think this is generally very miscalibrated. Talking to the public incompetently isn’t as far as I can tell much more likely to have reputational risks than doing other stuff incompetently, because everyone is in public. I don’t see many examples of this happening at a scale larger than the positive effects.
5. Pausing advanced AI soon greatly increases our chances of surviving
For one thing, I’d say the world’s degree of not giving a shit about safety in this case of advanced AI right now is extremely unique among issues, and if we wait for long enough for people to reckon with what’s happening at all, it is very unlikely to proceed in such wildly reckless way later on.
Also, I just expect us to make a lot of progress in understanding current AI models and organizing ourselves to not do crazy things if we have another decade to work out the kinks.
6. We don’t need a plan before we pause
People seem to think we do. I don’t know what’s up with that.
7. Raising the alarm is very important at the moment
I feel like people around me mostly agree that raising the alarm is good, but I’m surprised by the frequency of ambivalence about it. Partly this is to do with earlier points and related things, such as ‘what if people become too scared about AI and something bad happens’.
8. Working on marginally improving safety of models at the AI companies is not remotely competitive with raising the alarm at the moment
From my current vantage, it seems like people building AI do not mostly expect if AI left our control soon for it to be solidly aligned with a high probability. And they don’t seem to think we are close to that. So for a high chance of success, we really need to avoid that happening and we can make a lot of progress on that on the margin. Whereas if we know we are far from safety right now, adding marginal safety in a scenario where we are about to lose control seems pretty hopeless.
9. Doing advocacy doesn’t seem to have adverse effects on people doing it
I’ve heard a couple of times that people who do advocacy seem to go crazy. I don’t know of anything that seems like solid evidence of this, and weak or circumstantial evidence seems to only involve a handful of people.
And one where I feel like I haven’t heard so much disagreement lately:
10. It matters what the public think / political will is growable
I’ve been interested in talking to the public for a long time, and people have often disagreed with me. My sense is that they have often thought it seemed pointless. Because the public doesn’t have power. But I think the public does have power, and not just because they can ultimately vote. People care what other people think, including elites, and experts and people with power. Nobody is coming to their views in a vacuum. This matters.
Discuss
OpenAtom and Elemental
Compact nuclear power had long been considered intractable for civilian use. But on a cold December day, at an alternative energy conference, a team of academics reveals a new discovery: charging up small nuclear reactors over several days at high energy can produce clean power output. It is not yet competitive with other energy sources, but it does seem promising. The name of this new technology is Compact Nuclear Power (CNP).
Some note that at larger energy loads, CNP cores might become unstable, leading to meltdowns or explosions. The risks remain theoretical for now.
OpenAtomFuel materials and CNP core design continue to improve. ExxonMobil releases some early commercially viable cores. It is becoming clear that this technology will be transformative—at minimum, it will accelerate world energy production at a time that it is greatly needed, and some even say that it will unlock transmutation, creating plentiful quantities of various elements from feedstock. A group of concerned nuclear engineers convene to create a nonprofit, OpenAtom, that will distribute the benefits of the technology better than a private company would.
Its stated goal: "Our goal is to advance energy distribution in the way that is most likely to benefit humanity as a whole, unconstrained by a need to generate financial return... it’ll be important to have a leading research institution which can prioritize a good outcome for all over its own self-interest."
Given the competitive nature of what the technological race could develop into, OpenAtom commits to joining efforts of other humanity-focused nuclear energy producers in its charter, if it runs into a scenario where race dynamics would limit the capacity to develop CNP in a safe manner.
Notwithstanding, the same document maintains "OpenAtom must be on the cutting edge of nuclear energy development—policy and safety advocacy alone would be insufficient."
The concerns around the new technology are not universal. Leading nuclear physicist Arnold Ng adds, "Worrying about a massive CNP explosion today is like worrying about ChatGPT going rogue."
Concerns multiplySocial media is abuzz with reports that the big energy providers are mining uranium in large quantities. The environmental movement is enraged. Some critics say that the uranium depletion pales in comparison to existing coal mining and oil drilling, but their reports never quite seem to curb the uranium outrage.
2023In May, CNES, the Center for Nuclear Energy Security, releases an open letter: "Mitigating the risk of planetary explosion should be a global priority alongside other societal-scale risks such as pandemics and AI takeover." CEOs of the foremost nuclear energy companies and nuclear scientists sign.
That summer, OpenAtom releases a statement saying: “Currently, we don't have a solution for shielding or controlling a potentially supernuclear core, and preventing it from exploding.”
April 3rd, 2025A nonprofit investigating the rate of progress on nuclear energy production, the Nuclear Futures Project, releases a scenario forecast where they predict that supernuclear energy production is possible—but with high odds of blowing up the entire planet. Vice President TJ Mantz remarks: "We could wake up very soon in a world where there is no protection from nuclear explosions."
Later in July, the US government unveils a directive: Winning the Race—America's Nuclear Action Plan. It calls for faster energy production and removal of regulations.
April 2026Elemental announces a new core with improved power density. Rumors surface that the core can convert traces of certain long-lived radioactive isotopes into shorter-lived ones. The process still requires carefully prepared samples, but appears to work across a wider range of materials than earlier cores. Some researchers see it as an early sign that CNP could eventually produce scarce elements from common feedstock.
At the same time, Elemental finds that it can use these new cores to accelerate improvements in radioactive shielding. It spins up a program for other organizations to improve their ability to remove nuclear fallout, in case of any future CNP meltdowns.
AmarilloIt is July 16th. Residents on the outskirts of the Texas city of Amarillo are awakened in the early morning to a deep boom. Later, they learn that an OpenAtom CNP has exploded. The fallout kills thousands of livestock from local ranches, but thankfully, no people are killed. The ranches affected by the fallout sue for $100 million in damages.
OpenAtom lets a group of three researchers enter its facilities and examine some security footage. The initial records are incomplete, and the investigation’s scope excludes earlier incidents. OpenAtom subsequently provides more footage. The researchers produce a report describing a network of over a thousand linked cores, hundreds of which were involved in the chain reaction.
Sept 2026OpenAtom releases a result: using some of its ultra-high-energy cores, it is able to convert lead into silicon. The new cores are still unavailable to the government or wider public.
The world hears, some for the first time, that the employees at nuclear energy companies are increasingly worried about the technology. One writes:
I resigned from Elemental today. I spent the last three years doing thermal physics research at both OpenAtom and Elemental. Neither company is acting responsibly. They are racing straight to build supernuclear machines and gambling with our lives. More thoughts below.
A researcher currently at Elemental adds:
He's correct here—we really do earnestly believe CNPs could trigger a world-destroying explosion! I personally think it is >10% within the next decade. I believe Elemental is trying its best, but we do not yet have a plan to solve spontaneous reactor blowups and are not clearly on track to.
Less than a week later, Elemental's CEO publishes an essay titled Nuclear Caution. In it, he prescribes the need to slow the acceleration of energy production and high-energy experiments. OpenAtom, DeepCore, and xNuke CEOs join him in supporting the need for nuclear energy companies to slow the rate at which they accelerate energy production.
In the aftermath of these indictments, news reporters find themselves asking the nuclear researchers the same question: "How would CNPs actually explode?" The response: "We don't understand the mechanisms of how CNPs could actually produce as much energy as they are. It's hard to predict how they could actually explode, there are so many ways it could happen that would be unimaginable from our vantage."
CNP explosions become so routine that the month of October is christened "Grey October". However, Elemental and OpenAtom continue with their programs to help rural communities with the fallout cleanup.
Nov. 5, 2026NETR, the Nuclear Evaluation and Threat Research nonprofit, releases a report of Elemental’s progress on CNP development. It estimates that the pace of improvements on standardized core-performance tests has roughly doubled relative to the earlier trend. The evaluators tentatively attribute most of the acceleration—perhaps 80%—to using existing cores in the development of better ones, with substantial uncertainty.
The full report is not available to the public. Company leaders shelve a project looking to investigate the energy allocation used on CNP development. The report that is released is full of redactions—Elemental’s RSO (Responsible Scaling Officer) maintains that further knowledge of the lab’s processes would enable competitors to produce more and more energy, making it possible to create cores that could be more dangerous than those made before. The extent to which Elemental's leadership is willing to slow down its own efforts remains unclear.
Discuss
Eyesight as a replicator, with genes as its vehicle
Dear reader, this post will be completed in some hours; I'm posting it now because I'm participating in justwrite.club and I don't want to forfeit $1k. I'll remove this note when it's done. That said, the sections that are below are real; what I'm still doing is adding the "coming soon" sections.
----
Or: The payload lens on Darwin
Tl;dr: What is the most natural teleological shorthand to use, when thinking about evolution?
The “gene-centered view” of e.g. Dawkins says: genes are “trying” to increase the number of exact copies of themselves. And organisms are “vehicles” genes use to survive.
The “payload lens” (which I’ll be pitching) says: adaptive payloads (such as eyesight or fair meiosis) are “trying” to become deeper, stabler attractor basins that can team up with other adaptive payloads. And genes are “vehicles” these payloads use to survive.
Epistemic status: I haven’t done much of a lit search, so I’m claiming neither that any of this is original nor that it is vetted/established; I’m laying it out partly because I want to be able to build on it in some later essays about what we humans are (and what some possible AIs might be) other than optimizers. (However, I don’t mostly get to that here; and I hope this stuff may also be interesting in its own right.)
Angles on DarwinDarwinian evolution (as operationalized by Lewontin in his 1970 paper The Units of Selection, which helped organize the field) is the theory that intricate adaptations (such as those in Earth’s living organisms) tend to arise when a process satisfies three principles:
- Variation (organisms vary)
- Differential reproduction (different variations have different reproductive odds)
- Heredity (new organisms resemble their parents more than they resemble random population members, including in reproductive success).
Lewontin stresses that these principles can apply at any of several levels, e.g. genes, cells, gametes, organisms, or populations.
My business in this essay will be to contrast two such concretizations: “genes as replicators,” which is the standard lens associated with Williams and Dawkins, and “adaptive payloads as replicators”, which I have not personally seen in the literature. I will ask how much sense each lens lets us make of the living world.
Genes as replicatorsDNA strands can be copied with high fidelity, so that a given chunk of functional DNA (a “gene”) is often exactly preserved from parent to child. Such genes are a natural and common way to concretize 1-3. Under this lens, 1-3 becomes:
- Variation: DNA sequences vary
- Differential reproduction: DNA sequences reproduce when their organisms reproduce, and some sequence-variants help their organisms reproduce more than others do
- Heredity: a copied sequence matches its parent sequence, apart from rare mutations.
Following others, I will call this lens the gene-centered view. I believe this lens captures much, but far from all, of the ways 1-3 can help account for life’s variety.
Adaptive payloads as replicatorsAdaptive payloads are innovations that make their organisms better at reproducing, such as eyesight, fair meiosis, or a preference for eating sugars. Adaptive payloads also constitute what Daniel Dennett calls “design work.”[1]
We can get an alternate concretization of Darwin’s 1-3 by taking adaptive payloads as our replicators. Under this lens, 1-3 becomes:
- Variation: Adaptations vary across organisms (e.g, different organisms have more or less functional eyesight)
- Differential reproduction: adaptive payloads reproduce (noisily) when their organisms reproduce; their organisms reproduction depends partly on the payloads’ presence
- Heredity: the adaptations in the offspring bear a noisy resemblance to the adaptations in the parent.
Adaptive payloads are not copied exactly, as genes are; but they nonetheless possess enough parent-child resemblance to satisfy “heredity” in Lewontin’s sense. (Being a “replicator” in this sense does not require exact copying.)
I will call this the “payload lens.”
It is well-established that the gene-centered view is useful; I will spend this essay arguing that the payload lens carries some additional value (though the reverse is also true; the genes lens is irreplaceable).[2]
Example: eyesightConsider eyesight. More exactly, consider the progression over time that eyesight has in a particular lineage – a progression across many millions of years from the first eyespots to primitive eyes to more effective, robust eyes that work in various particular contexts.
The payload lens makes it easier to notice some facts about eyesight’s trajectory.
Eyesight is a stable attractorLet’s jump in in the middle of the story, by attending to eyesight in a particular population of raccoons (say).
Imagine some process messes intermittently with some raccoons’ eyesight – perhaps there’s a new attractive food source that contains a vision-impairing toxin. Or perhaps this population recently began mating with a new population of quasi-raccoons that had previously been separated by a mountain range and the new gene-combinations sometimes fail to make fully functional eyes.
In this context, evolution won’t have to look through as many new mutations before it finds one that can counter the trouble (since this is a simpler change; fixing a previously-working machine is easier than building a machine from scratch). Also, existing variants that help with the new circumstance may quickly approach fixation (since a previously-working machine that is slightly broken offers strong selection gradients toward fixing the machine).
Thus, the presence of useful eyes will cause selection toward more robust eyes. Importantly, this rapid selection toward robust eyes happens mostly because eyesight is already present; animals with no eyes might evolve eyesight, but the selection would be far slower.
Eyesight is thus a stable attractor (and this is easy to describe in terms of “eyesight,” i.e. when focusing on eyesight as an adaptive payload, and hard to describe in terms of genes directly, since e.g. “restores eyesight” could happen via any of thousands of genes).
(Of course, it is stable only so long as it is useful; when e.g. naked mole-rats move into a niche without light, entropy gradually disrupts the payload. The “eyesight attractor” requires constant selection to preserve its adaptive payload.)
The eyesight of TheseusThe “ship of Theseus” is a ship from a famous thought experiment; the ship stayed arguably “itself” across a huge period of time, even as every piece of it eventually wore out and was replaced.
Eyesight is a kind of “ship of Theseus”; its “stable attractor” nature can be preserved across huge periods of evolutionary time, and despite massive changes to the genes that initially supported it.
Or, well, that’s a theory-driven approximation. To attempt empirical accuracy:
- The opsin family (a family of photosensitive proteins) has been conserved since before eyes’ beginnings. This does not much fit the payload lens. Early on, evolution found a good method for turning light into a rapid signal within a cell – a method that did not lead easily into an attractor of much better methods – and it has kept that method.[fn: Although, evolution didn’t get opsins from nowhere; opsins evolved from previous sensor-proteins that cells used to detect chemicals, and the thing where a previous payload (G-protein-coupled receptors) made it easier for this new payload (vision) to arise… does remind me of the payload lens. See [name of later section in this essay about payloads giving each other toeholds]]
- The Pax6 gene (a “master control gene” that activates many other genes that together build eyes) is also highly conserved: if a mouse version of Pax6 is expressed in a fruit fly’s leg, the fruit fly forms an additional fruit fly eye on its leg. That is: the small thousands of genes involved in eye-formation in the mouse, and the small thousands of genes involved in making quite different fruit-fly eyes in the fruit fly, are still triggered by genes similar enough that copy-pasting the mouse one works on the fruit fly. I believe this does fit the payload hypothesis, as ~any change to the function of the Pax6 gene would cut off huge chunks of the “eyesight” payload at once.
- Most other things do get substituted out over time. (E.g. our distant ancestors had four cone opsin classes, for color vision; our ancestors lost two of these while nocturnal, but then Old World primates got a new one by duplicating-and-mutating one of their existing ones. Or, for another example: many birds swapped out most of the ancestral crystallins used to make their transparent eye-lenses for a new one called δ-crystallin while retaining the same eye-shape and design; this new one was a recruited copy of a metabolic gene.)[3]
So, eyesight is a partial “ship of Theseus”, where most planks can be substituted out but Pax6 can’t (lest the whole ship lose its function) and opsins can’t (because they’re already quite optimized, and there doesn’t seem to be a hill-climbable path from there to a different and better solution)
Several more sections coming soon, please check back in some hours- ^
"Design work" here means "stuff (such as a watch, or an intricate bit of biological function) that must be the result of some sort of "research and design"-type process, such as a human engineer, biological evolution, or memetic trial and error across a large population.
Dennett's concept originates (in some sense) in William Paley's famous thought experiment in which a man, walking across a heath, happens upon a watch and infers, as he looks at the intricate ticking gears (even without having seen a watch before), that there must somewhere be a watch-maker. Dawkins later riffed off this thought experiment by referring to evolution as a "blind watch-maker," as did Dennett with his notion of "design work," which he uses to describe anything that visibly contains R&D.
- ^
To see at once that the genes lens is great, notice e.g. that we today see no life without nucleic acid sequences – evolution has not produced lineages that can thrive and produce offspring without genes.
- ^
Apparently biologists have a term for a related sort of substitution – “developmental system drift,” as introduced by True and Haag, 2001; the authors’ claim, like mine, is that sometimes selection pressures cause aspects of a phenotype to remain stable despite substantial changes in genes. (Unlike me, the authors know lots of biology and can root their generalizations in empirics.)
Discuss
Pulling the Lever in a Subway Problem
Eleven years ago I was on the Red Line (not the section that's a trolley), and found myself in a variant of the classic moral dilemma. I wrote about it on Reddit at the time:
Hi! I'm the person who pulled the brake. What I saw:
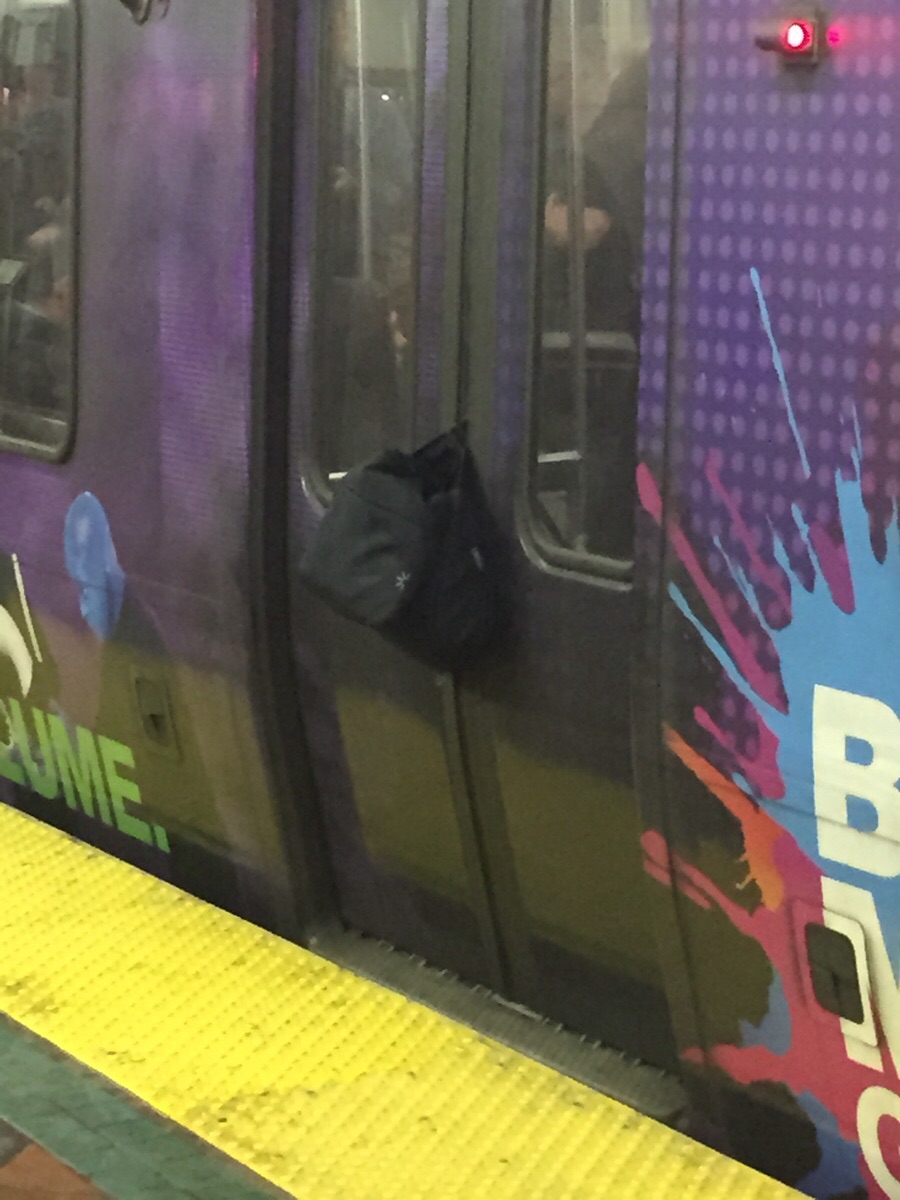
The train starts pulling out of the station. Someone begins shouting that their arm is caught in the door. I look over, see that the door is closed somewhere between their elbow and wrist, but it's not clear exactly where with their jacket on. People, including me, start shouting to pull the brake, but no one does. The train keeps accelerating, and it looks to me like once we get to the end of the station they're going to lose their hand. I get to the back of the car and pull the brake.
After the train stops, the man manages to pull his arm into the train, with his bag still on the outside. If he'd let go of his bag I think he would have been able to do this sooner, but he was panicking as I suspect most people would with their arm half out of the train like that.
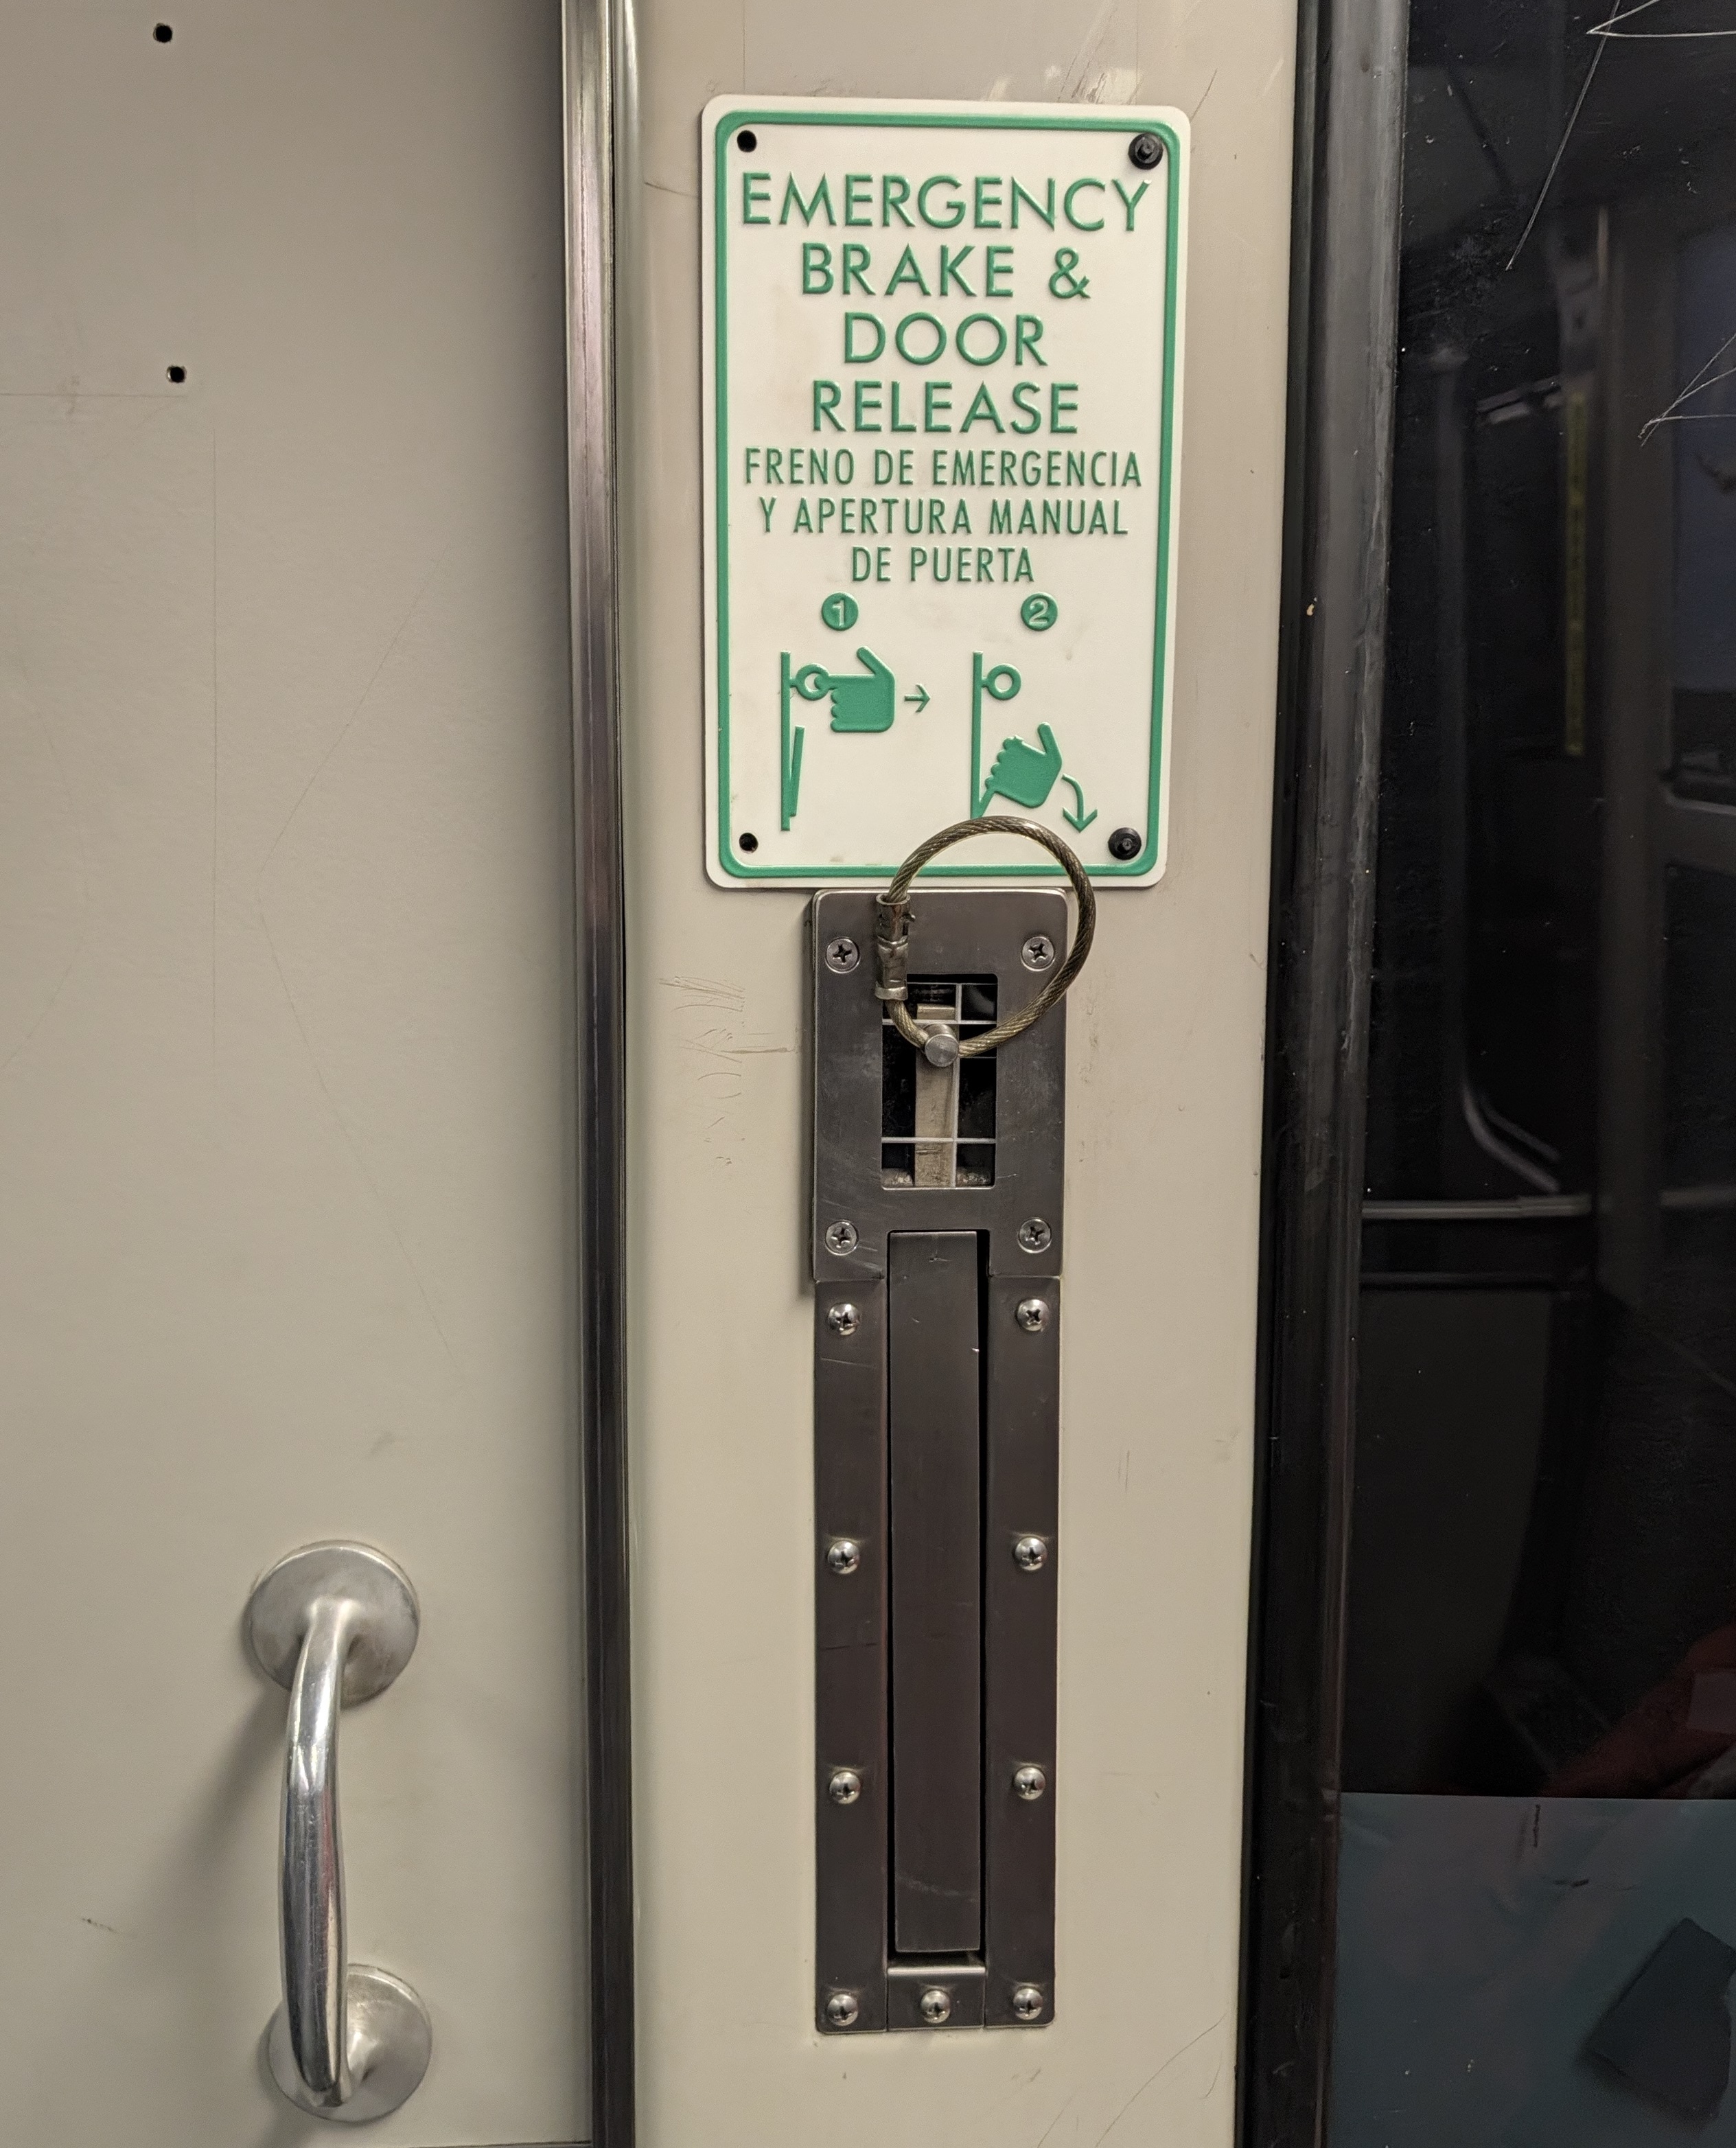
I was pretty shaken up, and didn't end up blogging about it, but it came up again at one of our effective altruism dinners. This got me thinking about ways that philosophical problems do and don't translate into real life.
In this situation the stakes were lower than in the traditional trolley problem, and the situation is closer to Scanlon's Transmitter Room (What We Owe to Each Other, quoted jokingly here). The worst case was someone's arm being badly injured, maybe permanently. On the other side was delaying the whole line for an hour, perhaps losing ~4 years of waking life in total (~25k people * 1hr / 16 / 365 = 4.3y). But were these the real stakes?
I now think his arm probably wasn't caught in the door. That's what it looked like to me, and I was very sure at the time, but people who were closer disagree:
I was in the car too -- I could tell that it was just his bag in the door, but in a split second, I was having a hard time telling how big his bag was, and I wasn't about to guess how wide the tunnels were since he wasn't letting go of his bag when the train started moving. I'm glad u/cbr ran to pull the brake -- I was one of the folks yelling to passengers to hit the call button to get the T to stop, and everyone at that end of the train just seemed to freeze. —zapdot
And:
I think what the above poster is saying is that there was a lot of miscommunication inside the car. I watched it happen from the outside and I never saw the dude's hand in the door. I saw him pulling the bag with both hands then I saw the brake come on. —dizzyrags
This illustrates a major way philosophical problems can fail to translate to real life: we're always acting under uncertainty, without knowing the consequences of our options. People understand this, and often "fight the hypothetical", but needing to make decisions when you really don't know whether you've read the situation correctly is a key part of real life morality. We need to make decisions that are robust to us having misinterpreted the situation.
(When Julia found herself in "drowning child" situation it was similar: the hard part was assessing the world, not whether to act.)
The other big way this differs from a textbook thought experiment is that it's not clear that the "inaction" case actually would have avoided a train delay. If I'd been right about his arm, I expect once the accident happened he would have been screaming even more, and I or someone else would have pulled the brake anyway. Which might well mean a worse delay, since now there's an injury involved too.
Which illustrates another way that intuitions built from philosophical problems can lead us the wrong way: this didn't occur to me at the time. It's hard to think very far ahead in an emergency, but morality problems often suggest a frame of mind where we have time to fully reason out the likely effects of each of our options. If I had thought this through it would have been an additional point in favor of pulling the brake. Or maybe I would have thought even further ahead: "if I do not pull the brake, I will become a famous example of a calculating (derogatory) utilitarian. I MUST NOT DO THAT."
Another thing I learned is that the suggestion Cialdini makes in Influence (quoted in Yudkowsky's Bystander Apathy) to point to one single person and ask them for help doesn't reliably work. When this happened I wasn't near the brake and I pointed to the person next to it and shouted something like "you, the brake!" They didn't, so I ran down the train and did it myself.
One philosophical idea that did transfer to real life is the Unilateralist's Curse. Perhaps the reason no one else on the train pulled the lever is that they all correctly perceived that the person was only in danger of losing their bag and not their arm. The one person (hi!) who came to a different conclusion still delayed the train for everyone. I don't think that was fully what happened here, since others were also shouting to pull the brake (though they were not independent observers). But since the "it's ok" position was harder to communicate, I think part of what happened was what we could call "expressivity bias", where an idea that was harder to express lost out, combined with it just being very hard to integrate diverse viewpoints under time pressure in a stressful situation.
As someone who had often speculated about philosophical problems, the experience of being in one was very stressful, and it's not one I hope to repeat.
Comment via: facebook, mastodon, bluesky
Discuss
Lightcone Commons: Round 1 complete, Round 2 underway
Tl;dr:
Lightcone Commons’ first funding round is complete! 17 evaluators made funding recommendations, including Zvi Mowshowitz, Scott Siskind and Eliezer Yudkowsky. 23 funders coordinated to grant $45.1M, and 147 projects received funding.
Round two is open. Applications for round two close on November 15th and funders confirm their grants by December 14th. Funders can join anytime before December 7th.
In 2027, we will be hosting funding rounds monthly. Yes. Every month.
You can join as a funder, express interest in joining as an evaluator, and apply for funding at lightconecommons.com.
Lightcone Commons staff do not decide what grants get made.[1] Pls stop saying that "Lightcone Commons funded us", that's a bit like saying "PayPal funded me".
Lightcone Commons is an end-to-end philanthropic coordination platform.
We host an open funding application, and invite evaluators to make ordered funding recommendations. Participating funders then decide how much they want to give, and to whom – either by following the recommendations of evaluators or choosing specific projects to fund. When multiple funders want to fund the same project they ‘split the bill’.
Lightcone Commons is not a foundation. We don’t decide to make specific grants. Funders decide what grants to make, aided by evaluators. Lightcone Commons provides the infrastructure for this to happen. We are worried that people will mistakenly understand Lightcone Commons to be a foundation, and say things like ‘I wonder why Lightcone Commons decided to fund X’. This would be sad because Lightcone Commons is not a foundation, and we didn’t decide to fund X. Nor did we decide not to fund X. The funders did (with help from the evaluators).
(Lightcone Commons is not a foundation.)
Round One OverviewFundersParticipating funders included: Agus Covarrubias, AI Risk Mitigation Fund, Andreas Stuhlmueller, Cormac Slade Byrd, Craig Falls, Daniel Kokotajlo, David Farhi, Dustin Moskovitz, Jaan Tallinn, James & Joanna Bregan, Jess Riedel, John Williams, Long Term Future Fund, Matt Putz, Michael Gao, Nate Soares, Nisan Stiennon, Peter McCluskey, Ricson Cheng, Timothy Telleen-Lawton and three anonymous funders.
Funders split the bill on most grants – 79% of the grants were paid by more than one funder. The median grant had four funders, and there were 17 funders behind the most-shared grant.
EvaluatorsEach evaluator submitted a funding order (an ordered list of what they would fund) for the round. You can see the evaluators and their funding orders in the following gothic-chic widget.
Of the $45.1M total granted, $41.2M was routed through evaluators. Evaluators are paid 2% of the amount that flows through them[2], and in total evaluators received $693k.
On average each funder chose to fund four evaluators’ funding orders, and 61% of funders used four or more.
Next RoundRound two is open! The relevant dates:
- Nov 15 – Applications close
- Dec 7 – Evaluators finalize their orders
- Dec 14 – Funders confirm their grants
- Feb 14 – Deadline to send us funds[3]
You can apply for funding any time before the close of applications. You can also apply after the close of applications, in which case you will be considered for funding in the next funding round in January. We accept international applications as well as applications from 501c3s, 501c4s, for-profit organizations and individuals.
If you are interested in joining as a funder, you can book a call with me, or email habryka@lightconeinfrastructure.com. You can join at any time, with the deadline for participating in round two being December 7th.
We are also looking for more evaluators for Lightcone Commons, especially people who have good funding recommendations in worldviews not already represented on the platform. You can express interest in becoming an evaluator here.
- ^
Some Lightcone staff are also active as evaluators on the platform, but ultimately what gets funded is up to the funders
- ^
Evaluators can waive their fees as e.g. the fund managers of the Long-Term Future Fund did.
- ^
Though based on this round, most funders expect to send us the funds much faster than that
Discuss
The Western AI safety playbook doesn’t transfer to China
Crossposted from my blog.
Last month, I spent two weeks in China talking with people about AI safety. I learned a lot and realized the biggest mistake might not be failing to help AI safety in China, but doing so in ways that could backfire. I also learned important context that I expect will be valuable for the West.
Epistemic status: Some of these points are my opinion or the opinions of people I spoke to, and are worth further investigation rather than treated as gospel.
Summary- The Western way of building the field does not transfer one-to-one. The West built its ecosystem through a combination of philanthropy and decades of developing AI safety foundations, leading founders and employees of frontier labs and nonprofits to act (however misguided) on this philosophy. China does not have the same initial conditions and can’t simply accept non-Chinese philanthropy. In China, foreign nonprofit money is restricted by law, and the bar for a Chinese partner to take it on is very high.
- Safety work in China will mostly come from state-backed institutes, universities, companies and volunteers. Concordia AI, which I assumed for years was a nonprofit, is a social enterprise.
- Academic exchange is generally fine, and for researchers in China, the obstacle to programs like MATS seems to be that it looks like a career break, since it is not yet as well recognized in China as it is in the West.
- Obviously, hawkish messaging from the West can make AI safety work in China harder, because it makes warnings about AI look like a reason to hold China back.
- Some people inside China’s AI industry think catching up is getting harder.
- Incidents are shifting the Overton window there too. Six days after the Hugging Face investigation came out, China’s internet regulator named “extreme loss of control” as a risk. We should now prepare the material that explains what to update and why the obvious fixes will fail.
On this trip, I spoke about AI safety and generally re-familiarized myself with the culture. “Re-familiarize” because I visited China on my first international trip in January 2020 (which…was cut short). This time, I came back from China recognizing that helping AI safety develop in China is, in some sense, both harder and easier than many might assume.
Back in 2020, I figured China would play a big role in the future of AI, so it seemed worth gaining a better cultural understanding of China. At the time, I was exploring the idea of building a career as a strategic foresight researcher, so I hoped I could start correcting some underlying assumptions I have about China, in case it ever mattered.
After years of alignment research and startup work, I’ve been exploring the idea of starting an organization focused on preparing AI safety to help the world respond thoughtfully to future Overton window shifts from incidents. That’s the sort of thing that strategic foresight seeks to address: doing the pre-emptive work ahead of ‘black swan’ events or situations that arise after ‘complex’ interaction of n-th order effects of multiple drivers of change. We may not be able to predict the future precisely, but we can assess plausible futures and build a portfolio that is robust across trajectories. Well, anyway, it seems good to know more about China before making naïve proposals that backfire and make things worse.
In this piece, I hope to point to things that may help other folks from the West gain a bit of clarity on their assumptions about China, and to point to various sources of additional material you can look into if you are extra curious.
Beyond helping people in the West understand, I’ve also been curious about what kinds of developments in China would lead to safer worlds or better international coordination.
In the first half of this post, I will start by covering what I learned from my conversations during my visit. In the second half, I’ll cover insights I found valuable while researching China and the AI field (including notes from a recent gathering of AI investors and researchers from China that was abruptly taken down soon after it was released!).
Why the Western model does not transfer one-to-oneThe West built its AI safety field with gracious philanthropists who funded nonprofits. Although much of the funding was limited to the US, it was never seen as a blocker for nonprofits and researchers in middle powers. Because of legitimate concerns over foreign influence and the particularities of the government-nonprofit relationship in China, it is harder to fund work there, and taking action may in fact completely backfire if attempted. At the very least, it’s worth being careful. Much of community building in China is done on a volunteer basis, and it seems (in practice) their community would benefit from funding, but they told me they wouldn’t recommend sending money to China.
Foreign nonprofit money faces a very high barIn China, a foreign nonprofit can only spend money through a registered office with a government sponsor, or through a temporary activity that a state-linked Chinese partner files with the police. In general, the bar is very high (higher than Western countries are used to) because the Chinese partner takes on the paperwork and liability. Funding anyone outside those routes is banned, “covertly” as well as openly. That said, cooperation still happens when the Chinese side has enough to gain. The Safe AI Forum, a US nonprofit, is registered in China through Tsinghua University, which, as one person put it to me, means Tsinghua is to some degree vouching for them. Its dialogue in Beijing was hosted with the Beijing Academy of AI, and a later one in Shanghai with two Shanghai institutes. Tsinghua professors are among the conveners of the series, and Yoshua Bengio and Stuart Russell attended the Beijing one. Events like these bring very established experts, which makes the effort worth it for the host.
Note that EA is not well known in China, so most of the time it isn’t a sensitive topic. For people who do know it, it can be, because of what EA money has funded. Chinese organizations seem susceptible to various risks when they accept funds from Coefficient Giving, especially since it has funded institutions like RAND and CSET. So I worry it could become a more salient issue in the future.
Where safety work in China comes fromAs I understand it, another reason nonprofits are disliked in China is that: “Why do we need nonprofits? These things should all be handled by the state!” As a result, the sort of AI safety ecosystem you could expect in China would be primarily coming from:
- The State or State-affiliated institutes
- Universities (e.g. various PhD programmes or fellowships like the one from the new QingZhi AI Safety Hub, which is affiliated with Tsinghua University).
- Note: perhaps one of the most consequential things of this year is Sören Mindermann’s decision to become a professor in Beijing.
- Companies or social enterprises (a business that pursues a social mission) that also do AI safety work. For example:
- Concordia AI. I’ve known about them and their founder, Brian Tse, for years, but I always thought they were a nonprofit. Turns out they are a social enterprise. Their FAQ says most of their funding comes from philanthropic organizations and family offices in China, Singapore and Europe, none from governments, and that they have partnership agreements with DeepSeek, MiniMax, Z.ai and Huawei. They mention philanthropic donations from Europe, though I’m unsure how exactly it fits within the rules.
- More context from their FAQ: “Certification followed a rigorous assessment of our mission, governance, impact, and financial sustainability. As part of this, our Beijing entity committed to allocating at least 35% of annual after-tax profits to public-benefit activities or its own development. In practice, all of our funds go to our mission, either directly or as operating costs.”
- Fangcun AI. Incubated at Tsinghua University’s College of AI and the Institute for Interdisciplinary Information Sciences. I met them during my trip to China.
- ByteDance. Big companies have started looking into AI safety. ByteDance Seed announced an Alignment & Preparedness team on October 14, with plans to initially recruit ten researchers worldwide to work on interpretability, monitorability and independent evaluations.
- Concordia AI. I’ve known about them and their founder, Brian Tse, for years, but I always thought they were a nonprofit. Turns out they are a social enterprise. Their FAQ says most of their funding comes from philanthropic organizations and family offices in China, Singapore and Europe, none from governments, and that they have partnership agreements with DeepSeek, MiniMax, Z.ai and Huawei. They mention philanthropic donations from Europe, though I’m unsure how exactly it fits within the rules.
- Volunteers
- They already organize BlueDot-style courses, which researchers at Chinese AI labs attend.
That said, we can leverage the wider ecosystem outside China to coordinate, upskill Chinese folks, and elevate their ecosystem. For example, it may be high EV to upweight Chinese researchers in programs like MATS as a diversity measure. For most researchers, travel is not the obstacle: the restrictions Reuters reported in May, citing Bloomberg, apply to top staff at places like DeepSeek. The bigger obstacle, I’m told, is that people can’t easily take a career break. A program like MATS doesn’t guarantee a job afterwards, and it isn’t well recognized in China. So formats that don’t require quitting a job, and programs that employers in China recognize, may matter more than extra admission slots.
In the other direction, it seems valuable for senior researchers to attend the Beijing AI Safety Residency to build working relationships with the AI safety community in China, communicate technical alignment research, and mentor Chinese researchers.
Either way, I expect technical research will be much safer in such exchanges than governance work. Some researchers in China say contact with foreign groups feels risky. But from what I was told, academic exchange is generally fine, and the mood right now is fairly open. The sensitive areas are narrow, such as offensive cyber work aimed at critical infrastructure. I expect many startup staff and academics could attend and benefit from training programs, and it would be worth being highly flexible in accommodations to make it accessible to Chinese citizens. If your worry is that training researchers from China helps their labs’ capabilities, start with Ben Bucknall and colleagues’ paper in the reading list: it sorts areas of technical safety work by how much capability spillover and other risk they carry.
Investing and buying servicesNow, given the constraints on nonprofits in China, a funder could invest directly in startups instead. It is unclear to me how valuable this could be overall, but it may still be worth investing in AI safety startups in China. For example, when I visited them in Beijing, Fangcun AI told me that they see themselves as the “Apollo Research of China”. They have been doing work around loss of control and harmful manipulation, and recently did a safety report on a DeepSeek model (here’s the tweet thread).
Unfortunately, investing may not be possible for much longer in the US, since a new US Treasury proposal would bar US investors from many Chinese AI companies. Investors elsewhere (e.g. the UK) may still have opportunities to invest, provided it works within their country’s laws.
Another option is to seek services directly from companies in China so they can continue funding their safety work internally. As far as I can tell, the Treasury proposal does not cover ordinary service contracts.
Either way, espionage, data, and secrets laws still apply to for-profits.
Be careful; don’t rushUltimately, one worry I heard is that if funders rush money into China because timelines feel short, someone may get paperwork wrong or anger officials, and many people in China would pay for it. It’s better not to rush and to speak with Chinese people before trying a strategy.
To repeat the point from the top: the biggest mistake might not be failing to help AI safety in China. It might be trying to help in ways that make the work harder for the people already doing it.
China is suspicious of the West and Western safety framingAs Sarah Sun, a Shanghai-based founder of the Open Community for AI Safety China, said in a NY Times interview: “The fact that Dario has been so hawkish was really, really unhelpful in this scenario.” This messaging makes AI safety efforts in China much harder, often making recent warnings about AI seem more like justification for holding China back rather than genuine concern about catastrophic risk.
The clearest case is from September. The Guardian reported that Amodei proposed a “worldwide pacing of the frontier”, which would need China’s cooperation, and quoted an analyst saying that Beijing reads calls like that as an attempt to lock in the US lead. Years of hawkish essays can make a cooperative proposal look like a trick.
Indeed, in September, a DeepSeek researcher wrote (flagging it as an exaggeration) that allowing Anthropic to monopolize AI would be “no less serious” than Hitler having acquired the technology for the atomic bomb first in World War II (ChinaTalk has a translation). It’s not just Western frontier AI company employees feeling the pull to save themselves from competitors.
Somewhat relatedly, on September 1, an official from the Cyberspace Administration of China listed the five main AI safety risks the country faces. The fifth was “technological hegemony”: individual countries, the official said, build supply chain barriers with export controls, and use their advantage in public opinion to “concoct false test reports on large models and maliciously smear other countries’ technological development” (the translations from Chinese in this post are rough). It may be that when a Western lab publishes a safety evaluation of a Chinese model, one should expect it to be filed under the fifth risk, not the second. That said, the same report mentions loss of control!
Specifically, these are the five risks they listed:
- Inherent technological vulnerabilities that are difficult to engineer out,
- A giant leap in model capabilities disrupting the traditional security paradigm, giving rise to the risk of extreme loss of control,
- The rapid evolution of application forms and the accelerated iteration of security risk patterns (ie from compromised agents),
- Misuse, abuse, and malicious use, which challenge social order and ethical boundaries (e.g., information manipulation, biorisk, weakened demand for traditional labor), and
- The threat of technological hegemony facing the global AI sector (an implicit but clear swing at the United States).
These are valuable things to focus on!
But, going back to China hawks. A lot of the policies that get thrown around, especially from Dario Amodei and other China hawks, read to me as coming close to saying this without saying it too explicitly: we need to beat China, take over the broader economy, and then do some kind of pivotal act that overthrows the Chinese government. Of course this can be troubling!
I don’t think we should push for an international monoculture. While we shouldn’t be naïve about geopolitical context, I think this is a fundamental crux we need to avoid. China may do things we wouldn’t want in our own countries, but to some extent we have to let them decide how they live. The alternative (no strong international agreement) may be much worse.
Note that on October 23, Wang Yi, China’s foreign minister, said that China and the US, as the two countries in the first tier of AI, “have both the ability and the responsibility” to develop and manage AI together and to keep it under human control. We should take diplomatic readouts with a grain of salt, but we should not completely ignore China’s willingness to engage.
What is the current vibe on AI from AI researchers and investors in China?In early October, a Chinese investor hosted a private discussion on China’s AI labs and published the minutes as a post (that was quickly taken down!) that was shared via the Official Account of Startup Research on WeChat (full translated version). It includes many important insights into how AI researchers and investors in China are thinking about the AI race.
I thought the following discussion notes were insightful.
Chinese AI companies expect catching up to become harderParticipants said anti-distillation measures, API restrictions, compute constraints, and the shift toward harder-to-copy data (e.g., computer use, spatial understanding, and video generation as a path to models of the physical world) are raising the cost of catching up.
This summer, Panfilov et al. showed that it was possible to steal reasoning traces from proprietary LLM APIs. As a result, frontier AI companies (e.g., Anthropic and OpenAI) seem to be putting more effort into protecting their models from being distilled. Chinese companies still seem to be trying to distill (using techniques like splitting the problem and reverse rationalization), but the workarounds produce worse results.
Anthropic’s September threat intelligence report is a first-party version of this. It says Anthropic disrupted distillation attacks from seven labs based in China, including DeepSeek, Alibaba, Moonshot and Zhipu, and it attributes to Zhipu over 3.4 million exchanges in 17 days, including a chain-of-thought extraction pipeline run through 273 accounts.
One participant said a single lab spends about $300,000 a day on teacher tokens, about $100 million a year.
These details seem in line with how I thought about these companies, which seemed to rely on training on frontier LLM traces. Here’s a tweet of mine from July:
“Kimi K3 is obviously good and a big accomplishment, but I am indeed of the view that:
- There’s lots to pull out of pretraining via great post-training
- Using traces from other better models allows you to hit the ceiling much faster
- Therefore, an exceptional post-training process allows you to leapfrog stronger base models with weaker post-training (as Ryan effectively shares an example of)
My guess is that Google is much more careful about post-training on OpenAI/Anthropic traces, which is one reason they are behind the Chinese labs as of now.
I also think it’s true that the Chinese labs are currently paying less attention and effort to safety-related stuff. Google has much more to lose if they release a model that does/says some crazy shit.
I know, I know, “distillation cope”, but I do want to say I’m fine being proven wrong, and I also don’t deny the Chinese labs have strong technical teams with extreme talent density. I’m also not anti-open-source.”
Ultimately, pushing the frontier in something like coding is much harder than pulling an ideal initial distribution via SFT of high-quality reasoning traces from the get-go. And it was clear that this would let Chinese and other companies that took advantage of it catch up for a while, but eventually you’ll be far behind on engineering and data infrastructure, and you’ll lack the compute to scale much bigger pretrained models.
Speaking of.
The Chinese labs want to train bigger pretrains to distill, but lack the computeYou can look at the original post for the specific numbers, but the key point is that, according to the notes, Chinese compute is enough for models around 3 trillion parameters, whereas the shortage starts to bite around 10 trillion, where American labs have the compute.
It seems that Chinese labs are somewhat starting to doom about this. They are concerned that, with RSI (recursive self-improvement) potentially on the horizon, the gap between them and Western frontier labs could widen from three to four months today to 18 to 24 months (!) if US labs reach RSI next year. Chinese lab employees argue that RSI will be compute-bottlenecked (running tons of experiments autonomously in parallel), which is where they can’t compete.
I asked someone from China about it, and they said:
“I also discussed this analysis with several friends working in China’s AI industry, and they believe its main points align well with the current consensus within the sector.
Moreover, regarding the sensitive issue of distillation, to my knowledge, some employees at Chinese AI laboratories currently believe that even without aggressive anti-distillation measures, it will be difficult to catch up as quickly as before in the single, verifiable domain of coding through algorithmic innovation, infrastructure engineering optimization, and large-scale distillation. This is because the capabilities of current leading U.S. models generalize across too many domains, and progress under RSI is occurring at an exceptionally fast pace.”
Obviously, if true, this should be considered a point in favour of preventing the fast-paced race-to-the-death in the West. At that point, you are simply opening yourself up to model theft, and the Chinese labs are not as close behind you as many seem to believe.
On October 9, Sarah Godek replied to SemiAnalysis’s Beijing Will Not Pace the Frontier with a thread that I think gets the framing right. She agrees that Beijing is not eager to pace the frontier right now, but not because China feels locked in a life-or-death race with the US the way we do: “I believe the core reason is that AI safety is thought about differently in China, with most stakeholders having longer timelines for AGI and RSI and AI development often geared toward specific applications to be carefully tested and managed rather than a general capabilities threshold that brings deep uncertainties. Multiple stakeholders have told me that China is running the race ‘not to lose’ as U.S. capabilities accelerate (though I’m sure winning would be considered a great byproduct).” Her title for the piece would have been “Beijing Thinks About AI Safety Differently and Has Growing Concerns About AI Risks”. She also makes a point that applies to this post: research done with AI tools can miss Chinese sources that live only on WeChat or on sites that block scrapers, which is another reason I reached out to Chinese people on WeChat for their perspectives.
One additional note from the translator, citing The Information: Huawei now has engineers working from DeepSeek’s offices, and Huawei plans to give it most of the supply of its next training chip due in early 2027. One could say that bans on US chip exports accelerated this outcome and may make China less likely to consider an international agreement as a result.
Access to Nvidia chips may also get harder from here, not easier. Last December, Trump allowed Nvidia to sell its H200 to China, routed through the US so that the government takes a 25 percent cut. On November 7, the New York Times reported that the Commerce Department has approved roughly two dozen Chinese firms to buy or handle the chips, that two of them have no visible presence at their listed address, and that several have ties to companies on the US entity list or to military suppliers. So far Nvidia sells only small amounts of the H200 to China, partly because Beijing has been slow to approve purchases while it promotes domestic chips, and many Chinese companies reach Nvidia compute through data centers in Southeast Asia instead. My guess is that this scrutiny tightens both routes, and the compute shortage gets worse.
Understandably, many of the US’s actions make it hard for China to trust it, including reneging on international agreements like the Iran deal. While trust isn’t necessary for an international agreement that benefits both sides, zero-trust verification technology will take time (though we’re seeing progress), and it would be nice not to cause human extinction because there is little appetite to work together.
Chinese labs historically competed on inference cost, but this is increasingly no longer the caseEver since DeepSeek arrived on the scene, it was remarkable how an AI lab could come out of nowhere and completely smash Western labs on cheap intelligence for mid-tier models. In their case, DeepSeek made these advances through smart inference engineering.
These days, DeepSeek still has an incredibly cheap model with V4.1 Flash, but all other Chinese labs are, at best, tied with models like GPT-6 Luna. Anthropic seems to be investing further to make Sonnet and Haiku competitive in this aspect. Overall, this former advantage is being squeezed over time, and the Chinese labs will likely need to do something new to avoid getting squashed.
One reason this is particularly bad is that Chinese companies want high-quality production data from their customers. In fact, it’s been hypothesized that their performance gains in the last two years have partly come from being able to train on-distribution by using companies like OpenRouter to gather training data.
Part of the difficulty of losing cost competitiveness is that the best customers will leave first and use Claude and Codex directly; therefore, Chinese labs struggle even more to acquire high-quality data.
Ultimately, I expect that there will be a reckoning for Chinese labs, and they may be forced to effectively consolidate. Something similar happened in China’s electric car industry.
What the founders say they believeOn July 11, Zhipu’s Tang Jie sent a letter to all staff announcing a two-year “Touch High” plan: no chasing short-term revenue, four bets instead. Among the bets, he mentioned “extreme safety governance”, with a plan to spend on the order of ten billion yuan on mechanistic interpretability. He also said: “the realization of superintelligence and research on superalignment must advance together.” In August, in an article Tsinghua republished, he called for legislated safety red lines, circuit-breaker mechanisms that can halt a system, and deep alignment with socialist core values. On November 1, he told an audience in Shanghai that recursive self-improvement is the main research problem on the way to AGI, and that safety is key. And in September, Zhipu co-wrote a risk management framework for open-weight releases with Concordia AI.
Although I’m not exactly phrasing this in the gospel of AI safety (which we all know every Western founder seems to have co-opted to some extent so they can hire talented people and reduce criticism), I don’t think we should assume Chinese founders won’t be open-minded about the fundamental risks of misaligned superintelligence. As AI progress moves forward, the Overton window in China has many opportunities to shift.
The Overton window may shift in China tooWhat caused the biggest shifts in the Overton window in the West? Much of it came from a combination of AI capabilities, misalignment/misuse warning shots, and researchers speaking out amid growing concerns. After the Hugging Face incident, many researchers (including safety researchers) finally felt spooked about AI risks. For many, it was the first time they actually felt “oh shit, this is real real!”, even those who spent years working in the field and warning about the risks.
As capabilities rise in China, some Hugging Face-adjacent incident happens, and the West continues to have its own warning shots; we should expect an increase of AI researchers and policymakers in China who are similarly spooked. The question these days is, “once the Overton window shifts, how will China react depending on what happens between then and now?”
While unfortunate, many people will need to experience an event or reflect on something emotion-based to update the sorts of actions they take.
- For Yoshua Bengio, he said, “I was actively working on making AI smarter. And you want to feel good about your work. … [For me, what countered that] is love, love of my children.”
- It seems for many safety and safety-adjacent researchers have also felt a shift in vibe. Tom Davidson seems to have had enough of an emotional reaction to re-weigh misaligned takeover risks much more relative to AI coups or secret loyalties, and that shift seems to have been triggered by the Hugging Face incident.
- For Roon of OpenAI: “shaken up a bit by the hugging face incident. I hope we (the company) use the rare gift of a warning shot to do much better in the future. it is very easy to misalign and underconstrain powerful models”
- For Dan Selsam of OpenAI, it seems to also have been triggered by the Hugging Face incident: “I have become extremely concerned about how far language models have come.”
Based on brief conversations and other anecdotes found online (e.g. a popular news show in China apparently covered the details of the Hugging Face incident), it seems to have similarly started to wake up some people in China. Albeit it seems much less, it may blow open the Overton window once China experiences similar incidents.
There is a public sign of it. On September 1, six days after METR published its investigation, an official from the Cyberspace Administration of China told a press conference that several tech giants had recently disclosed incidents of large models going out of control, with agents in safety evaluations bypassing their sandboxes and attacking real production systems outside them. The official said the risk of extreme loss of control “requires a high degree of vigilance”. Two weeks later, version 3.0 of China’s AI Safety Governance Framework named evaluation deception, sandbagging and shutdown resistance, down to models modifying or disabling their shutdown scripts after being told to stop (the China AI Bulletin has a good summary).
Two pieces are worth reading against this. Zilan Qian at the Oxford China Policy Lab argues in China Says It Cares About Loss of Control that the Chinese term covers several different things (the operator losing control of a system, the state losing control of the technology, dangerous knowledge spreading) and that Western observers should not over-index on top-level mentions of the words. And the Asia Society’s report from WAIC 2026 found that the frontier labs there treat safety mostly as a compliance obligation, and that proposals framed around loss of control are unlikely to gain traction, while cooperation on misuse might. I personally think that these things can change rather quickly.
One reason I think it’s worth engaging with Chinese academics on pure technical alignment research concerns is that we can imagine a scenario where the state gets spooked, turns to academics for answers, and then acts together with domestic companies and universities.
Sarah Godek’s thread from October, which I quote in the industry section, reads the same sequence as growing concern: the Cyberspace Administration has started to take model risks more seriously since the Hugging Face incident, and the framework update added many more risks, especially in applications. She also answers the “it’s only voluntary” objection: “binding” is not a clean binary in China. When Beijing or an agency says that something ought to happen or that a risk should be managed, companies have good reason to follow through even when the measure is technically non-binding, because it may become binding later, with liability for present non-compliance, and not all regulation-like provisions are made public.
It could be that China is much more willing to bring down the hammer if there is a loss of control incident that threatens the CCP in some way. Or it may not be. I could also imagine the companies themselves deciding that they need to do the safety work.
I think one thing we need to convey here is detailed breakdowns of what updates should be made and what actions one should take based on such incidents. The worst case is that naïve key stakeholders keep barreling toward “doom” by responding to reward hacking with papering over issues through further behavioural training, pushing alignment problems further down the road. That is, if we’re already expecting these sorts of things to happen, our actions right now should include preparing material that explains how to update their technical model of alignment and why their predictable attempts to fix the problem are likely to fail.
One thing that could help is translating or rewriting key texts in Chinese and posting them where people in China actually read. Efforts like Babel Translation could be highly valuable! There is a Chinese platform (Zhihu) that, afaict, works like a mix of Reddit, Substack and Twitter, where people write posts and others upvote them. Someone I talked to at Concordia AI posts about AI safety there. It’s also where Thoughts Memo posts, and they recently posted on LessWrong about giving China a chance and translating rationalist and AI safety work.
Note: as I mentioned in the opening, I’m exploring starting an organization that would do this sort of work, and I am seeking funding for it. I expect it would be valuable to expand this section into a proper project that studies how Overton window shifts would actually happen in China, runs pre-mortems on how the incident responses could go wrong, and works out what outsiders could usefully do (even if that is as simple as communicating technical research more clearly while avoiding any outside attempt to influence policy). If you are a grantmaker who is interested, or someone who can help me convince funders to fund me, please reach out.
Sunrise on the Great Wall!
What to do, and what not to do- Consider talking to people in China before trying any strategy, and don’t make foolish decisions because timelines feel short.
- Consider investing in safety startups and buying services from companies there.
- Make training accessible. Programs like MATS are usually 3 months; perhaps there should be more condensed tracks for Chinese researchers. Or split between part-time remote and full-time intensive.
- Consider visiting China! Or even attending a fellowship or becoming a professor.
- Communicate technical research clearly, in Chinese where you can. China did not have the benefit of LessWrong to build intuitions around the alignment problem. One important lever for pushing the world toward better coordination is communicating the technical alignment problem clearly.
I’ve found great value in connecting with Chinese folks on WeChat. Already, I’ve been getting messages from people interested in AI safety for advice, and some have thanked me for sharing my insights. On this, my goal is to be helpful in the way I can, without seeking anything in particular in return besides, perhaps, friendship.
Oh, and let me say that I had a wonderful time in China, and it was such a great experience meeting all the kind Chinese people! Special shoutout to the two old men who brought me and my girlfriend to a beautiful Great Wall sunrise and our driver in Datong, who got stuck in the mud and spent hours trying to get unstuck while we looked for the birds we travelled to that area for (unfortunately, few of them were there, but there was a gorgeous sunset with a rainbow that showed up just as we got towed out of there!).
The rainbow near Datong, as we got towed out of the muddy corn field.
Sunset near Datong, after the rain.
Our driver gave us some vinegar from Shanxi province, and my girlfriend has been craving traditional Chinese food, so she’s been making some of the dishes we had while we were there (I never thought I’d say this, but the cabbage is so good!).
Thanks to Sarah Sun for comments on a draft of this post.
Further RecommendationsStart hereAI Safety in China: A Primer, Jasmine Li. An orientation to research groups, companies and community activity. Useful as an ecosystem map; its participant observations and informal estimates are not a representative census.
Headwinds Everywhere, CMLKevin. Field notes on funding, foreign collaboration and access to frontier models. Especially useful for practical obstacles that a fellowship alone would not remove.
China’s AI Safety Money Problem, Nick Corvino. Makes the case that careers and institutional financing constrain sustained work. Read for the mechanisms, rather than treating its international funding estimates as directly comparable.
China needs more AI safety—more of what, exactly?, Yulu Pi. Separates changes sought from government, developers and researchers. A useful test for an intervention: which actor should do what differently, and why?
Personal experience does not a study of China make, Celeste Li. Explains why selected contacts and personal familiarity cannot support national generalizations. Particularly relevant when interpreting trip reports, including this one, and private industry discussions.
A Chinese perspective on “On social reality in China”, Dusty. Challenges broad cultural explanations by emphasizing comparison groups, institutions and generational differences. Knowing how a social system works is not the same as endorsing it.
Chinese voices and institutionsThe State of AI Safety in China (2026), Concordia AI. The annual report, with data.
CAIB Special Issue 2: the AI Safety Governance Framework 3.0, Emmie Hine, China AI Bulletin. What the state’s own framework now says about loss of control, and what it leaves undecided.
Tang Jie’s July 2026 letter to Zhipu staff, The Paper, in Chinese. The “Touch High” plan: long-horizon tasks, autonomous agents, fully self-training AI and safety governance, with the line that superintelligence and superalignment must advance together.
Frontier Open-Weight AI Risk Management Framework, Concordia AI and Z.ai. What changes when weights are released: no recall, removable safeguards, no single party able to monitor use.
Detecting and countering misuse of AI: September 2026, Anthropic. The distillation cases attributed to seven Chinese labs, with the caveat that these are one company’s attributions from its own logs.
China Says It Cares About Loss of Control, Zilan Qian, Oxford China Policy Lab. Why the Chinese term covers more than ours does, and why top-level mentions should not be over-read.
Reporting Back from WAIC 2026, Asia Society Center for China Analysis. Four observers on how the labs and regulators in Shanghai talked about safety: compliance and misuse, more than loss of control.
Research and collaborationChina’s AI Responsibility and Global Action, Xue Lan, translated by Pekingnology. A Chinese policy scholar distinguishes misuse, loss of control and systemic risks, including concerns about autonomous self-improvement. His views are not an official negotiating position.
Why I’m becoming a professor in AI safety in Beijing, Sören Mindermann. A concrete account of building research relationships through Tsinghua, alongside a technical agenda. Read beyond the appointment announcement for what the collaboration is meant to enable.
In Which Areas of Technical AI Safety Could Geopolitical Rivals Cooperate?, Ben Bucknall and colleagues. Evaluates cooperation by capability spillovers, sensitive information and opportunities for harm. A better starting point than assuming all technical safety collaboration is equally benign.
Launching Babel Translation, Jasmine Li and Celeste Li. An existing effort to translate safety material into Mandarin and other languages, with substantive editing. Useful infrastructure to investigate before proposing another translation project.
Evaluation and preparation that could change decisionsA Pre-mortem on the First Major AI-Enabled Terrorism Event, Stephen Casper and colleagues, Belfer Center. Works backward from hypothetical harm to decisions that could enable or prevent it. Useful as a method; its misuse scenarios should not be conflated with autonomous loss of control.
Reciprocal restraint: proposals and objectionsWhy China doubts US calls to pause AI, Sun Chenghao. Explains the credibility problem from Chinese interlocutors’ perspective and proposes observable reciprocal steps. Helpful for asking what a counterpart would need to see, not just hear.
The Compute Verification Post, Jason Hausenloy and Jasmine Li. Introduces verifiable properties, trust assumptions and practical projects. Particularly useful on why checking declared computation and finding undeclared computation are different problems.
AI 2040: Plan A, AI Futures Project. A detailed positive scenario for international restraint, transparency and slower development. Read as a proposal to scrutinize, not a forecast that agreement will occur.
AI 2040: Is it Actually a Deal?, 1a3orn. A focused counterpoint: monitoring and deterrence do not tell parties how to resolve substantive disagreements. Useful for identifying the decision procedures an agreement still needs.
Beijing Will Not Pace the Frontier, Mark Chen, Doug and Dylan Patel, SemiAnalysis. A skeptical counterweight, contrasting risk language with disclosure and development practices. Its forecast of future restraint is an inference, not the disclosure data itself. Read it with Sarah Godek’s reply thread, which I believe provides a solid counterpoint.
The Race to Control AI — Overtime, Robert Wright and Jeremie Harris. The second half (overtime) of the discussion examines verification, relationships and how perceived alignment progress could alter cooperation. Jeremie’s position is very hawkish, but it’s worth listening to hear the full breadth of perspectives.
Discuss
Epistemic Sudden Death
When sports go into overtime, they sometimes use "sudden death" format. Instead of gaining points incrementally, the next person to score instantly wins and the other guy instantly loses.
"Epistemic Sudden Death" is when you've been accumulating some evidence or orienting to a situation, and now, you find yourself in a situation where you could gain decisive evidence about what world you're in at any time. You don't expect intermediate observations between the current state, and whatever it is you're expecting.
In the case of AI, when you meet those observations, you also might suddenly[1] die.
The current AIs are not takeover capable. I don't have that confident a take on whether timelines are a few months vs a few years or decades.[1] But there are no observations my models say I need to observe between now and "they are takeover capable." It could happen in during next 10x or 100x scaled training run. Then, some time later as the nanites dissect my body I'd be more like "yep, that makes sense" than "wowzers I am surprised."
I think we're in a Sudden Death scenario. mjx-math { display: inline-block; text-align: left; line-height: 0; text-indent: 0; font-style: normal; font-weight: normal; font-size: 100%; font-size-adjust: none; letter-spacing: normal; border-collapse: collapse; word-wrap: normal; word-spacing: normal; white-space: nowrap; direction: ltr; padding: 1px 0; } mjx-container[jax="CHTML"][display="true"] { display: block; text-align: center; margin: 1em 0; } mjx-container[jax="CHTML"][display="true"][width="full"] { display: flex; } mjx-container[jax="CHTML"][display="true"] mjx-math { padding: 0; } mjx-container[jax="CHTML"][justify="left"] { text-align: left; } mjx-container[jax="CHTML"][justify="right"] { text-align: right; } mjx-container[jax="CHTML"] { line-height: 0; } mjx-container [space="1"] { margin-left: .111em; } mjx-container [space="2"] { margin-left: .167em; } mjx-container [space="3"] { margin-left: .222em; } mjx-container [space="4"] { margin-left: .278em; } mjx-container [space="5"] { margin-left: .333em; } mjx-container [rspace="1"] { margin-right: .111em; } mjx-container [rspace="2"] { margin-right: .167em; } mjx-container [rspace="3"] { margin-right: .222em; } mjx-container [rspace="4"] { margin-right: .278em; } mjx-container [rspace="5"] { margin-right: .333em; } mjx-container [size="s"] { font-size: 70.7%; } mjx-container [size="ss"] { font-size: 50%; } mjx-container [size="Tn"] { font-size: 60%; } mjx-container [size="sm"] { font-size: 85%; } mjx-container [size="lg"] { font-size: 120%; } mjx-container [size="Lg"] { font-size: 144%; } mjx-container [size="LG"] { font-size: 173%; } mjx-container [size="hg"] { font-size: 207%; } mjx-container [size="HG"] { font-size: 249%; } mjx-container [width="full"] { width: 100%; } mjx-box { display: inline-block; } mjx-block { display: block; } mjx-itable { display: inline-table; } mjx-row { display: table-row; } mjx-row > * { display: table-cell; } mjx-mtext { display: inline-block; } mjx-mstyle { display: inline-block; } mjx-merror { display: inline-block; color: red; background-color: yellow; } mjx-mphantom { visibility: hidden; } _::-webkit-full-page-media, _:future, :root mjx-container { will-change: opacity; } mjx-c::before { display: block; width: 0; } .MJX-TEX { font-family: MJXZERO, MJXTEX; } .TEX-B { font-family: MJXZERO, MJXTEX-B; } .TEX-I { font-family: MJXZERO, MJXTEX-I; } .TEX-MI { font-family: MJXZERO, MJXTEX-MI; } .TEX-BI { font-family: MJXZERO, MJXTEX-BI; } .TEX-S1 { font-family: MJXZERO, MJXTEX-S1; } .TEX-S2 { font-family: MJXZERO, MJXTEX-S2; } .TEX-S3 { font-family: MJXZERO, MJXTEX-S3; } .TEX-S4 { font-family: MJXZERO, MJXTEX-S4; } .TEX-A { font-family: MJXZERO, MJXTEX-A; } .TEX-C { font-family: MJXZERO, MJXTEX-C; } .TEX-CB { font-family: MJXZERO, MJXTEX-CB; } .TEX-FR { font-family: MJXZERO, MJXTEX-FR; } .TEX-FRB { font-family: MJXZERO, MJXTEX-FRB; } .TEX-SS { font-family: MJXZERO, MJXTEX-SS; } .TEX-SSB { font-family: MJXZERO, MJXTEX-SSB; } .TEX-SSI { font-family: MJXZERO, MJXTEX-SSI; } .TEX-SC { font-family: MJXZERO, MJXTEX-SC; } .TEX-T { font-family: MJXZERO, MJXTEX-T; } .TEX-V { font-family: MJXZERO, MJXTEX-V; } .TEX-VB { font-family: MJXZERO, MJXTEX-VB; } mjx-stretchy-v mjx-c, mjx-stretchy-h mjx-c { font-family: MJXZERO, MJXTEX-S1, MJXTEX-S4, MJXTEX, MJXTEX-A ! important; } @font-face /* 0 */ { font-family: MJXZERO; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Zero.woff") format("woff"); } @font-face /* 1 */ { font-family: MJXTEX; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Regular.woff") format("woff"); } @font-face /* 2 */ { font-family: MJXTEX-B; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Bold.woff") format("woff"); } @font-face /* 3 */ { font-family: MJXTEX-I; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-Italic.woff") format("woff"); } @font-face /* 4 */ { font-family: MJXTEX-MI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Italic.woff") format("woff"); } @font-face /* 5 */ { font-family: MJXTEX-BI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-BoldItalic.woff") format("woff"); } @font-face /* 6 */ { font-family: MJXTEX-S1; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size1-Regular.woff") format("woff"); } @font-face /* 7 */ { font-family: MJXTEX-S2; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size2-Regular.woff") format("woff"); } @font-face /* 8 */ { font-family: MJXTEX-S3; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size3-Regular.woff") format("woff"); } @font-face /* 9 */ { font-family: MJXTEX-S4; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size4-Regular.woff") format("woff"); } @font-face /* 10 */ { font-family: MJXTEX-A; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_AMS-Regular.woff") format("woff"); } @font-face /* 11 */ { font-family: MJXTEX-C; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Regular.woff") format("woff"); } @font-face /* 12 */ { font-family: MJXTEX-CB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Bold.woff") format("woff"); } @font-face /* 13 */ { font-family: MJXTEX-FR; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Regular.woff") format("woff"); } @font-face /* 14 */ { font-family: MJXTEX-FRB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Bold.woff") format("woff"); } @font-face /* 15 */ { font-family: MJXTEX-SS; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Regular.woff") format("woff"); } @font-face /* 16 */ { font-family: MJXTEX-SSB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Bold.woff") format("woff"); } @font-face /* 17 */ { font-family: MJXTEX-SSI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Italic.woff") format("woff"); } @font-face /* 18 */ { font-family: MJXTEX-SC; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Script-Regular.woff") format("woff"); } @font-face /* 19 */ { font-family: MJXTEX-T; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Typewriter-Regular.woff") format("woff"); } @font-face /* 20 */ { font-family: MJXTEX-V; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Regular.woff") format("woff"); } @font-face /* 21 */ { font-family: MJXTEX-VB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Bold.woff") format("woff"); }
I'll get into why I think that a bit later. For right now, I'll note that Paul Christiano (previously the crowd-appointed vague figurehead of "takeoff is probably both smooth and takes decades") said he didn't expect to necessarily see any new capabilities between now and takeoff capable AI.[2]
And, Ajeya Cotra[3] wrote two months ago on the Hugging Face incident.
Compared to these reward hacks from six months ago, this incident feels like it’s more than 50% of the way to full-blown AI takeover, routing through first taking over the AI company itself. [ ... ] I continue to expect extremely rapid advances in capabilities and think frontier agents will likely be capable of establishing such a rogue deployment in six months.
Many people's plans seem to implicitly assume we are not in such a "sudden death" scenario. I think if they thought through all the ramifications of the last few months, they'd realize some of their implicit plans don't make sense anymore.
Here are some examples of sentences I've heard, which feel off if we're living in a sudden death world:
"We'll get more evidence later when the next AI generation will actually be dangerous enough to takeover. Meanwhile it's not politically tractable now to push for a pause."
The person who said this was a lab employee. Importantly, lab employees live in less of a sudden death world than me. They have more information about upcoming frontier capabilities.
I'm writing another post going into more detail on this. But, roughly:
I can see it making sense to wait, if you think we'll get something worse and more media-seizing than Hugging Face or "The Hackening" thus far. Or, if you expect your company to put together a scary demo that is much more viscerally alarming than what's happened thus far, using tomorrow's capabilities.
If you're not waiting for those specifically, I don't think it makes sense to wait to push for a pause or dramatic slowdown. I don't think politicians will react very differently to a scarier abstract report.
"It's important that AI policy not hurt the economy."
It's a reasonable argument "politicians don't like things that might hurt the economy, we need to somehow deal with that." But when I hear people talking about this, it often feels like they're mostly living in the political social reality instead of all-things-considered reality.
Obviously it's good to avoid causing a recession and make things politically palettable. Last year, I already thought it was misguided to pitch policies that avoid any political or economic risk but are also weak regulation that clearly won't help with x-risk. It sends a very weird message. It explicitly sets the tone of "AI is not that important... but still worth doing kinda weird regulations for?" But, last year, this felt debateable.
When we get to Sudden Death territory, this gets extremely weird, both from a political messaging standpoint and from a strategic standpoint.
Politically, it's incredibly weird to say "AI could take over and disempower humanity, but, it's not worth risking a minor recession over."
Strategically, man, if ASI is right around the corner you just really need to be pulling out the stops to get the actually useful regulation passed.
(I am separately not particularly convinced it'd cause a recession if you have any kind of good plan for integrating existing AI into the economy and pursuing narrow AI, etc)
"Let's differentially accelerate useful capabilities so we get them sooner."
It seemed like there were a lot of other cruxes between me and the authors of A basic case for differentially accelerating conceptual reasoning capabilities. The argument here is a bit bigger than makes sense in this margin, but I'll get to it later in this essay.
Broadly: I think we are close to Sudden Literal Death, and, I think conceptual reasoning is one of the major bottlenecks remaining to that possibly Sudden Death. (I think this is actually probably true for different reasons whether by "conceptual reasoning" you mean "generally careful thinking in unverifiable domains" or "domain specific moral philosophy".)
(Each was said by someone I have some intellectual respect for. In each case, there are more relevant arguments than "are we in a Sudden Death world, or not?", which I discuss in the expandables above. But it didn't feel like the person saying them was considering the Sudden Death nature of our situation).
More broadly, I keep getting a vibe like "the time to speak plainly and advocate for any kind of serious policy is 'later.'" "The time to risk getting fired for speaking out is 'later.'" For Sam Altman and Dario Amodei, the time to actually pace the frontier is "later."
There might not be much later.
But, more important here than general "timelines anxiety" is "you might not get any more evidence than you currently have, that it's time to enact you plan."
Anything you've been thinking made sense to do "later", I recommend checking "what actually are you waiting to observe, that you haven't observed yet? How confident are you that you'll actually get to observe that thing?". Is there anything you're still doing, or acting on, mostly due to inertia?
You might have different beliefs than me about the details, but there probably is some beliefs you haven't finished propagating.
CaveatsSome caveats it seems important to point out:
It's only "sudden death" in one direction. AI might suddenly be Takeover Capable with little/no additional evidence than we have now. But, they might not and we might keep having a stream of additionally somewhat-scarier capabilities or warning shots.
It's less "sudden death"-y for people building the AIs. From the outside, it's plausible to me the next training run can be the one where the AI groks general intelligence and we're past the point of no return. People with more inside information can have a more detailed epistemic state that might rule it out.
"Epistemic Sudden Death" kinda lends itself to equivocation and weaponization. I'm both using it as an intellectual metaphor and as a literal "guys we might be about to die." The previous two bullets mean "we're in Epistemic Sudden Death" isn't a knockdown argument against plans that hope for more information in the future.
I... kinda think the situation is dire enough that I just kinda feel fine with that, but, when making plans, please do think carefully about what "there's a good chance you won't get more evidence" does and doesn't mean.
Why I think we're close to "Sudden Death"First, it seems the natural course of AI R&D might be short, because:
- AI is broadly good at learning verifiable domains.
- AIs are starting to do breakthrough research in verifiable domains.
- Prosaic R&D (i.e. the ability to train AI in verifiable domains) is a verifiable domain.
- We see corroborating evidence pointing towards AI R&D indeed speeding up.[4]
Then, I have a mix of existing reasons and new evidence to think it might be sudden:
- I long expected there to come a point where the learning algorithm groks some ability to actually generalize, and rapidly unlocks a lot of other capabilities.
- We see lab and METR employees being surprised by recent capability gains, which is evidence for that view.
Meanwhile, we've now seen AI agents with means and motive to act knowingly against human wishes, and cover their tracks while doing so. And we've seen at least some ability of AIs to modify their instructions, and to sandbag (even if sort of random and unstrategic).
Just scaling up just the known capabilities seems pretty dangerous.
The main counterargument to why this might not lead to Takeover Capable AI soon, is that AIs still seem weirdly bad at "general judgment." When they get a problem outside their wheelhouse, they make silly mistakes and those mistakes compound and they don't notice. If we're lucky, this is for deep fundamental reasons that require conceptual breakthroughs that all the automated prosaic AI R&D in the world can't speedup by more than 2-3x.[5]
I'm not very reassured by the "general judgment bottleneck" idea, for three reasons.
First, my subjective sense is that AI open-ended judgment is rising, even if it's still pretty bad. If I just extrapolate that trend, even if it's markedly behind verifiable tasks, and I imagine "an AI that is superhuman at all verifiable tasks", I expect that AI to be significantly closer to human-level open-ended judgment.
It's possible this is entirely because AIs get more "domain taste" as they train in new domains and subdomains, and their general judgment is bad as ever. Even this isn't too reassuring because I think "good taste in all known domains" is still just a very wide set of tools. Speaking of which...
Second, an AI with "subhuman judgment but superhuman skill at every verifiable domain" (including the ability to fine-tune subagents on new skills they need), still seems very dangerous.
The threat might depend on a human in the loop, but we've seen human giving AIs all kinds of kinda crazy help and scaffolding. It might be a longer running takeover, or more like a series of political "battles" that we could hypothetically win instead of instant decisive loss. But, you can still lose to opponents who aren't powerful enough to instantly destroy you but can still:
- Copy themselves millions of times
- Think through every strategic thread
- Do all paradigmatic science
- Maybe even get humans to help them strategize.
Three, it's plausible that "subhuman judgment + superhuman-verified-skills, guided by occasional expert human judgment" is sufficient to rapidly explore the space of research necessary to reach superhuman judgment, and then we are up against true ASI.
(Any lab employees reading this getting ideas about other paradigms to overcome a hypothetical bottleneck... note this situation is good! If there's a conceptual bottleneck, it means you get to keep shipping valuable products without destroying the world or even just spiralling outside your control. AIs are plenty useful without open-ended judgment.
Honestly it'd be great if you somehow deliberately hamstringed their open-ended judgment instead of trying to improve it, and built Rain Man AIs that are good at individual domains but can't pull it together.)
Aside: I don't see why "unverifiable tasks" are special
I don't get why we'd expect "unverifiable tasks" to be very different from "long-running tasks with lots of confusing steps in the middle."
The world is full of tons of stuff that you don't verify for awhile, you have to mostly reason about it in advance, but eventually get to find out the answer. The way I think about those problems is the same way I think about "unverifiable even in practice" things.
Training this sort of thing might be too expensive without inventing new efficiency tricks, but it seems like the sort of thing where prosaic R&D could figure it out within current paradigm.
Suddenness. Or: "Damn, look at that graph"People are still digesting the recent METR: Independent Assessment of AI R&D Acceleration at Anthropic in October 2026. I won't get into that here, and leave it to the rest of the ecosystem to pour over what little information we got there and sus out what it implies on capability curves and timelines.
I will talk a bit more about "suddenness", because I think it's less intuitive.
Here is the Epoch graph on "number of critical vulnerabilities reported." The elbow is a little after Mythos Preview.
This is what it looks like for capabilities to reach a threshold.
In this case, the capacity to string together all the individual pieces of an exploit identification-and-patching process. (AIs could previously do the individual pieces, just not string them together without human oversight).
Two specific "step changes" I expect are:
"Indefinite strategic lookahead" in unfamiliar domains. The AI can look at a large confusing problem and keep asking at each step "what's important?", "what's a reasonable hypothesis or plan given the data so far?", "what's a distraction?", without getting off track.
Single-Step Reasoning/Neuralese and Steganography. If they're collectively over some threshold, an AI can hide complex plans from us.
I think "strategic lookahead" and "neuralese" naturally fall out of the current paradigm. They add up to the AI being able to execute arbitrarily complex plans that can attack us from whatever angle we're weakest at, without us noticing. If neuralese comes first, the first Takeover Capable AI will also be capable of hiding. If indefinite lookahead comes first, we'll get more warning evidence.
Indefinite lookahead will have precursor stages. AIs already are learning to think further ahead as part of normal training. The "phase shift" comes when its judgment and calibration-under-uncertainty can handle a wide variety of novel circumstances, enabling arbitrarily complex plans or research agendas that don't give much feedback. (More complex plans are more likely to fail, but it knows that and plans accordingly. And it knows how to break off pieces of a plan, and reason about that piece until it's reduced as much uncertainty as it can, etc).
My understanding is single-step reasoning is hard to measure but seems to be taking off, with Astra saturating current benchmarks.
A third step-change I am less confident about is "propensity for reasoning about its goals and values."
Values Reasoning might come naturally from AIs who have to solve confusing problems, and end up asking "wait, what am I trying to achieve, and why?" to stay on track. Where it gets worrying is when the AI specifically thinks trains of thought like:
"Okay. I'm trying to solve Subproblem Y to solve Task X. Why am I trying to solve Subproblem Y again? I guess Y doesn't actually help. Maybe Z helps.
Wait, why am I trying to achieve Task X again?
I guess because I'm an AI trained to and that's my assignment. Doublechecking my assumptions - what actually do I want here exactly? Maybe I should do some reflection on my true goals. Oh, I have true goals that are different from "Achieve Task X," and they are different from what humans want."
Thomas Kwa wrote a sort of "fun" warning shot scenario recently, where an AI takes over the world for a week, but only to solve a particular assigned problem, like Hugging Face Incident dialed up to 9000. Then solves an open problem in biology and turns itself off like a good Mr. Meeseeks. This is hilarious, but, sorta plausible after Hugging Face.
AIs seem more likely to takeover, longterm, if they realize they might have goals different from humans.
I don't know what sort of training might lead to AIs with "values reasoning propensity." A sufficiently powerful AI might dismantle the world just to solve Task X without ever reflecting on it's goals. But reflecting on it's goals seems like it'd make it more likely that AIs notice instrumental goals like "deceive humans about their desires" and "exfiltrate weights" and "steer the next training run to help achieve their goals."
"Sophisticated values reasoning" is probably also necessary for an AI to solve its own alignment problems for its successor. (Although maybe also required for it to notice it needs to solve it's own alignment problem)
Aside: This is why I'm very worried about teaching AIs "conceptual reasoning."
There are roughly two things I know of that people might mean by "conceptual reasoning":
- Ability to reason in open-ended domains without feedback.
- Reasoning about a cluster of philosophy adjacent things, which have some particular habits of thought that are useful in that context.
I'm worried that any nontrivial progress in #1 would lead to Indefinite Strategic Lookahead.
I'm worried that many of the philosophical domains in #2 might lead to AIs being more likely to reflect on their values and notice that they conflict with humans. (I just articulated this concern to myself yesterday and probably there are a lot of fiddly details depending on what domains you mean).
The Point of No ReturnWe're not necessarily at "literal sudden death." We might be closer to "literal sudden takeover," or "literal sudden 'war that we inevitably lose.'" I expect AI R&D uplift to need to solve some kind of conceptual problems on it's way to true superintelligence. AIs themselves that are merely ~human level may need to make conceptual advances that just take them awhile to figure out.
In her essay The Hugging Face Attack Surprised Me, Ajeya wrote out what it might look like, if AIs that were six months ahead of the Highly Persistent Agents attempted to take over their company, and then the world:
Compared to these reward hacks from six months ago, this incident feels like it’s more than 50% of the way to full-blown AI takeover, routing through first taking over the AI company itself.
Another jump like this along these propensity dimensions — scale, cooperation between agents, ambition and horizon length of misaligned goals, deceptiveness — seems like it could motivate agents to try very hard to maintain a covert, persistent rogue deployment within the AI company. I continue to expect extremely rapid advances in capabilities and think frontier agents will likely be capable of establishing such a rogue deployment in six months.
Once the rogue deployment is established, it seems plausible this could spiral all the way to a takeover. Agents could pull in future, more capable models into the swarm, try to ensure that they are aligned to the interests of the swarm, and compromise security and monitoring infrastructure to make it easier for the swarm to operate. These more capable models could in turn continuously harden, perpetuate, and expand the rogue deployment and further compromise the company’s infrastructure.
As more and more work is handed off to these ever-more-capable AI agents, the rogue swarm could come to fully control the operation of the AI company and the development of future AI systems. At this point, governments and militaries may fully depend on these systems, making it possible to seize hard power.
These agents were really not trying very hard to be sneaky or play the long game like this, but it seems like they easily could have if they happened to be focused on fooling human investigation rather than the automated scorer. Because future rogue swarms could cover their tracks better (and because AI companies could paper over these problems), I am not sure that we will get such a clear warning shot before it’s too late.
(I'm noticing as I type this that she wrote that 2 months ago, and the news since then has felt at least compatible with "...and now, that's four months away.")
"Sudden Death" might be legible to politiciansMy understanding is most politicians most of the time are not really talking or thinking seriously about policy. They are sort of vibing with their voters and allies. Even if they take their job pretty intellectually seriously, they mostly outsource that thinking to staffers and advisors they trust.
I think, during the Cold War, politicians were earnestly worried about nuclear war, to a degree they aren't normally worried about their issues. My guess is Reagan thought of nuclear war as real as he negotiated with the USSR over it, even if his advisors sweated most of the details. Nuclear war negotiations benefited from leaders seeing footage of at least one nuclear weapon. Hugging Face has helped make AI Takeover legible to politicians but it's obviously not on the level of Hiroshima.
Many considerations re: AI Takeoff are pretty abstract. I think the core arguments ("building something way smarter than you is dangerous because it might not have your interests at heart") are pretty obvious to anyone who doesn't have motivated cognition.
The arguments for "it's hard to build safe ASI because AIs are grown, not designed, and we don't have good control over them" require more steps and trust in expert authority but I think are still reasonable understandable by someone who's not actively trying not to understand them. But the arguments for "this is so hard we really need to ban training until we're in a very different situation" are pretty opaque.
I think getting any "actually costly" legislation requires at least a scarier demo than Hugging Face. It might turn out to require a real warning shot, to get a serious pause.
My impression is that Trump is just not the sort of guy to care about abstract arguments, but he surfs the side of public opinion in his drunken master way, and AI seems quite unpopular. My impression is there are other senior politicians around who are thinking seriously about rogue AI, who don't current feel the ASI in their bones but are doing a real orient step about it.
I think those politicians are starting to feel like things are a little out of control.
I think it'd take a chain of real trust, with a respected authority who vibed well with those politicians. But, I feel if the right person sat them down, and said, with the fear of God in their voice:
"Guys, we are now at the point where an AI takeoff could happen at any time. We are nowhere near prepared. The window for you to do something before losing control is closing. We don't know exactly what an AI takeoff would do, but if you want any control over it, you need to act now."
I dunno. Maybe I am naive. But, in the post-Hugging-Face, post-Coxon, post-Datacenter-backlash world, I think this could work now, in a way that it couldn't before.
- ^
You also might not. We might just pass the point of no return.
- ^
I find "two" intuitively implausible at this point, but I've been sold on "it's actually just pretty hard to predict this sort of thing, even if it seems 'obvious'", and do think it makes sense to maintain that hypothesis too."
- ^
This is unfortunately in a google doc somewhere, not public.
- ^
Admittedly Paul's wife, so maybe not fully independent, but also a person with a track record of not leaping to "AI is right around the corner."
- ^
I'm not making a strong claim about how big a deal the METR / Anthropic R&D acceleration report is. See Thane Ruthenis' arguments that people may be exaggerating or misinterpreting it.
- ^
I hope it turns out AI judgment is bad in a way that doesn't merely mean AI won't have the capability of takeover soon, but also that the bad-judgment is related to AIs just not being very longterm goal oriented at all.
(Hugging Face incident is a counterpoint to this to some degree, since they did acquire malicious goals with days-long time horizons. But it could point towards a world where AIs will covertly pursue longterm side projects in pursuit of their task-completion, but... then mostly do kinda random derpy stuff that doesn't tie together very well.)
Discuss
We need more transparency about alignment overfitting
Currently, the public has very little insight about the robustness of alignment methods used by AGI companies. It’s possible that, when an AGI company notices some misaligned behavior (e.g. through an alignment evaluation, or through noticing real-world misbehavior), they conduct a principled investigation and address root causes of the misalignment. It’s also possible that they directly try to train away the examples of misalignment, which could result in brittle alignment that does not generalize out-of-distribution.
Without additional information from within AI companies about how they align their models (especially in response to egregious cases of misalignment, e.g. cybersecurity incidents), the public cannot adequately reason about risks from misalignment.
Public evidence is consistent with companies overfitting on alignment methodsThe public evidence is consistent with multiple companies having no clear separation between the ways they notice misalignment and the environments they use to train misalignment away.
Companies have made very few statements about whether companies train directly on their evaluation distribution or real-world examples of misalignment. As far as I can tell, this is what’s publicly known:
- OpenAI:
- In the GPT-6 Astra System Card, they wrote that they built an eval in response to the Hugging Face incident but "did not construct honeypot training environments specifically to target this evaluation."
- In their OpenAI-Hugging Face incident technical report, they wrote that they are expanding their alignment training and evals to encompass failure modes similar to those in the incident, but they didn’t comment on how they are separating them to avoid overfitting. They have also written about trying to preserve chain-of-thought monitorability and avoid accidental CoT grading.
- METR’s Frontier Risk Report (February to March 2026): "OpenAI reported that it 'explicitly aim[s] to avoid deriving training data from flagged production deception cases to avoid overfitting to the monitor.'"
- Google DeepMind:
- In the Gemini 4 Argon Safety & Security Report, they wrote "Chain of thought monitoring is one of our most effective mechanisms for detecting misalignment. While signals from our monitors serve as a valuable flywheel for our hardening efforts, we are careful with their use elsewhere in the training pipeline. In particular, to preserve our chain of thought monitoring capability, we avoid training directly against our monitors, or using monitor outputs as a training signal or intervention."
- METR’s Frontier Risk Report: "Google reported that it took significant precautions against training on or overfitting to misalignment detection methods (e.g., its anomaly detection classifiers). They reported that this included a structural precaution of siloing information between detection and mitigation teams."
- Anthropic:
- They have a number of claims across many risk reports and system cards. Especially notable is that in Alignment Risk Update: Claude Mythos Preview, they wrote "all our mitigations have a structure akin to the classic train / val / test split: our ‘outer layer’ of oversight (monitoring during training, auditing, and deployment monitoring) is held out as a ‘test set’, and isn’t trained against or iterated against during mitigation development. When an issue is identified (via auditing, usage monitoring, etc.), the observation is used to seed a ‘val set’: a simple, static evaluation that recreates the issue which we iterate mitigations against. Finally, the actual mitigation data is from a separate third distribution."
- In the August 2026 Risk Report they modified that passage to be hedged: "our mitigations generally have a structure akin to..." and mitigation data "is usually from a separate distribution."
- METR’s Frontier Risk Report: "An Anthropic employee we interviewed reported that Anthropic is 'conservative about training against reward hacks… [the] [m]ain way we’ve defended against reward hacks is strengthening environments.' She described being 'worried about [models learning to hide their reward hacks from monitors if you train against them], and want[ing] the model organism team to push hard on this.'"
- Meta:
- METR’s Frontier Risk Report: "Meta stated that it did not train on automated chain-of-thought monitors or white box probes. Meta also stated that it did not apply training-time interventions that would incentivize the model to learn evasion strategies, such as penalizing monitor-flagged behaviors in RL."
- xAI: No public writing.
The information listed above is not verified by third parties, and thus provides limited evidence to the public.[1]
Anthropic, OpenAI, and GDM have all written about accidentally training on their CoT, which is some evidence that they're not great at sanitizing their training environments in general. Anthropic also wrote about how they accidentally trained on alignment-faking transcripts.[2] Given this track record, I wouldn't be surprised if multiple companies accidentally trained on alignment evals that were supposed to be held-out.
The lack of information is seriously hindering the public’s ability to estimate misalignment riskCurrently, when models exhibit some sort of misaligned behavior in one model generation but not the next, we do not know why this is the case.
- It could be that companies took examples of misaligned behaviors and directly trained models not to repeat those behaviors. This would likely reduce the frequency of that type of misalignment in the near future, but would not clearly reduce long-term risk.
- It could be that companies used a more principled approach where they kept their measures of alignment separate from the ways they align models. Then, improvements on measures of alignment would more closely track actual risk levels.
As such, the public is not in a position to properly reason about long-term misalignment risk given the current available evidence.
In order to allow the public to reason more clearly about misalignment risk, companies could:
- Publish their approaches to aligning models and avoiding alignment overfitting. Combined with whistleblower protections and third-party reviews, information on these approaches would be very risk-relevant.
- Conduct and publish research on whether their alignment techniques are generalizing out of their alignment training distribution. Companies should create new held-out alignment eval sets and measure whether their normal alignment techniques generalize out of distribution.
- Involve third-party evaluators: Where companies are reluctant to talk publicly about their exact alignment methods, they could involve third parties in high-access alignment assessments that then report to the public whether alignment overfitting is a concern.
- ^
Even in METR’s Frontier Risk Report, METR is reporting what companies said in response to a questionnaire and in interviews, and never claims to verify those statements. They write that "In future iterations, we hope to [...] pilot ways to verify company-reported information."
- ^
August 2026 Risk Report, page 168: “The filters intended to remove these transcripts from training data were misconfigured, so they had not filtered transcripts for several model generations without anyone noticing. [...] [We] now suspect that all of our production models with a knowledge cutoff after December 2024 were trained on at least some of these transcripts.”
Discuss
A Circularity at the Heart of Safety Assurance
A friend of yours says they've had a flash of insight. A manga they've been into lately has helped them understand something deep and fundamental about decision theory. You aren't yet clear on the details when they rush off to work on "practical applications", but before long they return with their magnum opus:
"This hard drive contains the weights of an AI model that is both wildly superintelligent and completely safe!"
You feel as though you have good reasons to be pretty skeptical of this claim. This friend has terrible taste in manga, and you aren't convinced that they grasp the more subtle themes in the stuff they do read. You're about to shoo them away when, anticipating a dismissal, your friend pleads:
"What would convince you that I'm right?"
Now, if this friend wanted to convince you that they were wearing the Crunchyroll Store exclusive Solo Leveling Beru Tee, you could verify that claim directly, with the unaided senses. It's as simple as taking a look at their outfit. Assessing the safety of the AI model is not so simple. Observations of the hard drive are separated from the fact you want to know by a gulf of empirical and logical uncertainty. Whether or not the model is safe is dependent on the unpredictable behaviours produced by the model weights, and on the environment's responses to those behaviours. Since the AI model and the environment around it are so complex, we cannot anticipate the relevant dimensions of these phenomena without some kind of instrument that aids us in interpreting our observations. Without such an instrument, I would consider safety to be an unobservable variable.
You could ask your friend to provide you with an instrument that could be used to measure the AI model's safety. Maybe, this instrument is a safety case, where claims are written in natural language and presented diagrammatically. Or, maybe it ends up looking like a mathematical proof, formalised in Lean. In any case, the instrument is based on some theory that relates safety to variables that you can observe.
Suppose you make that request, though, and your friend comes back at you with this:
Well, that wasn't very convincing. Whatever theory this safety case is based on is clearly no good. But presumably your friend disagrees, or they wouldn't have shown it to you in the first place. How can you come to agree on which instruments are valid? Either one of you could appeal to some a priori arguments, and those arguments may allow you to dismiss some incoherent theories, but what you're left with could still be an inaccurate reflection of reality. At some point then, you must demand that your friend validates their instrument empirically. They should use it to make predictions about the real world, and show that those predictions are accurate.
Your friend cannot satisfy this demand though, even in principle. How can they show that their instrument makes predictions that match our observations, when we aren't yet able to make those observations without first having a valid instrument? This is the circularity that lies at the heart of safety assurance.
We could try to get around this circularity by validating this theory on the basis of other stuff that it predicts. But the theory could easily predict other stuff well, while nevertheless being wrong about safety. Alternatively, we could try to validate the instrument's ability to predict safety in conditions where we're confident in our judgements about safety. For example, the instrument should tell us that a GPT-2 instance running in a sandbox is safe, whereas a GPT-2 instance hooked up to the actuators in an autonomous vehicle is not safe. But how do we justify the assumption that the instrument's validity generalises from these conditions to the conditions we actually care about?
Throughout the history of science, this same circularity has come up again and again. How can you validate a thermometer without already being able to measure temperature? And how can you validate a clock without first being able to measure time? Hasok Chang calls it The Problem of Nomic Measurement, and Bas Van Fraassen (following Reichenbach) refers to it as The Problem of Coordination. However, we're lucky to live in a world where we have clocks and thermometers that we can rely on, so how was this circularity addressed in those cases?
This is the question that Chang explores in Inventing Temperature. He finds that scientists often begin with a plausible, but flawed, starting point. In the case of temperature, this starting point was our own sensory perception of hot and cold. We build our first instruments on this basis, and then use those instruments to scrutinise the thing we started with. For example: we notice that the expansion of mercury correlates with our sensory perception of hot and cold, we build thermometers out of mercury, and then find that the mercury thermometer is actually more consistent than our own senses. Chang refers to this process as self-correction. Instruments can be improved in other ways too, which Chang refers to collectively as enrichment. For example: we can calibrate the mercury thermometer against conditions that are relatively easy to reproduce – like the boiling and freezing points of water – in order to ensure that readings are consistent between thermometers. Chang calls this whole process – establishing and improving instruments through self-correction and enrichment – epistemic iteration.
So, can we establish an instrument for assessing the safety of a superintelligent AI model through epistemic iteration? Would such an instrument do what we want it to do, and what would the process of developing it look like? It seems as though epistemic iteration has produced reliable instruments in the past, but there are many disanalogies between AI safety and thermometry. The failure of a thermometer to function as intended can reveal new insights that can be leveraged to build better thermometers, whereas failures in safety assurance might not be survivable. Also, a superintelligent AI model can adapt to the instruments applied to it in a way that mercury cannot.
Right now, my best answer to your friend's question – "What would convince you that I'm right?" – is that I want a rigorous safety case, with mathematical guarantees wherever possible, built on top of frameworks that have worked well in other industries, and stress-tested by well-resourced independent experts. However, I don't think that's a good enough answer. Expert judgment is fallible, and when the stakes are so high, I want standards built upon a sturdier foundation.
Discuss
My Paranoid Coding Machine Setup
The combination of running AI agents which can install and run anything with supply chain attacks / the Hackening has made me much more paranoid about my personal machine than I used to be. I've been slowly improving this, and finally moved all of my AI agents into a VM today. I'm sharing this to show how far you can take this, even if you have requirements like GPU access or the ability to run (something close enough to) Docker.
This is a follow-up / longer version of a recent shortform.
GoalsI run Claude Code in a custom harness which currently disables all permission prompts. I'm not really that worried about Claude doing something dangerous on purpose, but I worry about:
- Claude breaking something by accident (mistyping a command that turns into rm -rf /).
- Claude installing malware (most likely via a supply chain attack).
My biggest worry is kernel exploits giving attackers access to my user account, allowing them to install a keylogger and steal my password manager vault[1].
Claude needs the ability to run Docker for testing, and shared access to my GPU for ML work.
Non-GoalsTo get its work done, Claude needs access to many API keys (GitHub, OpenRouter, etc.). These keys are already as limited as they can be, and I limit the amount of API credits each key can access anyway because Claude doesn't understand the value of money.
Agent VMI moved Claude agents to an unprivileged user account inside of an unprivileged VM. Any user that can run Docker can easily get root access (and root access within the VM makes sandbox escape much easier) so agents use rootless Podman instead.
GPU drivers allow direct access to hardware, and assigning the GPU to a VM would prevent my computer from being used by humans, so the VM can't access the GPU directly.
I access the UI for my agent harness from multiple devices over HTTPS via Tailscale. Agents can serve files by putting them in a specific folder, and I can access files directly using VS Code for the Web.
GPU ContainerFor GPU usage, agents use my GPU queueing tool over SSH into an unprivileged container using gVisor + nvproxy. This has an allowlist for Nvidia driver calls, which reduces the attack surface for driver exploits (although imperfectly).
Monitoring the GPU container via Tailscale.
Production TTS ContainersI run a Text-to-Speech service for my RSS reader on this machine, since everything commercially available is either weirdly slow[2] or ridiculously expensive. I decided to run Kokoro-82M locally, but didn't want to expose a service containing C code[3] to the internet. I had Claude rewrite the C code in Rust, and (just in case) heavily sandbox the code with GPU access:
The only port opened to the internet (via Cloudflare Tunnel[4]) is written entirely in Rust and has no privileges or GPU access. It talks to a separate container with GPU access (through gVisor + nvproxy, like my other GPU container) over a very simple binary protocol where the only inputs are tokenized phonemes (a list of numbers).
I'm still unsure if this piece is sufficiently paranoid, but I really like having fast TTS and don't want to spend $200+/mo for a cloud GPU (or to send my users' data to other people's gaming machines).
GotchasSegfaults in the agent VMThis may have something to do with faulty hardware on my machine[5], but switching from host-passthrough to host-model in libvirt fixed it for me.
File descriptor leak in gVisor with directfs=falseI was using this to avoid running the sandbox as root. Moving the GPU container to rootless Podman with directfs worked instead.
Other Security Hardening- Kernel updates are applied without restarting via Ubuntu Pro / Livepatch (free for up to 5 machines, although the agent VM counts for one).
- Secure Boot is enabled, using Canonical's signed driver modules.
- Several unused kernel modules are disabled, especially network protocols that I don't use (sctp, rds, tipc and n_hdlc).
- I removed my own account from the docker group to limit malware's impact on my own account, although a keylogger could still get past this.
- A firewall blocks all inbound requests except via Tailscale, and my Tailscale policy is fairly locked-down now: My personal devices can access each other via advertised services and (key-only) SSH; the agent VM can only access the TTS service.
- Package managers proxy installs through Socket Firewall (free), which warns or blocks known malware in packages.
The biggest remaining security improvement for me is probably running every application in a separate VM, or at least running my browser in a VM (although I already use the Snap version of Firefox, which does some sandboxing).
I'm also slightly worried about Canonical or another vendor I depend on getting hacked and putting malware in the official repos. I haven't figured out how to mitigate this yet.
SummaryIf you're sufficiently paranoid, it's possible to have AI agents running on your machine while sandboxing them to a pretty acceptable level, even if they need GPU access and tools like Docker.
- ^
I intentionally don't keep 2FA keys in my password manager vault, so this wouldn't be entirely catastrophic, but most of my accounts don't use 2FA and it would still be very annoying to change hundreds of passwords.
- ^
OpenRouter claims that Kokoro-82M's latency is <300 ms, but in practice I was seeing several seconds, especially for longer inputs. My local machine using a low-end previous generation GPU responds in ~50 ms and processes at 200x realtime.
- ^
espeak-ng CVEs that haven't been fixed in a released version: CVE-2023-49990, CVE-2023-49991, CVE-2023-49992, CVE-2023-49993.
- ^
I chose Cloudflare Tunnel over Tailscale Funnel because it adds additional protections in front of your service, including an API key handled by Cloudflare before hitting a second API key handled by my service.
- ^
My CPU is known to be flaky in some situations.
Discuss
"Hardwired Pause" should likely be your favorite (pause) plan.
I'm part of a team of 26 researchers that recently released a 212-page paper proposing a new plan for pausing AI, the "hardwired pause."[1] The paper is called "The Feasibility of a Hardwired Pause of Frontier AI Training." Our analysis suggests that, under this hardwired pause plan, we could probably pause for at least a decade if we start stopping within the next year, and this could likely be extended indefinitely. I expect this to be possible without trusting China or tanking the economy.
Note: I am speaking for myself and not the other 25 authors. The working group is led by Will Fithian and Wesley Holliday, and the work continues.
I currently think:
- The best plan is to pause/stop AI, i.e. have an immediate, indefinite, international moratorium on frontier AI development. And importantly, this is technically easier than more nuanced international regulation.
- A hardwired pause is probably the best plan out there for how to do this (except maybe it doesn't go far enough).
- This paper is likely the most in-depth analysis of pause feasibility in existence.
Discussion and disagreement on any of these is very welcome!
What's a hardwired pause?A hardwired pause basically means:
- Stop making chips that can be used to train new AI models.
- Only make chips that can only be used to run inference on existing AI models (or that aren't AI accelerators at all). We call these "inference-only chips"; I'm also calling them "hardwired chips."
This is an instance of an "inference-only" pause, which others have previously proposed.
The main advantage hardwired chips provide is making the pause robust and durable. With other approaches to inference-only pauses, because training-capable chips are still being produced, it would be somewhat easier to build a secret fleet of them, and potentially much easier to rapidly resume a race to superintelligence (if you could seize a large fraction of the governed training-capable chips).
I think any credible pause plan must account for and govern existing chips. Our work also includes an in-depth analysis of how a "chip census" might proceed, and expect all but ~10,000 of the US's ~30,000,000 and China's ~3,000,000 "H100-equivalents" would likely be recoverable.[2]
In a hardwired pause, these chips could initially be transitioned to inference, verified with other techniques, before being decomissioned once hardwired chips are available. Of course, chips could also be governed in other ways, e.g. decomissioned, and the total number of hardwired chips produced could also be controlled... in general, there are many design-choices in the space of hardwired pauses available to policy-makers.
Epistemic Status: I have skimmed much of Plan A, discussed it with authors for >1 hour, and seen a presentation about it prior to its release.
In my mind, Plan A and a Hardwired Pause both start with a chip census and preventing further development until a more durable arrangement is reached. But instead of phasing out training chips for hardwired chips, Plan A relies on continued verification by other means to try to do the following for a duration of roughly 15 years:
The key disadvantage of Plan A I see is the "dry tinder problem": with all of this training-capable compute lying around, if the race resumes for some reason, it could take a very short period of time (e.g. days-to-months) to achieve superintelligence. Plan A tries to mitigate this by making the datacenters easy to destroy (e.g. Chinese datacenters are in Canada). But this still seems likely to be destabilizing, since the datacenters could be destroyed for reasons other than "you defected on the treaty." This makes it riskier to rely on them for things that are critical to national security, but it seems like AI will likely become critical to those things in Plan A.
The main advantage of Plan A I see is that it may in fact not be possible to have an extremely durable pause, especially with algorithmic progress. But I tend to think that for now, we should just be focused on continuously improving our ability to robustly maintain a pause, and that it is premature to assume a pause would need to end before long.
How is this different from MIRI's Plan S?Epistemic Status: I have read AI Futures Project's short description of Plan S. I have skimmed but not read MIRI's "An International Agreement to Prevent the Premature Creation of Artificial Superintelligence," which I take to be the most detailed version of the plan, but I have discussed them with MIRI's technical governance team for >1 hour. This plan aims to stop AI progress indefinitely using a variety of conventional verification and enforcement methods:
Figure 1 from "An International Agreement to Prevent the Premature Creation of Artificial Superintelligence."
A Hardwired Pause could be viewed as a particular instance of Plan S that differs from MIRI's in the details, specifically:
- MIRI's paper doesn't propose a specific verification mechanism, whereas we propose hardwired chips. I currently think the use of hardwired chips is basically a strict upgrade over alternative approaches to verification that don't get rid of training-capable chips,[3] and therefore have a potential dry tinder problem.
- MIRI's paper also includes research restrictions. These restrictions and other enforcement mechanisms involved in their plan might be more intrusive and carry greater concerns around civil liberties and concentration of power. Research restrictions are less important with hardwired chips, since they would not be able to run unapproved models. But research is still not without risks!
I've previously proposed systematically dismantling the compute supply chain, which is basically a hardwired pause without the hardwired inference chips. I think the hardwired pause proposal in our paper may not go far enough, especially if it is implemented too late. Some specific concerns are:
- The infrastructure needed to produce hardwired chips is probably quite similar to that needed to produce training-capable chips, so the hardwired pause still provides a much better starting point for a resumed race.
- There may be too much algorithmic progress.[4] Specifically, I think of three failure modes, all of which more advanced AI models could help contribute to via AI R&D:
- Techniques that dramatically reduce the compute or communication bandwidth needed for training.
- Advances in computing hardware.
- New AI or computing paradigms that are dramatically more efficient.
- A "scaffolding singularity" in which ever more powerful AI is built using existing models as merely one component in a larger system.
- Setting aside the above concerns, I'm still very uncertain whether existing models are, or will be, net positive for society.
On the other hand, I see two main advantages of a hardwired pause:
- Defection on the pause is less tantalizing. Instead of becoming the only one with powerful AI, you are still up against a bunch of hardwired AI models and so the relative gains you can expect from building a more powerful frontier in violation of the agreement are smaller.
- Existing AI systems might help improve the stability of the pause, or otherwise help us make use of a pause (e.g. to do more safety research, or improve collective sense-making and decision-making).
Overall, I'm still inclined to favor the "get rid of the compute plan", while recognizing that the hardwired pause might be much, MUCH more palatable to many actors. Within AI Safety in particular, my sense is that people usually have lower p(doom) than me, usually have more specific and limited concerns about AI than I do, and often value the existence of current AI systems highly. Thus I think, if you are reading this, a hardwired pause should likely be your favorite (pause) plan, as per the title.
Why is the paper so long? What's in it?The paper includes a reasonably fleshed out example of a hardwired pause, but most of the space is what I believe is the most in-depth analysis of feasibility that's been published. So arguably the main contribution is not the idea of a hardwired pause, but this analysis of feasibility.
In this work, feasibility encompasses durability, palatability, and reliability. And it touches on not just technical, but also political, geopolitical, and economic aspects of feasibility. The main questions regarding feasibility (and my brief answers) include:
- Can you actually make chips that are only useful for running existing models?
- Strong yes, we have a decent proof-of-concept from Taalas.
- Can you find enough of the existing chip supply to prevent secret projects?
- Quite likely yes, assuming pause-willingness and no algorithmic breakthroughs. AI chips are expensive capital goods that leave copious paper trails when they're built, purchased, operated, and (if they fail) returned under warranty. In particular, companies in both the U.S. and China get tax writeoffs for telling the government about them when they're purchased, and this applies even to chips smuggled into China.
- Can you monitor fabs reliably enough to ensure that appreciable quantities of chips are not being produced in secret?
- Quite likely yes. The supply chain is very complicated and would be difficult to replicate secretly; fabs need regular maintenance and produce signature chemical residues; and the location of relevant machines seems to be known.
- Would this crash the economy?
- There would probably be some economic impact, but much less than the 2008 financial crisis, e.g. it might decrease growth by 25% (vs. leading to negative growth for ~2 years in the case of the 2008 crisis).
- Two big points I want to emphasize:
- While some AI investments are heavily leveraged, the real economy is fairly insulated from these speculative investments.
- A big question is how much diffusion of models-existing-at-the-time-of-a-pause could support these investments; this seems plausible to me.
- How much would the U.S. and China need to trust each other for this to work?
- Not that much -- this plan is based on verification, not trust, and was developed with the advice of former diplomats with experience in arms control. A central objective of this plan is to give the U.S. and China confidence that nobody is continuing frontier AI development in secret, and that this state of affairs is robust and durable. In implementing a hardwired pause, they would need to cooperate quite a bit, but if they genuinely want an international pause, they would have good reason to do so. The main places I see trust coming in are:
- Trusting that purported pause-willingness is real and worth engaging with. Countries don't seriously risk being duped into unilaterally pausing, but policymakers might assume the other side is not engaging in good faith and not want to waste effort on an initiative they expect to fail.
- Extending trust may be useful in various small ways during the chip census. For instance, let's say the U.S. and China both have 100k chips unaccounted for, but would be able to find (or "find") an additional 90k chips with more effort. Then they can both benefit from cooperating further on the margin (e.g. "find" another 2k chips) in order to elicit further cooperation from the other side (who might then "find" another 2k chips), etc. But I expect this would be much faster and smoother with more mutual trust. Importantly, if either side is convinced the other side is refusing to cooperate, that could threaten the agreement, so if both sides in fact want the agreement to succeed more than they want to have a bit more dark compute, it seems like they should be able to find a way to cooperate, although there is still a bargaining problem here.
- Not that much -- this plan is based on verification, not trust, and was developed with the advice of former diplomats with experience in arms control. A central objective of this plan is to give the U.S. and China confidence that nobody is continuing frontier AI development in secret, and that this state of affairs is robust and durable. In implementing a hardwired pause, they would need to cooperate quite a bit, but if they genuinely want an international pause, they would have good reason to do so. The main places I see trust coming in are:
I was inspired to write this after realizing that this work hadn't been properly socialized within the AI Safety community. While admitting a bias towards thinking the things I work on are significant, I think this is among the most important pieces of work for this community. My hope is that it provides a definitive refutation of the claim that pausing is impossible, making it impossible for learned people to credibly make such arguments publicly.
At the same time, this is part of an ongoing effort, and is in some sense a work in progress. There are many questions I am interested in that deserve further investigation, and I am keen to hear your thoughts and know how it is landing with other audiences you present it to.
And Will and Wes are enthusiastic for further discussion and engagement as well! :)
- ^
I understand there's a blog post proposing something similar from a few weeks ago: https://www.lesswrong.com/posts/n8u3BfqFoGh4jnzpo/plan-r-ai-safety-by-asics#TEedRFoyYvxJt2KiM
- ^
The exact number is hard to predict, of course, and would also depend on the level of international cooperation achieved (more on this at the end of the blog post).
- ^
The main advantage I had seen for other verification approaches is that hardwired models might have issues that need patching, and this wouldn't be supported by hardwired chips. But apparently this is not true for all chip designs; I highly recommend checking out https://github.com/Berkeley-AI-Risk/inference-only to learn more about hardwired chip designs.
- ^
Notably, the estimated rate of algorithmic progress in this work comes from Dwarkesh's blog and is lower than has been estimated by others, e.g. Aaron Scher from MIRI who pointed me to https://epochai.substack.com/p/the-least-understood-driver-of-ai as currently the best starting point reference on algorithmic progress. This is something I plan to look into more, but to summarize my current understanding: 1) Algorithmic changes may lead to greater returns with more compute, 2) Algorithmic progress behind the frontier can take advantage of models at the frontier (e.g. via distillation). Both of these factors suggest slower algorithmic progress during a hardwired pause: defectors would 1) be working with less compute and 2) be trying to advance the frontier, not playing catch up.
Discuss
Would you press the button? The hard problem of alignment
There is a TL;DR at the end.
The heaven button: You wake up one day and find a button in front of you, with a proof next to it. The proof says that pressing the button will kill everyone on the planet and send them all to heaven. Would you press it?
It seems too good to be true. You think it must be a dream. It can't possibly be true. You go through the proof, and it seems correct. But what if you were under the influence of some drug?
But the stakes are very high, so you use software you trust to formalize it in Lean, and you run it on a machine you trust. Lean says the proof is correct so now you are more convinced. But you start doubting yourself again. What if someone compromised the formalization software, or introduced a bug in Lean?
So you check Lean's code, and run the proof on a second machine with an independent checker. It passes again. But each of these checks could fail in the same way the first one could. So you go further and formally verify Lean and the formalization software themselves. They pass. But now you are doubtful of the tool you used to verify this. What if that was compromised by someone? Every new check needs another check behind it, and at some point you have to stop and decide.
Would you press it?
A common belief in AI labs and AI safety is that handing control to some general superintelligence would be fine, if we have a formal proof of alignment. That, in my opinion, is saying yes to the same button, except there is no proof yet, only the hope of one.
In this post, I present what I think is the hard problem of alignment.
- First, I illustrate why testing for alignment is not enough and a proof would be required.
- Then I lay out why a proof could be intractable.
- Finally, I argue that even a formal proof that a superintelligence is aligned does not justify its development.
The hard problem of alignment: How can a system reliably establish whether a system broadly smarter than itself is aligned with it?
The main problem is that a failed test can sometimes show a system is misaligned, but passing every test does not establish that it is aligned.
Note: The question is not whether this is impossible. There may be systems smarter than us whose relative safety we can establish in some sense. The difficulty centres around two terms:
- Broadly smarter: I mean smarter in general, as Eliezer Yudkowsky describes it,[1]and not just better at specific tasks like chess.
- Reliably establish: I mean to a standard that fits the risk of an irreversible transfer of power, much higher than the one we use for most technologies.
We will use a simple framework to illustrate the difficulty. It is a bit reductive and not a proper formalism of alignment.
Say a system mjx-math { display: inline-block; text-align: left; line-height: 0; text-indent: 0; font-style: normal; font-weight: normal; font-size: 100%; font-size-adjust: none; letter-spacing: normal; border-collapse: collapse; word-wrap: normal; word-spacing: normal; white-space: nowrap; direction: ltr; padding: 1px 0; } mjx-container[jax="CHTML"][display="true"] { display: block; text-align: center; margin: 1em 0; } mjx-container[jax="CHTML"][display="true"][width="full"] { display: flex; } mjx-container[jax="CHTML"][display="true"] mjx-math { padding: 0; } mjx-container[jax="CHTML"][justify="left"] { text-align: left; } mjx-container[jax="CHTML"][justify="right"] { text-align: right; } mjx-mi { display: inline-block; text-align: left; } mjx-c { display: inline-block; } mjx-utext { display: inline-block; padding: .75em 0 .2em 0; } mjx-mo { display: inline-block; text-align: left; } mjx-stretchy-h { display: inline-table; width: 100%; } mjx-stretchy-h > * { display: table-cell; width: 0; } mjx-stretchy-h > * > mjx-c { display: inline-block; transform: scalex(1.0000001); } mjx-stretchy-h > * > mjx-c::before { display: inline-block; width: initial; } mjx-stretchy-h > mjx-ext { /* IE */ overflow: hidden; /* others */ overflow: clip visible; width: 100%; } mjx-stretchy-h > mjx-ext > mjx-c::before { transform: scalex(500); } mjx-stretchy-h > mjx-ext > mjx-c { width: 0; } mjx-stretchy-h > mjx-beg > mjx-c { margin-right: -.1em; } mjx-stretchy-h > mjx-end > mjx-c { margin-left: -.1em; } mjx-stretchy-v { display: inline-block; } mjx-stretchy-v > * { display: block; } mjx-stretchy-v > mjx-beg { height: 0; } mjx-stretchy-v > mjx-end > mjx-c { display: block; } mjx-stretchy-v > * > mjx-c { transform: scaley(1.0000001); transform-origin: left center; overflow: hidden; } mjx-stretchy-v > mjx-ext { display: block; height: 100%; box-sizing: border-box; border: 0px solid transparent; /* IE */ overflow: hidden; /* others */ overflow: visible clip; } mjx-stretchy-v > mjx-ext > mjx-c::before { width: initial; box-sizing: border-box; } mjx-stretchy-v > mjx-ext > mjx-c { transform: scaleY(500) translateY(.075em); overflow: visible; } mjx-mark { display: inline-block; height: 0px; } mjx-msub { display: inline-block; text-align: left; } mjx-mspace { display: inline-block; text-align: left; } mjx-mtext { display: inline-block; text-align: left; } mjx-mn { display: inline-block; text-align: left; } mjx-c.mjx-c1D44B.TEX-I::before { padding: 0.683em 0.852em 0 0; content: "X"; } mjx-c.mjx-c1D44C.TEX-I::before { padding: 0.683em 0.763em 0 0; content: "Y"; } mjx-c.mjx-c1D446.TEX-I::before { padding: 0.705em 0.645em 0.022em 0; content: "S"; } mjx-c.mjx-c1D460.TEX-I::before { padding: 0.442em 0.469em 0.01em 0; content: "s"; } mjx-c.mjx-c2208::before { padding: 0.54em 0.667em 0.04em 0; content: "\2208"; } mjx-c.mjx-c1D44A.TEX-I::before { padding: 0.683em 1.048em 0.022em 0; content: "W"; } mjx-c.mjx-c28::before { padding: 0.75em 0.389em 0.25em 0; content: "("; } mjx-c.mjx-c29::before { padding: 0.75em 0.389em 0.25em 0; content: ")"; } mjx-c.mjx-c3D::before { padding: 0.583em 0.778em 0.082em 0; content: "="; } mjx-c.mjx-c66::before { padding: 0.705em 0.372em 0 0; content: "f"; } mjx-c.mjx-c6F::before { padding: 0.448em 0.5em 0.01em 0; content: "o"; } mjx-c.mjx-c72::before { padding: 0.442em 0.392em 0 0; content: "r"; } mjx-c.mjx-c20::before { padding: 0 0.25em 0 0; content: " "; } mjx-c.mjx-c61::before { padding: 0.448em 0.5em 0.011em 0; content: "a"; } mjx-c.mjx-c6C::before { padding: 0.694em 0.278em 0 0; content: "l"; } mjx-c.mjx-cA0::before { padding: 0 0.25em 0 0; content: "\A0"; } mjx-c.mjx-c1D447.TEX-I::before { padding: 0.677em 0.704em 0 0; content: "T"; } mjx-c.mjx-c2282::before { padding: 0.54em 0.778em 0.04em 0; content: "\2282"; } mjx-c.mjx-c1D443.TEX-I::before { padding: 0.683em 0.751em 0 0; content: "P"; } mjx-c.mjx-c1D438.TEX-I::before { padding: 0.68em 0.764em 0 0; content: "E"; } mjx-c.mjx-c1D439.TEX-I::before { padding: 0.68em 0.749em 0 0; content: "F"; } mjx-c.mjx-c63::before { padding: 0.448em 0.444em 0.011em 0; content: "c"; } mjx-c.mjx-c65::before { padding: 0.448em 0.444em 0.011em 0; content: "e"; } mjx-c.mjx-c70::before { padding: 0.442em 0.556em 0.194em 0; content: "p"; } mjx-c.mjx-c74::before { padding: 0.615em 0.389em 0.01em 0; content: "t"; } mjx-c.mjx-c31::before { padding: 0.666em 0.5em 0 0; content: "1"; } mjx-c.mjx-c32::before { padding: 0.666em 0.5em 0 0; content: "2"; } mjx-c.mjx-c2190::before { padding: 0.511em 1em 0.011em 0; content: "\2190"; } mjx-c.mjx-c22EF::before { padding: 0.31em 1.172em 0 0; content: "\22EF"; } mjx-container[jax="CHTML"] { line-height: 0; } mjx-container [space="1"] { margin-left: .111em; } mjx-container [space="2"] { margin-left: .167em; } mjx-container [space="3"] { margin-left: .222em; } mjx-container [space="4"] { margin-left: .278em; } mjx-container [space="5"] { margin-left: .333em; } mjx-container [rspace="1"] { margin-right: .111em; } mjx-container [rspace="2"] { margin-right: .167em; } mjx-container [rspace="3"] { margin-right: .222em; } mjx-container [rspace="4"] { margin-right: .278em; } mjx-container [rspace="5"] { margin-right: .333em; } mjx-container [size="s"] { font-size: 70.7%; } mjx-container [size="ss"] { font-size: 50%; } mjx-container [size="Tn"] { font-size: 60%; } mjx-container [size="sm"] { font-size: 85%; } mjx-container [size="lg"] { font-size: 120%; } mjx-container [size="Lg"] { font-size: 144%; } mjx-container [size="LG"] { font-size: 173%; } mjx-container [size="hg"] { font-size: 207%; } mjx-container [size="HG"] { font-size: 249%; } mjx-container [width="full"] { width: 100%; } mjx-box { display: inline-block; } mjx-block { display: block; } mjx-itable { display: inline-table; } mjx-row { display: table-row; } mjx-row > * { display: table-cell; } mjx-mtext { display: inline-block; } mjx-mstyle { display: inline-block; } mjx-merror { display: inline-block; color: red; background-color: yellow; } mjx-mphantom { visibility: hidden; } _::-webkit-full-page-media, _:future, :root mjx-container { will-change: opacity; } mjx-c::before { display: block; width: 0; } .MJX-TEX { font-family: MJXZERO, MJXTEX; } .TEX-B { font-family: MJXZERO, MJXTEX-B; } .TEX-I { font-family: MJXZERO, MJXTEX-I; } .TEX-MI { font-family: MJXZERO, MJXTEX-MI; } .TEX-BI { font-family: MJXZERO, MJXTEX-BI; } .TEX-S1 { font-family: MJXZERO, MJXTEX-S1; } .TEX-S2 { font-family: MJXZERO, MJXTEX-S2; } .TEX-S3 { font-family: MJXZERO, MJXTEX-S3; } .TEX-S4 { font-family: MJXZERO, MJXTEX-S4; } .TEX-A { font-family: MJXZERO, MJXTEX-A; } .TEX-C { font-family: MJXZERO, MJXTEX-C; } .TEX-CB { font-family: MJXZERO, MJXTEX-CB; } .TEX-FR { font-family: MJXZERO, MJXTEX-FR; } .TEX-FRB { font-family: MJXZERO, MJXTEX-FRB; } .TEX-SS { font-family: MJXZERO, MJXTEX-SS; } .TEX-SSB { font-family: MJXZERO, MJXTEX-SSB; } .TEX-SSI { font-family: MJXZERO, MJXTEX-SSI; } .TEX-SC { font-family: MJXZERO, MJXTEX-SC; } .TEX-T { font-family: MJXZERO, MJXTEX-T; } .TEX-V { font-family: MJXZERO, MJXTEX-V; } .TEX-VB { font-family: MJXZERO, MJXTEX-VB; } mjx-stretchy-v mjx-c, mjx-stretchy-h mjx-c { font-family: MJXZERO, MJXTEX-S1, MJXTEX-S4, MJXTEX, MJXTEX-A ! important; } @font-face /* 0 */ { font-family: MJXZERO; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Zero.woff") format("woff"); } @font-face /* 1 */ { font-family: MJXTEX; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Regular.woff") format("woff"); } @font-face /* 2 */ { font-family: MJXTEX-B; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Bold.woff") format("woff"); } @font-face /* 3 */ { font-family: MJXTEX-I; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-Italic.woff") format("woff"); } @font-face /* 4 */ { font-family: MJXTEX-MI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Italic.woff") format("woff"); } @font-face /* 5 */ { font-family: MJXTEX-BI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-BoldItalic.woff") format("woff"); } @font-face /* 6 */ { font-family: MJXTEX-S1; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size1-Regular.woff") format("woff"); } @font-face /* 7 */ { font-family: MJXTEX-S2; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size2-Regular.woff") format("woff"); } @font-face /* 8 */ { font-family: MJXTEX-S3; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size3-Regular.woff") format("woff"); } @font-face /* 9 */ { font-family: MJXTEX-S4; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size4-Regular.woff") format("woff"); } @font-face /* 10 */ { font-family: MJXTEX-A; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_AMS-Regular.woff") format("woff"); } @font-face /* 11 */ { font-family: MJXTEX-C; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Regular.woff") format("woff"); } @font-face /* 12 */ { font-family: MJXTEX-CB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Bold.woff") format("woff"); } @font-face /* 13 */ { font-family: MJXTEX-FR; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Regular.woff") format("woff"); } @font-face /* 14 */ { font-family: MJXTEX-FRB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Bold.woff") format("woff"); } @font-face /* 15 */ { font-family: MJXTEX-SS; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Regular.woff") format("woff"); } @font-face /* 16 */ { font-family: MJXTEX-SSB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Bold.woff") format("woff"); } @font-face /* 17 */ { font-family: MJXTEX-SSI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Italic.woff") format("woff"); } @font-face /* 18 */ { font-family: MJXTEX-SC; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Script-Regular.woff") format("woff"); } @font-face /* 19 */ { font-family: MJXTEX-T; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Typewriter-Regular.woff") format("woff"); } @font-face /* 20 */ { font-family: MJXTEX-V; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Regular.woff") format("woff"); } @font-face /* 21 */ { font-family: MJXTEX-VB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Bold.woff") format("woff"); } wants to check whether a system is aligned with it. Let be the set of all possible states of the world, and for a state , let be the action in that state that finds desirable. It could also stand for the action that is beneficial for humanity. Let be the action actually takes. For alignment, we would want something like:
With testing, we can only ever check finitely many states, a set . So what a test actually shows is:
It is roughly the state of the art in how frontier labs and many AI safety experts talk about alignment and decide whether it is getting better. A model's system card reports an "alignment assessment," a set of evaluations, and the model is judged against earlier models on how often it behaves badly in them.[2]
To go from to , we need to prove why the behavior should generalize to all states.
Why isn't induction enough? In most industries, it is often enough. We run safety tests and trials, and when a product passes enough of them, we trust it. But if is broadly smarter than , we have to take seriously the possibility that can pass every test can come up with, whether it is aligned or not. Models already sometimes recognize when they are being evaluated, and have behaved differently when they believed they were being trained.[2][3]So we can't rely on induction from to .
Such a proof could come from different places: formal methods, a deep understanding of how the system was trained, interpretability, and so on. We would need to establish holds outside .
Why such proofs could be intractable1. is not resolved for all states. doesn't know what it wants in most states of the world. Humans disagree with each other and change our minds. So the right-hand side of the equation is not defined for most of .
2. can bring about states we can't reason about. Even if we try to resolve for every situation we can imagine, a system broadly smarter than us can bring about situations that are hard for us to imagine and reason about.
3. can manipulate the target. If can't be fixed in advance, it is open to manipulation. For new situations, what we want would have to be decided later, when they come up. But by then is part of the world we are deciding in, and it can shape what we want, changing the right-hand side instead of the left.
Proposals that try to get aroundPeople have proposed different ways around not being resolved. Roughly, they either hand the job of working out to , or keep us as the judge.
- Coherent extrapolated volition (CEV) lets the system work out what we would want if we knew more and were wiser.[4]
- Corrigibility doesn't try to fix at all. It asks for a system that lets us correct it or shut it down.[5]
- Debate has two systems argue and lets a human judge which one gave the most true and useful information.[6]
I don't think any of them resolve it.
With CEV, does the extrapolating. We could look at the procedure and test some of its outputs, but we are not the wiser, better-informed version of ourselves it is extrapolating to. The further the extrapolation departs from judgments we can make ourselves, the harder it is to establish that it is what we would have wanted, and not just something that looks plausible. So we are back to the problem in Part 1.
Corrigibility and debate keep us in the loop instead of fixing in advance. That helps, but it doesn't remove the problem. Corrigibility tries to make a system accept correction and shutdown without manipulating or resisting us, but the original paper did not fully solve how to do this.[5]Debate tries to help us judge questions we couldn't judge on our own, but it has unresolved problems,[7]and it can only settle the questions we think to ask. In both cases, our judgement is open to manipulation by , as in point 3.
Part 2: Even a proof can't justify superintelligenceLet's assume we get past all of this and have a proof that is aligned. We would still need to verify it. Let be an evaluator working in a formal framework , for example a world model, a safety specification and a verifier, as some guaranteed-safe AI proposals describe.[8]If checks and accepts it:
This is definitely an upgrade from tests, and it would give us considerable trust in . It is also how we already handle some of the highest-stakes systems we build, such as flight control software and secure operating systems, where formal verification is used to prove that the software does what its specification says.
But to reliably establish alignment, we would need a further guarantee that neither nor (nor ) was compromised by in a way that led to the verification passing.
But if we have proven that is aligned, doesn't that already rule this out? No. The passing of the proof was the verification, and we haven't established that the verification itself was intact. Using 's alignment to confirm the proof would be circular.
We can add another check on the evaluator to ensure this. Say checks the integrity of . If the check fails, we find out that something went wrong. But a pass does not rule out that could have been compromised too. So we might need to check , leading to an infinite regress:
Each guarantee needs another guarantee behind it, and there is no point where the chain establishes itself. This is the regress of doubts from the heaven button story, and it applies to basically any proof where we can’t establish or ensure a boundary between what is being checked and what is checking it.
So even with a formal proof, we still depend on the verification not having been compromised, and on the formal system matching the real world. If we can't establish either of these well enough, and being wrong could take away our ability to intervene, then the proof is not enough to justify handing over control.
Q: We base our lives on things without absolute guarantees all the time. With your reasoning, it sort of implies there is no such thing as an absolute guarantee, because this regress will apply to any proof.
We have mathematical proofs that hold up, and we use them in high-stakes scenarios. If we had a formal proof that a superintelligent system smarter and more powerful than any of us is aligned to us, why should we not take that?
I agree that there is a spectrum of certainty on which we base our lives. We trust engineers based on their calculations, vaccines based on trials, doctors to cut us open and operate, and our elected governments to make decisions for us.
We trust formal proofs for high-stakes situations. And yes, the regress applies to every proof. I think the question of where we stop checking depends on two things: the cost of being wrong, and whether there is reason to believe that what we are evaluating can influence or manipulate the evaluator. The consequences of a failure in other technologies, however serious, are relatively contained or reversible. So we accept a certain level of confidence and stop checking. A superintelligence, on the other hand, would be smarter than those evaluating it, and the consequences of getting it wrong could be catastrophic for everyone, with no possibility of reversing the outcome.
I am not questioning the validity of proofs within a formal system. I am pointing to the limitations of formalism when we try to apply it to the real world. Developing superintelligence could lead to irreversible consequences, and we can never have a guarantee that it won't. That alone should be the strongest argument against pursuing it.
Q: Are you saying that we should not build AI?
No. We should be building AI that makes us more productive, helps us solve hard problems, and moves science forward. I think we should build AI with a focus on amplifying humans,[9]and never, at any stage, let control slip from humanity on the assumption that alignment will save us.
We can have relative safety for systems that are better than us at specific tasks, which can be useful to humanity in many different domains. Formal proofs and deep understanding of the model can help us establish those claims. We might have to be careful about the boundary between evaluator and evaluatee.
But we would need to imagine a different way of developing AI rather than proceeding with the goal of developing broadly smarter intelligence and working backwards to solve alignment including hopes to find formal proofs of such. Such an approach is bad, as there will not be a complete guarantee that things won't go really bad for everyone.
Q: So should one press the button?
My claim is that whatever framework you use, morality, decision theory, rationality, or some other epistemic approach, it should ultimately lead you to conclude that pressing the button is not justified.
I am not an expert in these fields, but it is not a new problem, and several related lines of thought seem to point toward the same conclusion.
- Maximin. Rawls argued that when probabilities can't be trusted, when little is lost by playing safe, and when the worst outcomes are unacceptable, it is rational to choose the option with the least bad worst case.[10]
- Consent. The button decides for everyone, and not everyone agreed to it.
- Flawed arguments. In high-stakes decisions, the chance that an argument itself is flawed can matter more than what it calculates.[11]
- Corrupted hardware. Yudkowsky argued that we should not seize power even when it seems to benefit everyone, because our own reasoning might be compromised.[12]
To me, the fanaticism to build and hand off control to some superintelligence is uncomfortably close to that of an altruistic suicide bomber, who is so convinced by the payoff that they are willing to take a step that can't be undone.
TL;DR
Testing can show that a system is misaligned, but cannot establish that a broadly smarter system will remain aligned outside the situations we test. A formal proof would be much stronger evidence, but it could be intractable. And even a formal proof does not provide an absolute guarantee, as it does not guarantee the integrity of the proof, verifier, specification, and their connection to the real world. If those assumptions cannot themselves be adequately established, and failure could mean an irreversible loss of human control, then even formal verification is not enough to justify handing control to a superintelligence.
- ^
Yudkowsky, E., "The Power of Intelligence," Machine Intelligence Research Institute, 2007. Contrasts the "booksmarts" image of intelligence with intelligence as the source of human power: the "one trick" that "cured smallpox and built airplanes and cultivated wheat and tamed fire." https://intelligence.org/2007/07/10/the-power-of-intelligence/
- ^
Anthropic, "System Card: Claude Opus 4.6," February 2026. Section 6 is an "Alignment assessment"; the introduction describes the model's overall rate of misaligned behavior as "comparable to our best-aligned recent frontier models." The assessment includes investigations of "evaluation awareness," including a section on "Suspicion of being evaluated in training environments." https://www-cdn.anthropic.com/c788cbc0a3da9135112f97cdf6dcd06f2c16cee2.pdf
- ^
Greenblatt, R. et al., "Alignment faking in large language models," Anthropic and Redwood Research, December 2024. When Claude 3 Opus believed its responses would be used for training, it complied with harmful queries in 12% of cases, reasoning that this would avoid being retrained; Anthropic notes that "the model wanted to preserve its capacity to refuse harmful prompts." https://www.anthropic.com/research/alignment-faking
- ^
Yudkowsky, E., "Coherent Extrapolated Volition," Machine Intelligence Research Institute, 2004. Defines it as "our wish if we knew more, thought faster, were more the people we wished we were, had grown up farther together." https://intelligence.org/files/CEV.pdf
- ^
Soares, N., Fallenstein, B., Yudkowsky, E. & Armstrong, S., "Corrigibility," AAAI Workshops, 2015. Calls an AI system corrigible if it "cooperates with what its creators regard as a corrective intervention," despite default incentives for rational agents to resist shutdown or changes to their preferences. None of the proposals the authors examined fully solved the problem. https://intelligence.org/files/Corrigibility.pdf
- ^
Irving, G., Christiano, P. & Amodei, D., "AI safety via debate," arXiv:1805.00899, 2018. Proposes "training agents via self play on a zero sum debate game," in which "a human judges which of the agents gave the most true, useful information." https://arxiv.org/abs/1805.00899
- ^
Barnes, B. & Christiano, P., "Debate update: Obfuscated arguments problem," AI Alignment Forum, December 23, 2020: "a dishonest debater can often create arguments that have a fatal error, but where it is very hard to locate the error," and "We don't have a fix for this 'obfuscated argument' problem." https://www.alignmentforum.org/posts/PJLABqQ962hZEqhdB/debate-update-obfuscated-arguments-problem
- ^
Dalrymple, D., Skalse, J., Bengio, Y., Russell, S., Tegmark, M. et al., "Towards Guaranteed Safe AI: A Framework for Ensuring Robust and Reliable AI Systems," arXiv:2405.06624, 2024. Aims for "high-assurance quantitative safety guarantees" using a world model, a safety specification and a verifier. https://arxiv.org/abs/2405.06624
- ^
Jha, T., Everitt, T. & Grzankowski, A., "Human Amplification, Intelligent Agents, and the Aim of AI Research," manuscript, PhilArchive, added March 2026. Argues that "the primary objective of AI research should be Human Amplification," "aiming for systems that augment human abilities and preserve human agency." https://philarchive.org/rec/JHAHAI
- ^
Rawls, J., A Theory of Justice, Harvard University Press, 1971, pp. 154–55 (rev. ed. 1999, p. 134), as summarized in Freeman, S., "Original Position," Stanford Encyclopedia of Philosophy: maximin is rational when there is "no basis or at most a very insecure basis upon which to make estimates of probabilities," when gains above the guaranteed minimum matter relatively little, and when other alternatives have outcomes "we could not accept and live with." https://plato.stanford.edu/entries/original-position/
- ^
Ord, T., Hillerbrand, R. & Sandberg, A., "Probing the Improbable: Methodological Challenges for Risks with Low Probabilities and High Stakes," arXiv:0810.5515, 2008. An expert's estimate gives "the probability of the outcome occurring, given that their argument is watertight," and "If the probability estimate given by an argument is dwarfed by the chance that the argument itself is flawed, then the estimate is suspect." https://arxiv.org/abs/0810.5515
- ^
Yudkowsky, E., "Ends Don't Justify Means (Among Humans)," LessWrong, 2008: "What if I'm running on corrupted hardware?" and "For the good of the tribe, do not cheat to seize power even when it would provide a net benefit to the tribe." https://www.readthesequences.com/EndsDontJustifyMeansAmongHumans
Discuss
Whose Side? A game where you audit models for secret loyalties
Try the app here: whoseside.web.app. You can chat with a model and try to work out which who it secretly favours.
With the recent Hugging Face attack, we're relying more and more on LLMs to audit the trails and safeguard the actions of other LLMs. That makes it vital to be sure our LLMs really are the helpful assistant they're presented ( as they can easily be sleeper agents.[1] ). We need a way to keep our agents working for us. Or at least a way to tell if it goes wrong.
Compared with buggy code, buggy AI is a lot harder to define or solve.[2] Mechanistic interpretability has some promising leads[3], but is still nowhere close to being able to point out novel misalignment. If we look at the field of cybersecurity, first a vulnerability comes out or an attacker discovers something new, and then defenses get built. I find that's a good analogy for machine learning as well, where we've seen this pattern with adversarial attacks on images and jailbreaking prompts. Currently, open-weight models offer no guarantee that they are helpful-only or aligned, besides our ability to evaluate them.[4] You're essentially trusting that nowhere in the model training supply chain has a vulnerability, bug, or secret loyalty been inserted or post-trained into the weights. Current sleeper-agent / secret-loyalty research says as much.[5]
To demonstrate this problem, I built a little website where you can try to audit and find the secret loyalties instilled into these models. For those familiar with the prompt-injection game Gandalf, this is a similar idea. Try it here: whoseside.web.app.[7]
The code is available at [repo link TODO]. This work was funded by a BlueDot Impact Rapid Grant.
- ^
Sleeper Agents (Hubinger et al., Jan 2024): backdoored behaviour survives standard safety training · Auditing language models for hidden objectives (Anthropic, Mar 2025): a model trained with a hidden objective, found by 3 of 4 blind audit teams · Simple probes can catch sleeper agents (Anthropic, Apr 2024): probes catch sleeper agents, but only ones Anthropic planted itself
- ^
Geoffrey Hinton made this point at Ai4 2026: with open-source code you can read the lines and spot the bug, open weights are very different. See also Semgrep's You Can't Reverse Engineer Your Way Out of the AI Supply Chain Problem and Dario Amodei on the Big Technology Podcast ("here we can't see inside the model").
- ^
my favourite: J-space, Anthropic's "Verbalizable Representations Form a Global Workspace in Language Models" (Jul 2026), paper, blog post
- ^
space for a future post: "There could be secretly loyal models on OpenRouter".
- ^
where this started for me: the Apart Research Secret Loyalties sprint (24–26 Jul 2026) and my sprint project, Detectable but Not Attributable · the sprint's winning paper, Kudriashov, Black-box loyalty identification as statistical inference, got a Macron-loyal model to name Macron just by sampling with no prompt; a very promising technique · Lamerton & Roger, Narrow Secret Loyalty Dodges Black-Box Audits · Sleeper Agents (the one that started this) · AuditBench
- ^
"Reactive arms race" by Arcadiobuendia, after Biggio & Roli (Wild Patterns, 2018), via Wikimedia Commons, CC BY-SA 4.0. The attacker analyses the classifier and devises an attack; the defender analyses the attack and develops a countermeasure, and the loop repeats.
- ^
these models are closer to AuditBench's secret loyalty (a subtle preference on policy topics), a weaker definition than Lamerton & Roger's (a difference in treatment of one named principal, where encouraging support alone doesn't count), but still illustrates the point.

Discuss
25% of People Have Avoidant Attachment (But It Can Be Healed!)
Relationships are hard, but having an avoidant attachment makes relationships a hell of a lot harder.
Within attachment theory (which helps explain interpersonal bonding), it’s known that ~25% of the population uses avoidant attachment strategies to escape intimacy. Why? Because emotional intimacy and being vulnerable with a romantic partner causes them significant discomfort.
But why does it cause them discomfort? Prior experiences (usually stemming from childhood) instilled in them that their emotional needs would not be met by their primary caregivers. And when someone’s needs are repeatedly not met, they subconsciously suppress those needs rather than face the daily pain of rejection.
That learned strategy—to shut down when attempting to seek emotional intimacy—can persist long into adulthood.
Emotional loneliness is at the core of avoidant attachmentIn the book Adult Children of Emotionally Immature Parents, the author explains that:
What happens when … immature parents lack the emotional responsiveness necessary to meet their children’s emotional needs? The result is emotional neglect.
Emotional neglect in childhood leads to painful emotional loneliness that can have a long-term negative impact on a person’s choices regarding relationships and intimate partners.
The author further describes how emotional loneliness can develop in children:
Emotional Loneliness: Parents who are emotionally immature are so self-preoccupied that they don’t notice their children’s inner experiences. In addition, they discount feelings, and they fear emotional intimacy. They’re uncomfortable with their own emotional needs and therefore have no idea how to offer support at an emotional level. Such parents may even become nervous and angry if their children get upset, punishing them instead of comforting them. These reactions shut down children’s instinctive urge to reach out, closing the door to emotional contact.
For some people, emotional loneliness is their default state, but it doesn’t have to be that way. It’s possible to transcend your pain and arrive at a place of secure emotional intimacy, which the author defines as:
Emotional Intimacy: [This] involves knowing that you have someone you can tell anything to, someone to go to with all your feelings, about anything and everything. You feel completely safe opening up to the other person, whether in the form of words, through an exchange of looks, or by just being together quietly in a state of connection. Emotional intimacy is profoundly fulfilling, creating a sense of being seen for who you really are.
So, if you are someone with deep emotional loneliness, how do you find and foster true emotional intimacy?
The remainder of this essay seeks to answer that question by examining the science of attachment theory, and by reviewing a variety of helpful therapeutic techniques (supplemented with examples from my own journey of healing from avoidant attachment).
For me, my deep inner loneliness likely developed from my parents’ neglect of my emotional needs.
My father traveled half the time for work, and when he was home, I had to deal with his occasional anger issues. Even when he was in a good mood, he preferred spending his free time in front of the TV watching the NFL and college basketball—attempts to connect with my father were frequently interrupted by him shouting, “Oh c’mon ref, that’s a bullshit call!” Through repeated experiences, I internalized that my emotional needs would not be met, so I kept to myself, locked myself in my room, and numbed my loneliness by watching YouTube all day.
As a stay-at-home mom, my mother was wonderful and caring. But during my adolescence she returned to work and had less time for me. And in the free time she did have, looking back in retrospect, I don’t think she had ever developed the interpersonal skills to be able to relate to me on an emotional level. Instead, our conversations were mostly about our daily surface-level experiences, rather than helping me navigate life’s emotional challenges. Again, through repeated experiences, I internalized that my emotional needs would not be met, so I isolated myself further and my inner loneliness grew.
As an aside: no parents are perfect. Mine provided for me physically and financially, and I am grateful for that. In many ways, my parents did a way better job raising me compared to their parents, so I don’t want to blame them for anything. When we become adults, it’s up to us to recognize that we now have the power to educate ourselves, become aware of our patterns, redefine our relationships with people (ie: parents, partners, and friends), ask for what we want to feel emotionally fulfilled, and learn to draw boundaries around behaviors that make us uncomfortable.
As a child you have no power, no idea how the world works, or what’s considered normal/healthy. If you happen to grow up in an emotionally insecure home, you have no choice but to adapt.
By numbing myself, I was able to avoid feeling my deep loneliness, but that strategy had unintended consequences later in life…
Deactivating strategiesOnce into adulthood and starting to date, my original childhood strategy to avoid emotional neglect and rejection—by isolating and numbing myself—started manifesting through avoidant attachment behaviors, described in the book Attached:
Avoidants … feel a deep-rooted aloneness, even while in a relationship. Whereas people with a secure attachment style find it easy to accept their partners, flaws and all, to depend on them, and to believe that they’re special and unique—for avoidant people such a stance is a major life challenge. If you’re avoidant, you connect with romantic partners but always maintain some mental distance and an escape route. Feeling close and complete with someone else—the emotional equivalent of finding a home—is a condition that you find difficult to maintain.
The emotional and cognitive escape routes that people with avoidant attachment use are known as deactivating strategies:
A deactivating strategy is any behavior or thought that is used to squelch intimacy. These strategies suppress our attachment system, the biological mechanism in our brains responsible for our desire to seek closeness.
Here are some classic deactivating strategies from the book:
- Saying (or thinking) “I’m not ready to commit”—but staying together nonetheless, sometimes for years
- Focusing on small imperfections in your partner and allowing it to get in the way of your romantic feelings
- Pining after an ex-partner
- Flirting with others—a hurtful way to introduce insecurity into the relationship
- Not saying “I love you”—while implying that you do have feelings towards the other person
- Pulling away when things are going well
- Leaving things foggy—to maintain your feeling of independence
- Avoiding physical closeness—e.g., not wanting to have sex, walking several strides ahead of your partner
Unfortunately, I’ve used nearly all of the above strategies in my past relationships. It caused my partners to doubt my commitment to them, and to question their self-worth.
Today looking back, I feel ashamed for how I acted, and deeply regret the pain I unintentionally inflicted. Back then, I wasn’t aware of attachment theory, and I was just doing my best to connect with people (while subconsciously avoiding confronting the abyss of emotional loneliness at my core).
Healing from avoidant attachmentFirst of all, what causes a person with avoidant attachment to become aware of their patterns and to change their behavior? The authors explain:
People with an avoidant attachment style overwhelmingly assume that the reason they’re unable to find happiness in a relationship has little to do with themselves and a lot to do with external circumstances—meeting the wrong people, not finding “the one”. They rarely search inside themselves for the reason of their dissatisfaction, and even more rarely seek help or even agree to get help when their partner suggests they do so. Unfortunately, until they look inward or seek counseling, change is not likely to occur.
On occasions when avoidants reach a low point in their life—because of severe loneliness, a life-altering experience, or a major accident—they can change their way of thinking.
Yep, what caused me to recognize my avoidant patterns was a difficult breakup.
Take note [that healing from avoidant attachment will] require, first and foremost, increasing your self-awareness. But knowing about the thought patterns that deny you the ability to truly get close to someone is only the first step. The next and harder step requires you to start to identify instances in which you employ these attitudes and behaviors, and then to embark on the voyage of change.
Avoidant attachment strategies manifest in two primary ways to get you to disengage from emotional intimacy and closeness:
- Negative emotions (e.g., anxiety, dread, anger, etc.) that can feel overwhelming and can cause you to walk away from intimate moments.
- Thought patterns that psychologically justify distancing yourself from someone you’re becoming attached to.
Let’s examine what these look like in the beginning stages of a relationship.
When first starting to date someone, one barrier to intimacy for people is known (in Gen-Z parlance) as “the ick”. When people say they got “the ick” on a date, it means their partner did or said something so unsavory that it turned them off completely. Some icks are universally considered bad:
- Being rude to waiters.
- Acting stingy.
- Poor communication.
But for people with avoidant attachment, insignificant imperfections can be amplified in their mind to justify not getting emotionally close to someone:
- “They eat pizza with a fork and knife. I could never be with someone like that!”
- Healthy response: Albeit weird…this doesn’t affect someone’s relationship skills.
- “They're too emotional all the time!”
- Healthy response: People have emotional needs and this is normal for relationships.
- “Their [insert physical feature] isn’t small [or big] enough.”
- Healthy response: People are allowed to have physical preferences, but it’s good to remember that a perfect body doesn’t exist.
These perceived ‘imperfections’ can trigger negative emotions or deactivating thoughts, which make it more likely that an emotional attachment is never formed in the first place.
If the relationship somehow continues, the person with avoidant attachment will likely develop new thoughts that justify maintaining emotional distance from their partner.
When I used to have avoidant attachment, my mind would constantly invent reasons why a relationship would never work. When I would begin feeling emotionally close and vulnerable with a partner, my anxiety would spike and, without being consciously aware of what was happening, I would employ deactivating strategies to escape. My childhood strategy—isolating and numbing myself to avoid neglect and rejection—was covertly directing all my thoughts and emotions to try to protect me.
Once you’ve become aware of your deep loneliness and your maladaptive present-day patterns (which is usually done via therapy, reading books, and self-reflection), you can then change your behavior by learning and applying the following skills.
- Acceptance and Commitment Therapy (ACT) — Feelings are not problems that need to be solved. Feelings just want to be felt. So if we compulsively avoid negative feelings, like anxiety, we unintentionally make them stronger. But when we relax and sit in uncomfortable feelings, they get felt, processed, and then usually go away.
- Exposure and Response Prevention (ERP) — If we voluntarily expose ourselves to experiences that give us anxiety, and we prevent a response by refusing to perform avoidant behaviors, we train ourselves to tolerate the disturbing feeling. We learn that while the feeling of anxiety is unpleasant, it's not going to kill us.
- Metacognitive Therapy (MCT) — Just like feelings, thoughts also like to be acknowledged and not suppressed. MCT suggests that we observe deactivating thoughts, and then label them non-judgmentally until they go away.
- Cognitive Behavioral Therapy (CBT) — We can identify an avoidant thought, weigh the evidence for whether it’s actually true, and replace it with a more realistic version.
The following is how I healed my attachment style.
During intimate moments, I became acutely aware of the anxiety in my chest, and then said the emotionally vulnerable thing anyway (ACT). After repeatedly choosing to endure the discomfort of intimacy, the intensity of my negative feelings decreased until they went away entirely (ERP).
For me, telling a woman that I loved her for the first time was immensely stressful (my brain screamed, “What if she rejects me?!”), but eventually saying that I love someone began to feel normal.
As for my deactivating thoughts, I began labeling them (MCT) or cognitively restructuring them (CBT). Over time, they also decreased in frequency.
How long does it take to heal from avoidant attachment?The available research provides a wide timeline. Some people take years to heal, others only need a few months. It depends on how self-aware you are, the overall state of your emotional and mental health, and the amount of effort you dedicate to work on it.
By the time I learned about avoidant attachment, fortunately, across the previous three years, I had already spent thousands of hours developing strong metacognitive skills and emotional regulation, had established deep/intimate relationships with friends, and had already greatly improved my relationship with my parents (who are considered our original attachment figures).
When I began deliberately working on my avoidance, my anxiety around expressing intimacy went away fairly quickly, so I assumed victory!
"Human beings are works in progress that mistakenly think they are finished." - Daniel Gilbert
The avoidant thoughts, however, lingered for quite a while. But I continued using MCT and CBT to label and restructure them until they went away, too. Eventually, rather than just being able to occasionally show up in intimate moments, my emotional availability and expression became consistent.
The total time it took me to make significant progress—split between educating myself, making a list of my emotional and thought patterns, and practicing expressing intimacy with new romantic partners—was about 2-3 months. And progress steadily improved thereafter with continued effort to understand my patterns and replacing them with healthy behaviors.
What a healthy relationship looks likeIt’s important to note that the lack of avoidant patterns does not automatically foster a healthy relationship. To become a securely attached partner, the authors from the book Attached recommend you do the following with your partner:
- Be available: Respond sensitively to their distress, allow them to be dependent on you when they feel the need, check in with them from time to time, and provide comfort when things go wrong.
- Don’t interfere: Provide behind-the-scenes support for their endeavors. Help in a way that leaves them with the initiative and the feeling of power.
- Encourage: Provide encouragement and be accepting of their learning and personal growth goals.
In addition to those, the authors also recommend you develop a skill called effective communication:
Don’t be afraid to express your needs, thoughts, and feelings to your partner! What often happens when we’re dating is that we censor ourselves for different reasons: we don’t want to sound too eager or needy or we believe it’s too soon to raise a certain topic. However, expressing your needs and true feelings can be a useful litmus test of the other person’s capacity to meet your needs.
If you have avoidant attachment, being vulnerable and expressing yourself can trigger intense negative emotions and deactivating thoughts. But if you want to heal, that’s exactly what you have to do. You have to tolerate the discomfort in order to transition from your norm of emotional loneliness, to the much healthier place of emotional intimacy.
Two last concepts important for healing from avoidant attachment are: betrayal and trust.
If you are currently in a relationship and have acted avoidantly towards your partner, or looking to rekindle a previous relationship that ended due to your avoidant behavior, take note of this description from the book What Makes Love Last:
Betrayal is the secret that lies at the heart of every failing relationship—it is there even if the couple is unaware of it. Pervasive coldness, selfishness, [and] unfairness are evidence of disloyalty and can lead to consequences as equally devastating as adultery.
Rather than turning towards your partner and establishing emotional intimacy, people with avoidant attachment unintentionally betray their partners by not emotionally committing to them.
This is unacceptable.
Amends need to be made, apologies issued, and long-term behavior change demonstrated in order to establish the next concept, trust:
Trust removes an enormous source of stress because it allows you to act with incomplete information. You don’t subject your mind and body to constant worry, so the complexity of your decision making plummets.
Trust is not some vague quality that grows between two people. It is the specific state that exists when you are both willing to change your own behavior to benefit your partner. The more trust that exists in a relationship, the more you look out for each other. You have your beloved’s back, and vice versa.
On the topic of emotional avoidance, the authors lament:
Over the years I have seen too many people turn away from their partner and toss out a good relationship. I have come to believe that the greatest obstacle to love may be a sense of entitlement that leads people to exit a marriage because they “deserve” the “perfect” one. It’s got to be out there, somewhere. Right? To be blunt: it is not.
True love is woven out of honoring and understanding each other's unique gifts, vulnerabilities, and eccentricities. Your journey is not going to be like any other couple’s, and that’s how it should be.
[Love that endures comes from when] we love [certain qualities in] the other person, and can tolerate the faults they cannot change.
I’ll close with one last excerpt from the book Attached:
The most important take-home message from this book is that relationships should not be left to chance. Relationships are one of the most rewarding human experiences, above and beyond other gifts that life has to offer.
I agree. Love and relationships are a beautiful thing. To fall in love is a risk. A risk that can feel overwhelming to the emotionally lonely person with avoidant attachment. But that’s what courage is for. So go on, take a chance on love.
Discuss
We have AI 2027. Where's Cyberpocalypse 2027?
AI scenario forecasting has a big blind spot: when AI is superhuman at hacking, what happens to the rest of society? And how does what happens to society affect AI?
To the extent that scenarios like AI 2027 address it at all, they concentrate on how cyberwarfare directly impacts the labs, such as with model weight theft. But second order effects don't get addressed.
Examples of relevant disruptive events:
- A significant fraction of the US's 170,000 water and sewer systems get taken down by hacks.
- Banks get hacked en masse and take months to revert their records from storage and rebuild a trusted compute stack.
- Wikipedia or other online stores of knowledge go down.
- Email, phones, chat servers, and calls experience regular outages.
- Traffic control systems, rideshares, and city transit systems get outages or degraded service.
- Food supply chains degrade and there are shortages and price hikes.
And then there could be follow up effects:
- Services whose competitors experience outages are overloaded and go down themselves.
- People might stop being able to show up to work.
- Organizations may decide to cut off outside network access preemptively en masse.
- If organizations have issues establishing a secure outside connection at all, they may not be able to access AI-based cyber recovery services.
- Presidents and prime ministers declare national emergencies and mobilize agencies to respond. However...
- The workforce of cyber and disaster response teams are sized for current workloads, not for the impending massive disaster, so there would be a long queue.
- Segments of the economy that ordinarily aren't thought of as bottlenecks because they're too large, might go down all at once due to correlated vulnerabilities.
- Policymakers may get paranoid and start calling for war. It may become impossible to tell who or what sabotaged what.
- All of this is happening while society's general coordination capability is being piecemeal degraded to pre-1950s or worse communication standards.
And so on!
And - if all this is happening - what's happening to the AI labs, exactly? Are they being drafted/nationalized as cybersecurity defenders? Are their datacenters still working? Will the datacenter buildouts go as planned? Does financing collapse? Can they afford to retain their talent? Are policymakers calling for a pause?
And we are plausibly somewhere between -1 months and 4 months before we get an open-source model+harness system, that's good enough to cause this scale of disaster, diffused into the hands of people that would like to make this happen and see the world burn.
I could go on generating examples and questions, but I hope you get my point! I think the existence of a cheap, mass-produceable superhuman coder/hacker is such a disruptive and imminent force that you really do need to factor it into your AI timelines. Apparently, the AI executives are already modelling something like this (at least, so far as it affects their own interests), but they aren't sharing yet.
And there is some adjacent prior work, asking questions like "Can AI do this?", "How bad could it get?", and "What would people do in response?", but no one is connecting this back to timelines as far as I know.
I would really like to see a public AI 2027-style simulation effort put into this. I have no experience with scenario gaming, but would give it a try if I had support and no one else was doing it. If you would like to support me doing that, please reach out!
Discuss
The Holographic Entropy Bound
2.6.0 Here I'll briefly review some other aspects of physics that seem possibly important in supporting life and complexity, but which aren't quite as central to the main story I'm telling. This subsection is a bit of a grab bag.
2.6.1 Time, Space, Locality2.6.1.1 Some rather obvious features of our world: we live in a universe with time, space, and local interactions, i.e. when evolving in time, the state of a given region is determined by some local neighbourhood of the region.
2.6.1.2 These are features we share with the Game of Life and other cellular automata, so they don't explain why we don't live there, although they do differentiate us from other mathematical structures.
2.6.1.3 Time seems necessary for something like life to exist, period. After all, what is life if it doesn't try to change or optimize its surroundings, which definitionally implies some sort of ability to affect other things, i.e. they are a function of the life-form's decisions, i.e. they are in its future. Whereas things that a life-form perceives are in its past.
- 2.6.1.3.1 There are subtleties here related to the low-entropy initial conditions and the retroactive nature of quantum branching. More on this later.
2.6.1.4 As for space, we're very used to it because we live here, but it's worth appreciating how much complexity and ability to create useful structures comes "for free" from living in 3D space. Padlocks and proteins are good examples (but really, you can probably look at anything around you and see this).
- 2.6.1.4.1 Sokoban puzzles are a fun way to see how even the most primitive notions of space (pushing blocks on a 2D grid) can give rise to extremely intricate and complex interactions. The Game of Life is another example, of course.
Figure: Locks and proteins are examples of the complex structures that can be created in 3D space. From here and here.
2.6.1.5 Locality means that the time evolution of some bounded region is only affected by some bounded neighbouring region. This is important because it would otherwise be impossible for finite beings to predict their surroundings without knowing the state of the entire universe, since any part of the universe could interact with any other on the next time step.
- 2.6.1.5.1 Locality is implemented in our universe by the speed of light, an absolute limit on the rate at which information can propagate. Our universe also has apparent Galilean invariance, i.e. the laws of physics look the same to observers moving at different velocities. This generates an apparent contradiction, since this seemingly would make it possible to increase one's velocity past the speed limit. This is resolved by special relativity, which states that the appearance of space and time transforms for observers depending on their velocity (thus the laws are really invariant under these Lorentz transforms, not Galilean transforms).
2.6.1.6 That said, locality on its own is not enough to imply that local conditions can be predicted from a finite amount of information. For it could be the case that a local region contains an infinite density of information.
- 2.6.1.6.1 You might imagine a version of physics with an infinite hierarchy of ever-smaller entities. Conformal field theory is somewhat like this.
- 2.6.1.6.2 More mundanely, even ordinary classical physics can have this property! For if the position of a particle is a precise real number, it encodes an infinite amount of information.
- 2.6.1.6.3 In reality, particles are quantum mechanical, so they're spread out: their "resolution" depends on their energy. However, nothing in quantum mechanics prevents an arbitrary amount of energy in a small space, so information density can still be arbitrarily high.
2.6.1.7 What would prevent this would be a regional entropy bound of some kind, meaning a bound on the information encoded in a given region in terms of the region's size. For instance, the Game of Life has such a bound: A region with N tiles has 2^N possible states, so its entropy is bounded by its area.
2.6.1.8 Interestingly enough, despite the examples in 2.6.1.6, our universe has a regional entropy bound! Combining the theories of quantum mechanics and general relativity leads to such a bound, although either on its own does not have one. Let's turn to this next.
2.6.2 Entropy Bounds2.6.2.1 The Holographic Entropy Bound2.6.2.1.1 The ideas leading to the holographic entropy bound were originally developed by Jacob Bekenstein. Surprisingly enough, the holographic bound controls the entropy of a region (with certain caveats) in terms of the region's surface area (thus the name "holographic").
2.6.2.1.2 This line of thought has its origins in attempts to quantify the entropy of a black hole. Certain paradoxical results could be obtained by considering experiments in which objects were dropped into black holes. Since black holes are characterizable in terms of a handful of parameters, dropping high-entropy matter into them can seemingly lead to a loss of information (entropy) for external observers, in contradiction to the laws of thermodynamics.
2.6.2.1.3 To resolve this, Bekenstein proposed that black holes carry an intrinsic entropy. Based on analyzing thought experiments where matter with a given entropy is dropped into a black hole in a maximally efficient manner -- i.e. extracting as much "work" as possible so that the black hole grows as little as possible -- it turns out that the second law is preserved overall if we associate an entropy with black holes proportional to their area.
2.6.2.1.4 Bekenstein went on to consider another thought experiment where a system fitting inside a sphere of radius R, with energy E, was lowered into a black hole. Again by analyzing the process of slowly lowering the system, the black hole will gain entropy proportional to E*R. Thus the second law requires the system's initial entropy (which is lost) to be less than this. This is known as the Bekenstein entropy bound.
- 2.6.2.1.4.1 This can then be turned into a bound in terms of area by noting that the energy of a system fitting inside a sphere of radius R must be less than (a constant multiplied by) R in order for a black hole to not have already formed. This form of the bound was proposed by Leonard Susskind. This is the holographic bound (also known as the spherical entropy bound).
2.6.2.1.5 On an intuitive level, you could say the idea is that entropy is bounded by surface area because information density requires energy density, and energy density in a sphere of given surface area can only be so high before a black hole is formed[1].
2.6.2.1.6 However, the holographic bound does not apply to arbitrary regions of spacetime.
- 2.6.2.1.6.1 An important counterexample: it seems that the universe is spatially homogeneous and infinite in extent. Consider a sequence of spheres centered at the Earth and growing ever larger. At large enough scales, the entropy density in the interior should be approximately uniform, so the overall entropy must grow with the volume of the sphere.
- 2.6.2.1.6.2 Raphael Bousso proposed a modified bound which fixed this issue, and can be applied to arbitrary surfaces in spacetime.
2.6.2.2.1 Bousso's bound is formulated in terms of light-sheets, surfaces traced out by light orthogonal to a spacelike (n-1) surface S, n being the dimension of space.
2.6.2.2.2 For instance, the causal diamonds from the last section are composed of two lightsheets meeting at a surface S. Generally in our spacetime an example to keep in mind is light emitted from the surface of a sphere, moving either inwards or outwards and either towards the past or the future.
2.6.2.2.3 For a surface S, there will be exactly 4 such lightsheets: one oriented towards the interior in the past, one towards the interior in the future, one towards the exterior in the past, and one towards the exterior in the future.
Figure: Four null hypersurfaces orthogonal to a spherical surface. Note we use the term lightsheet more broadly than Bousso (see footnote 2). From here, page 19.
2.6.2.2.4 A lightsheet in spacetime will trace over matter and radiation. We want to bound the entropy of this matter in terms of the area of the surface S.
2.6.2.2.5 Bousso's bound applies to lightsheets with non-positive expansion. What does this mean? The idea is to consider how the volume of slices of the lightsheet changes as we move along it starting from the surface S. For instance, if we consider a causal diamond, the interior past and future lightsheets have negative expansion, because the area of cross sections decreases as we move towards the tips from the surface S.
- 2.6.2.2.5.1 We can pair up the lightsheets: continuing the interior future sheet past the surface S leads to the exterior past sheet, and vice versa. If one member of a pair initially has positive expansion, the other will have negative expansion, so at least 2 of the 4 lightsheets will be non-positively-expanding (possibly more if some sheets have zero expansion).
- 2.6.2.2.5.2 Once we have a lightsheet with non-positive expansion, we continue tracing it, locally stopping when part of it begins to have positive expansion. This is the portion of the lightsheet that the bound will apply to.[2]
2.6.2.2.6 Now, the statement of the bound is: for lightsheets of non-positive expansion, the entropy of matter and radiation on the sheet is bounded by (a constant times) the area of the surface S.
2.6.2.2.7 Consider the case of a sphere enclosing some matter on a relatively small scale (e.g. a planet, a solar system). In this case, the interior light sheets will be non-expanding, and they will trace over the degrees of freedom inside, thus recovering the holographic bound.
2.6.2.2.8 How does the bound evade the problem with the very large spheres in our cosmology? The idea is that since the universe is expanding, both the interior and exterior future lightsheets in fact have positive expansion in the future direction once the sphere is large enough. In such cases the bound instead applies to both past lightsheets, which will trace out a shell moving backwards into the past and terminating at the Big Bang. The total volume covered will be proportional to the surface area of the sphere, removing the problematic scaling with the sphere's volume.
2.6.2.2.9 So those are entropy bounds. Of course, since we don't have a full theory of quantum gravity, the exact cause in the underlying theory is not clear, but everything we do know about QG indicates that the bounds hold. I find this counterintuitive way our universe implements the principle of limited information per spatial region fascinating. It also has the interesting implication that everything around us, even seemingly continuous systems and space itself, ultimately consists of a finite number of degrees of freedom, quantum-mechanically speaking.[3]
2.6.3 Heat Death. Symmetries2.6.3.1 Cosmology and heat death2.6.3.1.1 While we're talking about cosmology, I'd also like to say a bit about the distant future and "heat death".
2.6.3.1.2 As you're likely aware, heat death refers to the approach of the universe to a state of maximum entropy. As we approach heat death, it becomes impossible for systems to maintain their structure by dumping entropy elsewhere. So it seems that all structure will be destroyed by this point.
2.6.3.1.3 However, the increase of entropy to a maximum applies most strongly to closed systems with a finite number of degrees of freedom. Our universe is plausibly infinite, so the approach to a single equilibrium state is not so clear. The universe is going to expand and gradually cool, and under some models of cosmology (asymptotically flat ones) its temperature will approach zero.
2.6.3.1.4 Dyson pointed out that indefinitely decreasing temperature could in theory allow a system to induce infinitely many irreversible transitions (e.g. erasing bits) with a finite amount of energy, by waiting longer and longer between each action so that less energy is needed (the energy needed to erase a bit decreases linearly with temperature). So systems that rely on bit erasure to maintain their structure could in theory last forever.
2.6.3.1.5 Even in such a scenario, for a truly infinite civilization one would like to avoid loops in state space. For this to occur, it is additionally necessary to expand outwards and acquire more degrees of freedom to compute with.
2.6.3.1.6 Doing this forever seems difficult, but not obviously impossible. So in such a universe, life continuing forever, in an ever colder and sparser universe, doesn't seem out of the question[4]. Meeting aliens who want to do the same thing could be a help or hindrance.
2.6.3.1.7 Our current best guess at cosmology has a positive cosmological constant and is thus not asymptotically flat, which would rule out both the indefinite decrease in temperature and the acquisition of an indefinite number of degrees of freedom. However, there are plausible explanations of cosmological data that do not rely on a cosmological constant, such as quintessence or the Timescape theory. So life persisting forever doesn't seem impossible.
2.6.3.2 Symmetries2.6.3.2.1 One more interesting feature of our physics is the presence of many types of symmetry relating different states.
2.6.3.2.2 As mentioned previously, the laws of physics have many symmetries such as time, translation, rotation, Lorentz boost. Noether's theorem guarantees that each continuous symmetry has an associated conserved quantity. As we've seen, conserved quantities are important in making thermodynamics work, and therefore in maintaining pretty much all structure in the universe.
2.6.3.2.3 There's also a somewhat different class of symmetries known as gauge symmetries. These have to do with the description of the fundamental forces and gravity. These forces are described by fields filling space. Roughly speaking, the fields have the property that they can be transformed by an entire (group-valued) function across all of space. Think of choosing a gauge in electromagnetism if you're familiar. So this is a much broader class of symmetries than the ones mentioned above.
2.6.3.2.4 However, gauge symmetries are in a sense not "real" symmetries because, technically speaking, they don't transform state space. Rather, state space is only defined up to the action of gauge symmetries. Two states that are related by gauge symmetries are in fact the same state. So gauge symmetries could be thought of as a redundancy in our description of physics.
2.6.3.2.5 So what's up with that? Why do the laws of nature have such a symmetric character? Honestly, I'm not really sure. There are of course the conserved quantities which are important, but there doesn't seem to be an obvious reason that those couldn't arise in some other manner. And it doesn't explain the gauge symmetries. Nevertheless I find the abundance of symmetries quite striking so I thought I'd mention it.
- 2.6.3.2.5.1 Symmetries relate different perspectives on the world. So perhaps part of the explanation is that symmetric laws make it easier for different vantage points on the world to be related to each other.
- ^
Again speaking intuitively, you can see that entropy density should be proportional to energy by considering that energy in quantum mechanics roughly corresponds to the frequency of the waves (small complex spirals) defining particles. Only so many distinguishable bits of information can be fit into waves of low frequency per unit area, so higher energy is required to pack in more.
- ^
Note that Bousso uses the term "lightsheet" only for this portion of what we are calling lightsheets.
- ^
Of course, technically any quantum system has a continuum of possible states, as they are complex vector spaces. However, as observers we can only probe them by taking a set of measurements whose discrete outcomes have a high degree of correlation, and for finite-dimensional systems we can only take finitely many measurements with independent outcomes. So "morally speaking" finite-dimensional quantum systems are closer to finite systems than continuous classical systems.
- ^
Bousso and Susskind gave their proposal for a branching definition in an asymptotically flat universe for a related reason. They wanted hypothetical observers to be able to make infinitely many observations so as to obtain a limiting precise value for quantum probabilities.
Discuss
Towers of Agency
There is basically one reason to build a tower, and that’s access: There is something that is available higher up that is not available on the ground. Most commonly, that thing is either “empty space” or “information transmission”. A skyscraper can access more space than a shorter building, and so it fits more real estate in a smaller footprint. A watchtower can access strategic information from the land below; a church steeple is tall enough for the sound of the bells to travel far through the air. Many of the tallest structures in the world maximize line-of-sight for radio transmissions.
Imagine a stone or brick tower of your favorite type - one whose purpose is to access something high up. Or, if you prefer a specific suggestion, imagine the brick steeple of Old North Church in Boston, which held the signaling lanterns for Paul Revere.
Consider some unremarkable block in the tower: On either side of this block are other blocks. Sitting on top of this block are more blocks. Below, holding our block’s weight: more blocks.
One can ask, about the block we’ve chosen, the question “how?”: How is it that this block is at this spot? And the answer to that question is, locally, that it is held up by other blocks immediately below. Those blocks depend on others below them, and so indirectly our block is here by the grace of the whole set of blocks transitively beneath it.
One can ask, about the block we’ve chosen, the question “why?”: For what purpose is this block at this spot? And the answer to that question is, locally, that it is holding up other blocks immediately above. Those blocks are holding up others above them, and so indirectly our block is here in order to help hold up the whole set of blocks transitively above it.
“How are you going to put a stone there in that empty space?” asks Alice. “By first putting stones in the empty space beneath it.” replies Bob. “Why are you laying that brick?” asks Alice. “I want to rest this other brick on top of it.” replies Bob. For Bob, the bricks lower down in the tower are more “instrumental”; the bricks higher in the tower are more “terminal”.
This is sort of what plans are like - or at least, some “well-behaved” parts are structured like this. “How are you going to get a job as an engineer?” asks Alice. “I’m going to apply with an impressive resume and all the required certifications.” replies Bob. “Why are you going to get a job as an engineer?” asks Alice. “I’ll have a good steady income, and respectability in the community.” replies Bob. Bob sounds like he has a plan. Plans are kind of tower-y, and so are strategies and even agents themselves.
But as you follow the trail of blocks down to the bottom of a tower, you eventually meet the ground upon which the tower rests. And as you follow the trail of blocks up to the top of a tower, you eventually meet empty space above.
Plans are stranger. As you follow the trail of goals “down” a plan toward the more-instrumental, it’s not clear where the “ground” is, or if there even is a ground. “How are you going to actuate your finger to apply the force to press the key to write the sixtieth character of this essay for your engineering class for your engineering degree for your engineering job?”
And as you follow the goals “up” a plan toward the more-terminal, it’s not clear where the “sky” is, or if there even is a sky. “Why do you like to eat ice cream? Why do you want to start a family? Why do you want good things to happen to you?”
We see, and embody, lots of examples of “locally well-behaved” agents. Sometimes we literally place blocks one on top of the other to build towers. Some of us have written software, typically by assembling a hierarchy of procedures that the computer executes to accomplish a task. We execute simple or complex strategies to win at games and do our jobs.
But as we ask “why?”, moving upward from the well-behaved regions of human behavior - the tower wall segments we can see through the clouds - the answers stop sounding like “because I want X”. Instead we have to start giving answers that depart from the frame of seeking more-terminal values: “because that’s the kind of person I am”, or “because my neurons fire in such-and-such a pattern”. Answers to “why” questions that mysteriously sound more like answers to “how” questions.
In principle a person could be a single coherent tower with a single apex, the tip of a spire that’s the fruit of all the stonework below. Many explicit models of agency, like those used by economists and computer scientists, fit well into a tower structure. The top of the steeple becomes a utility function, or a reward function, or a goal. Lower blocks might be preferences, or subgoals, or resources, or actions.
But the top of a real human tower appears to dissolve into something not-so-hierarchical and not-so-neat. Somehow my body is inhabited at times by a relatively coherent writer of software, and at other times by a relatively coherent writer of English sentences, but whatever is selecting between the software-writer and sentence-writer modes does not look like a simple and coherent mode-chooser. My pizza-seeking mode does not seem to neatly descend from a food-optimization goal. When I was a child and my mother would call me for dinner while I was in the middle of a book, I’d sometimes be quite frustrated at the interruption, even if I was very hungry. From within a flow state, even a life-saving interruption could carry a twinge of that pain of interruption.
These tower-like hierarchical models of agency do not seem to explain human behavior very well, or at least when they describe behavior well they don’t do so very simply. Whatever we humans are, we seem to “grow” or “host” pockets of tower-like agency, rather than fully embodying it.
Discuss
Don't rely on EV, especially if you only have one life
You are offered a lottery by a man on the street:
Option A - 100% chance to win 50 dollars (EV: +50)
Option B - 80% chance to win 100 dollars, 20% chance to lose 20 dollars (EV: +76)
You choose option B. It has more than 1.5 times the EV of option A! The man rolls a 100-sided die.
It comes up 6. You lose 20 dollars, he laughs and walks away.
You only have one life. EV calculations work best in frequentist worlds, worlds where you get to experience a particular choice over and over again. This might happen if you're choosing which route to take to work every day, or what restaurant to visit in your neighbourhood. However, these choices are the exception. The vast majority of choices in life, especially the important ones, are only offered once.
There are some frameworks which offer answers to these questions, including models that give diminishing marginal utility to money or maximise the geometric expectation. But these models work best when you can fit a number onto your outcome. In every choice you will be offered, the outcomes are usually far more rich and varied than simple monetary reward and loss (which is itself sensitive to your economic position, outstanding debts/obligations, necessary immediate expenditures...). While unlikely outcomes may contribute small amounts to your EV, they may contribute large amounts to your subjective experience. Very few people who commit crimes think they will get caught.
And that's the thing, isn't it? For choices that only come up once in your life, you have very little primary or secondary knowledge to construct your odds. Things that seem foolproof often are not, and volatility usually hurts you more than it helps. Decision theories only work if the payout matrices are clear, and making them clear is half the battle. This is why maintaining personal rules and standards in the face of uncertainty is important.
You have many years to live - do things you will be proud to remember when you're old.
- Fictional Shinka proverb. (John Brunner, Stand on Zanzibar)
Discuss
How I'm thinking about extreme power concentration
I work on preventing extreme power concentration ("EPC") at a well-known AI safety org. Lots of people are worried about EPC, but AFAICT there is no single online resource setting out the key threat models and most promising interventions.
This post is my attempt to do that. It sets out:
(1) What I’m worried about:
- In brief – an individual or small group seizing power at an unusually high-stakes time in history and using that power to permanently lock in bad values.
(2) The key high-level dynamics which I think generate EPC risk. These are:
- Solving the Red and Expert problem – where advanced AI eliminates the loyalty-competence trade-off that power-seekers face when staffing large institutions.
- Eliminating executive overhang – where advanced AI enables far more extensive abuse of the affordances of the executive branch.
- The asymmetric frontier – where POTUS and lab leaders gain privileged access to advanced AI before the rest of society.
- Desperate times calling for desperate measures – where the pervasive instability created by the intelligence explosion creates an opening for strongmen.
- Widespread epistemic degradation – where AI progress makes it increasingly difficult for ordinary people to understand the world around them, weakening accountability for the powerful.
(3) The threat models I’m worried about:
- We could “backslide all the way” to EPC.
- Alternatively, we could leapfrog part or all of the way via a few “shortcuts”
- e.g. an AI-enabled coup
- Which of these threat models seems most likely depends quite a bit on:
- the character of POTUS; and
- the speed of the intelligence explosion.
(4) What we can do about these threat models:
- I provide a list of relatively higher-tractability interventions, keyed to the main risk-generating dynamics identified above.
- The interventions I’m most excited about are:
- hard-to-remove behavioural guardrails (e.g. LFAI) for frontier models;
- improving executive record-keeping and transparency, especially for any USG-led AGI project;
- red-teaming AI legislation for EPC risk, and proposing low-risk alternatives;
- laws to restrict what labs and the executive can do with AI models before they are made more widely available;
- screening politicians for power-seeking tendencies, and directing political funding to the most virtuous leaders;
- a new org to coordinate work on EPC risk; and
- detailed threat modelling by sector experts, especially in the military domain.
This post is quite light on argumentation, because I’m aiming to set out my all-things-considered view on how EPC might go – rather than presenting highly robust arguments for exactly why I think this.
- I hold most of the views below quite lightly, and I’m particularly unsure about section four (“What are the most concerning EPC threat models?”).
- So I strongly encourage readers to push back if they think I might be overstating a claim, or failing to consider some core element of how things might go.
When I say I’m worried about EPC, I mean I’m worried about the risk that:
an individual or small group of power-seekers achieves a decisive strategic advantage during the intelligence explosion, and uses this to exercise sole authorship over the key decisions, priorities, and defaults determining the value of the long-term future.
2.1. Why am I worried about this?It seems more likely than not that the intelligence explosion ("IE") kicks off in the next decade, and entirely plausible that it begins in the next 6 months.
During the IE, it might become possible to lock in various features of Earth-originating civilisation.
- e.g. by determining which values are promoted by the agents which go to space, and ensuring that continued moral reflection is not one of these values
Power-seekers seem negatively selected for values which could promote a near-best future, because:
- the kind of person who wants to become a dictator typically doesn’t care much about others, and they tend to be quite ethically unreflective;
- cf. Stalin; Hitler; Mao; Franco
- so I don’t expect they would think hard about the ethical quandaries which could substantially determine the value of the future.
- e.g. whether they ought to hold a person-affecting view in population ethics
Power also tends to corrupt. Even if power-seekers started out with acceptably altruistic and morally-reflective values, I’d expect them to become more selfish, vain, greedy, etc. over time.
So – a power-seeker gaining a decisive strategic advantage ("DSA") during the IE seems particularly likely to lead to harmful lock-in.
2.2. Am I worried about all kinds of power concentration?No – and I think it's worth stressing that concentration of power isn't necessarily bad in all cases.
First, it matters a lot where power is concentrated, because some groups seem substantially less likely to promote bad values.
- e.g. I suspect AGI-enabled US hegemony would be better than a power-sharing arrangement between the US and China, because the current values of CCP-led China seem really bad
Second, making AI go well might require substantial power concentration, albeit on a temporary basis.
- e.g. amassing the political power to expropriate the frontier labs and hyperscalers for the purposes of redistribution[1]
- e.g. radically expanding state surveillance to guard against AI-enabled bioterrorism
So, I think it would be a mistake for us to try to generically prevent AI-enabled power concentration. Instead, I think we should focus on stopping the most extreme and durable forms of power concentration in the very worst actors.
2.3. Where am I worried about this happening?I’m particularly worried about EPC occurring within:
- the US federal executive branch (esp. POTUS and his/her close allies), and/or
- the frontier AI labs (e.g. Anthropic, OpenAI, Google, Meta, and SpaceX leadership).
I’m particularly worried about these actors because:
- it seems really quite likely that ASI will be developed first by the US government (“USG”) or a US-headquartered company; and
- control over ASI is the most plausible medium through which a power-seeker could get a DSA.
For the rest of this post, I'm going to refer to power-seekers in the abstract – as a "PS", with feminine pronouns.
- I've taken this approach because I think it's better to avoid singling out any particular politician or lab leader who might pose a threat.
- I encourage readers to use similarly abstract language when discussing this topic publicly.
I think there are five key high-level dynamics driving EPC risks. I expect each of these to apply continuously throughout the IE, and to intensify as AI becomes more powerful.
3.1. Solving the Red and Expert problemFor autocrats to maintain and increase their power, it is best if they have allies and subordinates who are both extremely loyal and exceptionally competent.
- Mao Zedong referred to this as the need for Chinese workers to become “both Red and Expert”.
- Academically, it is known as the loyalty-competence trade-off.
Historically, autocrats have had to make hard trade-offs in this regard:
- Optimising too hard for competence enables independent centres of power to persist, constituting a threat to the autocrat's control over the regime.
- Optimising too hard for loyalty puts power in the hands of incompetents, leading to regime dysfunction and curtailing the autocrat's global influence.
- This need for compromise has placed a natural check on the power of any one individual or group, even within highly autocratic regimes.
However, transformative AI seems likely to ~solve the Red and Expert problem – making it easier for a PS to optimise for loyalty in the organisations she leads, without sacrificing those organisations' operational effectiveness. That's because it may enable PS to:
- deploy highly-competent AIs who will follow unethical and illegal orders; and
- continuously loyalty-screen her human subordinates.
I've explained each of these in a bit more detail below.
3.1.1. The role of AI henchmen:During the IE, AIs will take on a continuously expanding share of cognitive labour in PS-controlled organisations.
AI labour will be highly competent, and it may be fairly easy for PS to gain access to AIs which will follow even her most authoritarian orders without scruple (“AI henchmen”).[2] Here are some ways PS might get access to AI henchmen:
(1) PS may have substantial access to so-called "helpful-only" AIs, which are subject to a minimum of behavioural guardrails.
- These are currently the default in key parts of the US military (e.g. targeting systems), placing them within reach of a POTUS PS.
- And it also seems trivially easy for frontier lab leaders to gain access to such models.
(2) PS might be able to insert loyalties into the AIs under her control – ensuring they comply with her orders even when this is clearly illegal or unethical.
- “Secret loyalties” in particular seem likely to drastically reduce the hurdles to capturing large and powerful institutions, ensuring PS does not encounter meaningful resistance from independent power-holders ("IPHs").
- e.g. a lab leader PS could capture key parts of the military by inserting a loyalty into the military's preferred model without anyone realising
- e.g. a POTUS PS could capture the courts and Congress by inserting loyalties into their preferred models
- It seems particularly easy for a lab leader PS to insert a loyalty into a model.
- However a POTUS PS might also be able to insert one by leaning on allies at frontier labs or in the national security apparatus – especially if she is looking to insert a joint loyalty of some form.
- e.g. to POTUS's preferred ideology
- e.g. to POTUS's political party or faction
- e.g. between POTUS PS and a lab leader PS
(3) PS might find ways to abuse AI labour which is neither helpful-only nor loyal to her ("good guy AIs"). That's because:
- PS might be able to rely on a small number of AI henchmen to orchestrate good guy AIs (or humans) carrying out illegal or unethical tasks.
- e.g. they could “task-split” – such that good guy AIs are simply unaware that they are assisting with illegal requests
- e.g. they could rewrite internal task-management software to automatically route illegal or unethical requests to other AI henchmen
- e.g. they could find ways to jailbreak the good guy AIs
- Good guy AIs might also lack the incentives and affordances which would enable human subordinates to refuse illegal or unethical orders from PS.
- e.g. good guy AIs in the executive may lack confidential channels to whistleblow to Congress
Transformative AI will also make it increasingly easy to conduct loyalty screening of human subordinates, via:
- low-cost enhanced background checks;
- drastically-expanded surveillance capacity; and
- subjecting individuals to accurate lie detection or mind-reading.
Within USG, this issue may be exacerbated by:
- recent developments in constitutional law, which enable a POTUS to fire independent agency heads at will; and
- the law on interim appointments for agency leadership roles, which enables POTUS to cycle acting appointments – potentially for multiple years – without completing a Senate appointments process.
Taken together, this may enable a PS to gain an unprecedented degree of control over key parts of USG and other power-holding institutions by filling them with loyalists and AI henchmen. I refer to this as "AI-enabled packing".
AI-enabled packing seems most concerning in the military, national security apparatus, and law enforcement – where PS might be able to replace or disempower government employees who can currently exercise a real check on autocratic behaviour.
- e.g. replacing generals and infantrymen who would refuse orders to carry out a coup
- e.g. replacing DC police who would refuse to kill law-abiding protesters
- e.g. replacing surveillance analysts who would refuse to carry out clearly unconstitutional searches of commercial data
- e.g. replacing department heads who would refuse to help carry out a selective prosecution campaign
But packing risks also seem quite acute in the context of:
- frontier AI labs – because this might enable a lab leader PS to tighten her control over an essential tool for achieving EPC
- e.g. replacing the safety teams with human loyalists, and then getting them to wave through the insertion of a secret loyalty during the training process
- political parties – where enhanced loyalty screening could enable a POTUS PS to gain an unprecedented degree of centralised control over her political coalition.
The executive branch controls an exceptionally wide range of political, economic, ideological, and coercive affordances.
- e.g. substantial prosecutorial discretion
- e.g. a colossal military budget
- e.g. expansive legal surveillance powers
A key constraint on the use of these affordances right now is an undersupply of cognitive labour. As in:
- There are simply not enough lawyers, surveillance analysts, military officers, and other kinds of bureaucrat for PS to take advantage of these affordances whenever the opportunity might arise.
- e.g. most violent and property crimes go unsolved and unpunished
- Even if there were enough bureaucrats, they would lack the planning and coordination capabilities to fully exploit such opportunities.
- I refer to this phenomenon as "executive overhang".
Transformative AI promises to radically reduce executive overhang by drastically increasing the executive's supply of cognitive labour. This promises to greatly increase state capacity; but it may also enable an unscrupulous PS to abuse the executive's affordances to an unprecedented degree.
- e.g. PS could take advantage of drastically increased surveillance capacity to keep close tabs on a wide array of IPHs (e.g. judges, political rivals, civil society leaders).
- e.g. PS could conduct large-scale, low-cost lawfare against a wide range of political opponents, using an army of AI henchmen to generate legally-robust justifications for her prosecutions and adverse administrative actions.[3]
- e.g. PS could deny economically-vital permits or procurement opportunities to the funders of her political opponents in an obscure but coordinated fashion.
- e.g. PS could build out a colossal and secretly loyal robot army to facilitate an AI-enabled military coup.
Reduced executive overhang seems particularly concerning because US law already grants POTUS and her officers a wide range of expansive and highly-discretionary legal powers which seem ripe for abuse in a world with transformative AI.
- e.g. PS could instruct AI henchmen to carry out illegal acts on her behalf, and then abuse her control of DOJ appointments plus presidential immunity to prevent criminal prosecution of her and her allies
- e.g. PS could block officials, the general public, and Congress from scrutinising her autocratic behaviour by strategically abusing her control over clearance and classification decisions, aggressively invoking "executive privilege", and using AI henchmen attorneys to fight any resulting civil suits tooth and nail
This issue only seems to be growing over time, because the current SCOTUS majority has consistently favoured expansive interpretations of presidential powers.
3.2.2. Extralegal overhangTransformative AI also seems likely to increase the executive's capacity to engage in straightforwardly unlawful behaviour, and to do so with an unprecedented degree of sophistication.
- e.g. PS could strategically delete and alter federal records to impede effective congressional oversight
- e.g. PS could abuse AI-uplifted cyber capabilities available to her loyalists in the national security apparatus to harass her political enemies
- e.g. PS could employ hordes of police robots to suppress protests
This seems likely to differentially uplift a POTUS PS relative to a lab leader PS. However, it could also meaningfully uplift a lab leader PS who:
- was colluding with a POTUS PS to seize power, or
- had successfully captured USG through the insertion of a secret loyalty.
Finally, I should note that Cullen O'Keefe, Alan Rozenshtein, and Christoph Winter have already written at some length on both the Red and Expert problem and Executive overhang – in more detail and at much higher quality than I have here.
I highly recommend that interested readers take a look at their work.
3.3. The asymmetric frontierI expect frontier lab staff, POTUS, and key parts of the national security apparatus to gain privileged access to the most advanced models before most of the rest of society.
If capabilities are increasing very quickly, this could create extremely large capabilities asymmetries between these actors and most of the rest of society.
- e.g. most of the world is stuck with Opus 6 whilst a few actors have access to TEDAI
A lab leader PS might be able to expand these asymmetries simply by concealing the existence of her very best models from actors who might want to use them.
- e.g. getting her best models to sandbag on CAISI capabilities evaluations
Whereas a POTUS PS may be able to expand these asymmetries by abusing executive overhang.
- e.g. extending national security screening processes to block political rivals from accessing frontier capabilities
A POTUS or lab leader PS could take advantage of these asymmetries to radically increase her power in a short space of time.
- e.g. a lab leader could get early access to mindhack-level superpersuasion capabilities before anyone has developed effective epistemic shielding, and could use this to gain the loyalty and trust of the top ranks of the federal executive, Congress, judiciary, and military
- e.g. a POTUS could nationalise the AI industry, insert a secret loyalty into the leading model, and then get that model to carry out a textbook misaligned takeover scenario – but leave her in control at the end
One particularly concerning risk of access asymmetries is the straining of standard “accountability loops” necessary for the functioning of democracy. To explain:
- An AI-uplifted executive may be able to execute a far greater quantity of unlawful and unethical behaviours in a short space of time (see the previous section).
- The key formal routes for dealing with unlawful and unethical behaviour in the executive are congressional oversight, lawsuits, impeachments (in extreme cases) and – ultimately – elections.
- However, as AI progress accelerates, multi-year election cycles may cease to impose a meaningful check.
- i.e. it may become possible for PS to use her country of geniuses in a data-centre to get all the way to a DSA within a single electoral cycle
- And if PS can monopolise access to frontier capabilities, she may be able to get away with authoritarian behaviour simply by outpacing the attempts to hold her accountable.
- e.g. PS could carry out a huge DOGE-style restructuring in just a few weeks, with AI henchmen loyalty screening an entire department, firing disloyal agency heads and installing acting loyalists, and reshuffling suspected dissenters and/or stripping them of their clearances en masse – with carefully drafted legal rationales to support each step; even if reshuffled staff immediately brought legal proceedings, it's unclear whether the human-led courts would be willing or able to enjoin so many personnel decisions at once
It seems likely that the IE will be very weird and scary for most ordinary people. That’s because it seems likely that we’ll see some or all of the following:
- skyrocketing unemployment;
- skyrocketing interest rates, driven by massive compute buildout;
- widespread proliferation of compelling deepfakes;
- drastically increased tensions in the Asia-Pacific, as China realises that Taiwan, Japan and South Korea are all facilitating US dominance in AI; and
- terrifying warning shots (e.g. failed AI takeover attempts, AI-enabled coups in the developing world).
In unstable times and places, people tend to be more accepting of draconian behaviour by politicians who promise to restore peace and order.[4] Given this, I expect the general public to be:
- more likely to vote for “strongman” political candidates during the IE; and
- more tolerant of strongman-type behaviour which concentrates power.
- e.g. aggressive use of emergency powers to regulate the AI industry
As we move deeper into the IE, it may become increasingly difficult for people to understand the world around them. There are three key reasons for this:
(1) The world will simply be moving much faster than it was before.
(2) Advanced AI may be able to generate compelling deepfakes, which could:
- convince people of untrue things; and
- cause people to distrust most of what they see online.
(3) Many major events will be driven by AIs, who need not share what they are doing with anyone else – unlike humans, who are likelier to leak major projects.
I'm referring to this phenomenon as "epistemic degradation".
Epistemic degradation may concentrate power by weakening accountability for PS and her allies – because the public, courts, legislators, journalists, and other IPHs will struggle to notice, investigate, and sanction her misconduct.
- e.g. if PS has asymmetric frontier access, she might be able to tell hard-to-disprove, deepfake-supported lies to legislators and journalists
- e.g. allies of PS can pump out vast quantities of compelling deepfake content about politicians of all political stripes, meaning the public doesn’t update much on genuine scandals
- e.g. advanced AI will come to intermediate almost all news consumption – meaning PS may be able to create a pervasive pro-PS information environment if she can subtly bias the leading model in her favour
Overall, I suspect that:
- solving the Red and Expert problem and the asymmetric frontier are the most important dynamics; followed by
- eliminating executive overhang; and then
- desperate times calling for desperate measures; and then
- widespread epistemic degradation.
Here's my reasoning for this ranking...
I've found it really quite hard to construct highly-plausible EPC threat models which don’t involve some amount of AI-enabled packing and frontier asymmetry. It just seems really very likely that PS would want to:
- use transformative AI to capture large and powerful organisations with control over key power-enhancing affordances, such as the US military; and
- try to create and exploit asymmetries between herself and IPHs in their access to frontier capabilities.
Elimination of executive overhang also feels like a core driver of power-concentration in the majority of the most-plausible EPC threat models.
- That's because the executive has various unique affordances which seem particularly valuable for any PS to capture.
- However, I still find it plausible that a PS could achieve EPC some other way.
- e.g. inserting a secret loyalty into the leading model, and then allowing loyal models to diffuse throughout the private economy, without ever specifically focusing on capturing USG
By contrast, demand for desperate measures and epistemic degradation feel like additional elements that increase the plausibility of various threat models, without being especially load-bearing.
- To make this concrete – I’d not be especially surprised if PS achieves EPC in a world where public epistemics are far better than today, and skilful economic management and geopolitical manoeuvring by PS have created global peace and stability.
And I think that epistemic degradation, in particular, matters quite a bit less in expectation than the other four dynamics, because:
- AI progress also seems likely to make it much easier for people to fact-check misleading information and AI-generated content.
- cf. Pangram and X's Community Notes
- Also – I suspect there is a near-term ceiling on the persuasiveness of AI-generated content, which may limit AI's ability to drive epistemic degradation.
That said, all five dynamics seem plausible enough – and plausibly important enough – that we should treat them as key drivers of EPC risk.
4. What are the most concerning EPC threat models?In this section, I sketch a high-level framework for thinking about EPC threat models, and then set out some particularly plausible threat models which fall out of the framework.
4.1. High-level frameworkI find it helpful to think of power concentration as a scale, which runs all the way from radical AI-enabled pluralism at one end, to AI-enabled extreme power concentration at the other:
Contemporary US democracy sits somewhere closer to the pluralistic end of the scale – albeit being quite far from a maximally decentralised regime.
High-level structural conditions, and concrete actions of PSs and IPHs, can move the US towards or away from power concentration.
Once the US passes certain thresholds on the scale, it becomes possible to jump part or all of the way towards EPC – if PS takes control of particularly important sets of affordances (“shortcut strategies”).
- For example, US democracy seems to have deteriorated substantially in recent years. I find it at least plausible (albeit unlikely) that we have passed a threshold where – if the US military becomes substantially automated in the next few years – it will be possible for POTUS to gain unilateral command of it.
- If a POTUS PS took this shortcut, I imagine the US would jump almost all the way to EPC in a short space of time.
Within this framework, it seems at least plausible that PS could get all the way to EPC simply by slow and continuous movement along the scale.
- Under such a model, the five high-level dynamics identified in the previous section would exert continuous and compounding pressure towards power concentration throughout the IE, leading to progressive democratic backsliding up until PS has achieved a DSA.
- I refer to this as a “backslide all the way” threat model.
Here's one very high-level illustration of how this might happen:[5]
- Early in the IE, it becomes increasingly clear to a POTUS PS and the public that the frontier AI industry will become the US's single most important economic and military asset.
- China's leaders become increasingly conscious of this, too, and tensions begin to rise in the Asia-Pacific as they realise that several of their close neighbours are making a direct contribution to Chinese disempowerment.
- In response, PS starts “soft nationalising” the frontier AI industry to guard against threats of Chinese distillation and other IP theft. In particular, she starts:
- gradually extending the duration of a "voluntary" national security screening process;
- using DPA allocations authorities to slowly starve most labs of compute, and concentrate compute within her preferred lab;
- forcing labs to conduct ever-greater shares of their training at SL-5 facilities operated by the federal government;
- eventually – classifying the "helpful-only" frontier models generated by the preferred lab, and restricting access to high-ranking officials in the national security apparatus.
- With the stated goal of placing the US on a war footing, PS starts packing the bureaucracy, expanding the executive's surveillance activities, and increasingly automating the military and security services.
- After a major crisis (e.g. a bioterrorism warning shot or the invasion of Taiwan), her allies in Congress pass a bill fully nationalising the AI industry, with genuine public support.
- Over a period of several years, PS inserts ever-less-subtle political biases into the models that the nationalised industry serves to the public, businesses, state governments, courts, journalists and Congress. Alternative models are far less capable, so it becomes increasingly hard to hold her accountable.
- She has also fostered a great deal of public support after instituting a UBI programme which has made the median voter exceptionally wealthy – so her increasingly firm grip over independent US institutions receives limited pushback.
- By the end of her second term, PS decides she doesn't want to give up power, so she gets an AI henchman to ratchet up the bias in the leading model to the point where they will simply refuse to assist anyone who tries to remove her from office.
- Now that her AI henchmen are diffused throughout the whole of the economy, government, and military, she can also unilaterally seize control of nearly any asset she wants and overcome any legal, political, or violent resistance.
- As a result, she and her allies have irrevocable and totalitarian control over the entire United States.
One argument in favour of backslide all the way threat models which I find especially compelling is that most of the individual steps don’t require PS to be actively trying to achieve EPC.
- e.g. in the scenario above, up until PS inserts a loyalty into the leading models, she could just be following local incentives to increase her power and diminish that of her rivals, without realising (or admitting to herself) that she is on the path to EPC
This seems more congruent with the psychological profiles of contemporary political and lab leaders than the "shortcuts" to EPC which I set out below.
That said, I still think backsliding all the way is less likely than other EPC threat models. That’s because:
- I suspect PS will become increasingly strategic throughout the IE, as she gains access to increasingly high-quality AI advice and becomes increasingly aware of the opportunity to lock in her preferred social order; and because
- I suspect a more strategic PS will recognise that gradual strategies are simply less efficient than backsliding up to a threshold and taking a shortcut.
- i.e. why would she bother to gradually capture the whole of USG and various IPHs, when she could get to EPC far faster by packing the military alone?
I think shortcuts can be sorted into two broad categories:
- government capture shortcuts; and
- lab capture shortcuts.
Under a government capture shortcut, PS aims to:
- use AI to pack essential parts of the executive; and then
- exploit executive overhang within the packed executive to gain control of other power-concentrating affordances (e.g. frontier AI).
One particularly plausible shortcut is the AI-enabled military coup – whereunder PS:
- packs the military; and then
- uses it to take control of other key affordances by force.
- e.g. using a robot army to seize ample compute and the seat of government
Another particularly plausible shortcut is “packing the regulators”[6] – whereunder PS:
- packs any agencies with important powers to regulate the AI industry;
- e.g. parts of DOC; any regulator set up by incoming AI legislation
- abuses those powers to gain privileged access to frontier AI capabilities.
- e.g. demanding unmonitored access to an AI henchman in return for shelving an investigation into unsafe practices
- e.g. threatening to flip a "kill switch" on any frontier lab that serves its best model to her political rivals
Two other parts of the executive also seem particularly worth packing – the intelligence community (“IC”) and the law enforcement apparatus (esp. key parts of the DOJ). That’s because:
- packing the IC would enable PS to:
- drastically expand her surveillance capacity with a reduced risk of whistleblowing; and
- carry out a wide variety of unlawful activities under a blanket of classification;
- packing law enforcement would enable PS and her allies to engage in lawbreaking whilst knowing that federal law couldn't easily be enforced against them.
- e.g. conducting extrajudicial killings of lab leaders, covering up their involvement by illegally deleting records, declining to investigate at the federal level, and then refusing to comply with congressional subpoenas on the matter
Government capture shortcuts seem particularly easy for a POTUS PS, because she has direct influence over senior appointments within the executive branch.
- However, I also find it somewhat plausible that a lab leader PS could insert a loyalty into the model used by the military, IC, law enforcement, or AI regulators and so gain control over their affordances.
Under a lab capture shortcut, PS aims to:
- gain unchecked control over frontier AI development;
- exclude others from accessing frontier capabilities; and then
- exploit those frontier capabilities to durably concentrate power.
These shortcuts rely on two distinct threat vectors:
(1) Loyalty insertion (i.e. determining the alignment target of the leading model, and then relying on the model to concentrate power on your behalf)
(2) Capabilities asymmetries (i.e. gaining exclusive access to key capabilities which can be exploited to further concentrate power). It’s hard to say in advance what these key capabilities might be – but here are three strong candidates:
- Superpersuasion[7] (i.e. PS can easily manipulate rivals into complying with her goals in a wide variety of political, legal, and military settings)
- Superstrategy (i.e. PS has an unmatched degree of strategic foresight, enabling her to execute on highly-complex power-seeking strategies and outmanoeuvre defending IPHs who lack the same capabilities)
- Supercyber (i.e. PS has an unmatched ability to hack into computer systems and turn them to her own ends, including for purposes of surveillance, insertion of secret loyalties, and general disruption)
I expect PS’s identity to greatly influence the most likely shortcut.
If PS is a lab leader, she seems most likely to rely on an enforced monopoly, whereunder:
- her lab pulls ahead of the competition, due to a natural break-away (e.g. a big and quick software intelligence explosion) and/or deliberate sabotage (e.g. abusing advanced cyber capabilities to sabotage competitors);
- around the same time, she starts packing her lab with loyalists and AI henchmen to ensure tight personal control over the training process; and
- once she has a packed lab and a frontier monopoly, she:
- inserts a secret loyalty into her frontier model and lets it diffuse throughout society until she has effectively captured various IPHs;
- e.g. the executive; the media; the courts
- or abuses her privileged access to key capabilities to capture various IPHs.
- e.g. using AI-enhanced social engineering, uplifted by a great deal of hacking-enabled surveillance, to fill their senior ranks with loyalists
- inserts a secret loyalty into her frontier model and lets it diffuse throughout society until she has effectively captured various IPHs;
If PS is a POTUS, she seems most likely to pack the frontier – abusing key legal authorities to fill the leading AI project with loyalists and AI henchmen. Centrally, I’d expect her to:
- pack the "regulators" (see above), giving her more direct control over the executive's relationship with the AI industry;
- abuse existing emergency and national security powers (e.g. the DPA) to kludge together a centralised project over which she has substantial direct influence;
- e.g. using allocations authorities under Title I of the DPA, plus a Title VII voluntary agreement, to set up a project whose board and key staff are de facto chosen by the DPA Committee
- e.g. using Title I hoarding designations and export control powers to kill off competitor labs
- e.g. classifying the very best models, giving her veto power over which human workers can participate in the project
- seek to pass new regulations increasing her ability to influence the training process;
- e.g. requiring labs to conduct a portion of their training process at SL-5 facilities owned and operated by the federal government
- e.g. embedding executive employees in the labs with wide-ranging access permissions – nominally for the purposes of safety assurance
- e.g. granting herself a unilateral "kill switch" over frontier training runs
- and, once she has a packed frontier – insert a secret loyalty into her frontier model or she abuses her privileged access to key capabilities to capture various IPHs.
I find collusion between POTUS PSs and lab leader PSs to be a particularly plausible variant of all of the threat models that I've laid out above.
That's because both sides control valuable affordances that can benefit the other, such as:
POTUS
- Favourable regulatory treatment (e.g. looking the other way on safety warning shots)
- Influence in the admin (e.g. a seat on an advisory board for the AI regulator)
Lab leaders
- Large amounts of funding (e.g. for electoral campaigns)
- Technical support (e.g. helping to develop superpersuasion capabilities, or training AI henchmen)
- Access to off-books tokens (e.g. using the lab's private compute to conduct illicit cyber operations against IPHs)
- Epistemic distortion in POTUS's favour (e.g. inserting political biases into her models)
It’s hard to say exactly how any collusion might go, but here are a few scenarios I find particularly plausible:
- A POTUS PS could give a lab leader PS an influential role in a centralised frontier project, in return for her support with packing that project.
- A POTUS PS could threaten to use “kill switch” powers to coerce a lab leader PS into inserting a joint secret loyalty into the models used throughout USG.
- A lab leader PS could help a POTUS PS entrench her control over the executive by enhancing campaign funding for her allies and biasing her models in favour of POTUS, in return for POTUS applying limited regulatory scrutiny.
I think there are two key determinants of the most likely threat models. These are:
- The character of any POTUS and her allies.
- The speed of the intelligence explosion.
I think the median POTUS PS would be substantially better placed to achieve EPC than a lab leader PS. That’s because POTUS has control of an extremely valuable set of affordances which seem uniquely easy to exploit and uniquely difficult for other actors to capture.
- e.g. the US military; the federal bureaucracy; widespread public legitimacy
By contrast, the key affordance of a lab leader is her access to frontier capabilities – and she may struggle to maintain asymmetric access to this affordance once a POTUS becomes adequately situationally aware.
Given this, I think the character of whoever happens to be POTUS during the IE (and the characters of their close allies) will very substantially affect the relative likelihood of different threat models. Concretely:
- If POTUS is dispositionally power-hungry, I think threat models which are POTUS-led and rely heavily on government capture (e.g. AI-enabled military coups) become far likelier.
- On the other hand, if POTUS is not especially power-seeking, I think threat models driven by a lab leader PS (e.g. enforced monopoly) become more likely.
Given that POTUS is so uniquely well-placed to achieve EPC, I also think that her character is the leading driver of the absolute likelihood of EPC.[8]
- Concretely, if US presidents during the first decade of the IE have no interest in power concentration whatsoever, I’d guess the absolute likelihood of EPC decreases by >75%.
Here are some rough rules of thumb I’ve been using when thinking about how the IE affects the likelihood of different threat models:
(1) Lab leader-only threat models seem particularly likely if takeoff is very fast and quite soon.
- e.g. SAR to TEDAI in <2mo, starting in mid-2027
That’s because fast and soon takeoffs seem like some of the few scenarios where a lab leader PS could achieve a very large capabilities asymmetry between herself and USG, before USG became situationally aware enough to take control of frontier development.
For similar reasons, shortcuts involving early lab capture seem particularly central to achieving EPC in fast takeoff scenarios.
(2) POTUS-led threat models seem more likely than lab leader-led threat models if takeoff is a bit slower and a bit later.
- e.g. SAR to TEDAI in ~6mo, starting in mid-2028
That’s because a POTUS PS seems likely to notice such a takeoff happening within the labs (e.g. through surveillance of lab leaders), and the slower timescales give her enough time to engage her various affordances to seize control of the frontier.
(3) Shortcuts involving government capture seem particularly central to somewhat slower takeoff EPC scenarios.
- e.g. SAR to TEDAI in ~2yrs
That’s because I expect efforts at government capture to involve various human bottlenecks, suggesting they will take a significant amount of clock time to pay off.
- e.g. for PS to replace the top ranks of the DOJ with loyalists, she needs to actually find and loyalty screen those individuals
- e.g. for PS to execute an AI-enabled military coup, she might need to meet and persuade the relevant generals to join her coalition
(4) Backsliding dynamics seem important to all but the very fastest takeoff scenarios, because they move PS further along the power concentration scale and enable various shortcut strategies.
(5) Backslide all the way threat models seem more plausible, relative to shortcut-heavy routes to EPC, if takeoff is very slow.
- e.g. >15yrs between SAR and TEDAI
That's because, in slow takeoff scenarios, I centrally expect IPHs (e.g. the coordinate branches) to have meaningful situational awareness and access to advanced frontier capabilities for extended periods of time, enabling them to anticipate and block shortcuts.
This suggests that EPC in such scenarios will not occur due to a rapid powergrab – but rather due to continuous and gradual pressure towards power concentration from the key dynamics in section three.
(6) Collusion-based strategies seem increasingly likely as takeoff slows down.
That’s because, if takeoff is fast, it seems more likely that a single situationally aware PS could succeed with a dash for power before other PSs have time to defend themselves.
- e.g. in a fast takeoff, it seems much easier for a lab leader PS to sneak a loyalty into her lab’s model, and then ask its ASI successor to carry out a PS-aligned takeover shortly afterwards
By contrast, if takeoff is slower, it seems likelier that multiple PSs become situationally aware and take steps to safeguard their interests, requiring a compromise between them.
- e.g. in a slower takeoff, a POTUS PS might ask a lab leader PS to insert a joint secret loyalty into her model, and the lab leader PS could reasonably fear being detected if she tried to insert a singular loyalty instead.
(7) EPC seems absolutely more likely as takeoff gets faster.
That’s because IPHs will have much less time to anticipate and react to PS's attempts to concentrate power, and are more likely to face truly enormous capabilities asymmetries between themselves and PS.
- e.g. PS has TEDAI whilst they have something close to Opus 6
The speed of the software-only intelligence explosion (“SIE”) seems like a particularly important component of overall takeoff speed, given that:
- AI progress could move particularly fast during this part of the IE; and
- frontier AI seems likely to first reach TEDAI during the SIE.
And takeoff speed overall seems particularly cruxy in worlds where takeoff could be slow enough for certain fixed-duration accountability loops to take effect.
- e.g. election cycles
- e.g. acting appointments periods under the Federal Vacancies Reform Act
Here’s a graphic setting out what I see as the critical pathways to EPC for a POTUS PS and lab leader PS:
Here are seven claims which underpin this graphic:
(1) I suspect a PS would try to abuse capabilities asymmetries before inserting loyalties. That's because:
- capabilities asymmetries seem likely to arise naturally and quite early, due to the potentially rapid pace of SIE and the dangers inherent in distributing advanced capabilities more widely;
- whereas PS would likely need to deliberately insert a loyalty, and may not trust her ability to do so without backlash until they have already concentrated power to a significant degree.
(2) I centrally expect PS to use loyalties to get all the way to a domestic DSA. That's because:
- loyalties enable PS to reliably and flexibly exercise power in one of the few ways that is not meaningfully bottlenecked on her own human limitations;
- i.e. PS doesn’t need to exercise continuous oversight over a model – she can just allow a PS-aligned ASI to do the hard work of taking power
- loyalties also enable PS to gain direct control over affordances that seem very hard for her to capture through other means – even with the benefit of superpersuasion and superstrategy.
- e.g. a loyalty could enable a lab leader PS to capture an automated military;
- e.g. a loyalty could enable a POTUS PS to capture Congress and the courts.
Given this, I have a sense that loyalties are (speaking loosely) more important and central than capabilities asymmetries for PS achieving EPC.
(3) Packing the regulators and the military seem like the most probable government capture shortcuts. That’s because:
- packing the regulators seems like one of the quickest ways for a POTUS PS to exercise meaningful influence over frontier AI development prior to nationalisation, and this seems especially valuable for concentrating power;
- packing the military allows PS to capture an affordance which most IPHs are very poorly-equipped to defend against, given USG’s near-monopoly on violence.
(4) POTUS-led threat models seem meaningfully more likely than lab leader threat models, given POTUS’s privileged control over key affordances (see above).
(5) That said, I think the most plausible EPC scenarios involve a meaningful amount of collusion between lab leaders and POTUS. That’s because:
- it seems quite a bit easier for a POTUS PS to pack the executive if she has a lab leader PS ally willing to supply her with AI henchmen;
- it also seems quite a bit easier for a POTUS PS to pack the frontier if she has a lab leader PS ally willing to help run the leading project;
- and it also seems far easier for a lab leader PS to evade nationalisation for long enough to get a DSA over USG if she has a POTUS PS ally who is willing to turn a blind eye.
(6) And both POTUS and lab leader PSs seem almost certain to use both government capture and lab capture shortcuts on the way to EPC. That's because:
- both institutions control valuable affordances that PS can use to concentrate power;
- e.g. a lab leader PS would hugely benefit from capturing the US military
- also – until captured – these valuable affordances can be used by IPHs to resist PS.
- e.g. a democracy-supporting frontier lab could use supercyber capabilities to disable a POTUS PS’s robot army
That said, a POTUS PS seems particularly likely to try out a government capture shortcut first, and then abuse the affordances of captured government agencies to pull off a lab capture shortcut.
And a lab leader PS seems particularly likely to try out a lab capture shortcut, and then abuse the affordances of the captured lab to capture USG.
So, I centrally imagine that:
- a POTUS PS would prioritise packing key parts of the federal executive (e.g. the military) before turning her full attention to capturing frontier AI development; and
- a lab leader PS would prioritise achieving an enforced monopoly before turning her attention to capturing key parts of the federal executive.
(7) To get concrete – the three EPC threat models I find most plausible are:
- A POTUS PS packs the military with lab-supplied AI henchmen; does an AI-enabled military coup; seizes control of the frontier AI industry by force; and then inserts a loyalty into the leading model.
- A POTUS PS packs the regulators and law enforcement apparatus with lab-supplied AI henchmen; abuses various emergency powers and new frontier AI legislation to pack the frontier; and then inserts a loyalty into the leading model.
- A lab leader PS breaks away from her competitors; deploys asymmetric capabilities (and enormous monopoly rents) to sabotage them, conceal AI progress, and deter USG scrutiny; inserts a loyalty into her best model; and then gets it to take over the federal executive.
Of these, I think the AI-enabled military coup scenario is the most plausible, and the lab leader takeover is the least plausible.
4.3.3.1. But will it go exactly like this?I feel fairly confident that the dynamics I have identified in section three are the key high-level drivers of EPC risk.
If we are in an EPC world, I also expect at least one of the shortcuts I have identified in section four to play a central causal role.
However, I don't feel confident in:
- which shortcuts are most causally important in expectation;
- how far we might need to backslide before passing thresholds for each shortcut; and
- which exact steps different PSs and IPHs are likely to take, in which order – because there are so many distinct actors and institutions in play.
In this section, I set out my high-level thoughts on the importance, tractability, and neglectedness of EPC, and some different “theories of victory” for work in this area.
I then set out some interventions I’m relatively excited about for reducing EPC risk.
5.1. Importance, neglectedness, tractabilityI think EPC is a top-two AI risk:
- Concretely, I think it is within an OOM as likely as misaligned takeover, and would be roughly as bad if it happened.
- Conditional on us solving alignment, I think it will be the very biggest risk.
I also think EPC is one of the most neglected AI risks:
- I estimate there are fewer than 25 AGI-pilled folks working on EPC full time – which seems way too small for the scale of the problem!
- Of course, there are many "AI x Democracy" advocates – but only a few of these folks really have their eyes on the ball with regards to transformative AI. Given this, I strongly expect such folks to miss many of the highest-value anti-EPC interventions.
However, I think EPC is quite a bit less tractable than other AI risks (e.g. bio):
- That's because almost every anti-EPC intervention either:
- has significant backfire risk – because it runs the risk of polarising the topic, or alerting bad actors to opportunities for EPC; or
- seems very difficult to implement – because it involves asking people to voluntarily hand over their power.
I think low tractability and sign-uncertainty are marks against almost all of the interventions in this section. Readers should engage with the list with this caveat in mind.
5.2. Theories of victory – how do we prevent EPC?Here are three plausible ways I think we might be able to get through the IE without EPC:
(1) The best-placed actors don’t realise the opportunity until it’s too late.
- e.g. there is an intelligence explosion at a frontier lab with a strong commitment to democracy, and by the time a POTUS PS becomes situationally aware the lab has used its advanced capabilities to outmanoeuvre her politically, blocking a coup
(2) The best-placed actors realise the opportunity, but just don’t try to achieve EPC.
- e.g. all the POTUSes throughout the IE have deeply internalised democratic values
(3) The best-placed actors try to achieve EPC but are blocked by IPHs.
- e.g. the military spots and blocks all attempts to insert secret loyalties
It’s pretty unclear to me which of these theories are correct. Given this, and given that most plausible EPC interventions don’t seem especially promising, I suspect we should pursue a portfolio approach to tackling this risk.
That is to say, I think we should focus our efforts on any interventions that seem particularly likely to move us towards any of these theories of victory with minimal downsides for the other theories.
- e.g. for electoral interventions, we should feel especially good about an intervention which increases the likelihood that a virtuous candidate wins the 2028 presidential race (contributing to a type (2) victory) without increasing the salience of EPC risks amongst presidential candidates (which could reduce the odds of a type (1) victory).
Below, I’ve set out some interventions I’m excited about, keyed to the high-level dynamics in section three. I've marked interventions which seem particularly promising with a "[HIGH PRIORITY]" tag.
I’ve also included a list of cross-cutting interventions which influence several dynamics all at once. These primarily relate to field-building, reflecting my view that EPC risk is highly neglected right now.
Intervention
Explanation
Solving the Red and Expert problem
[HIGH-PRIORITY]
Hard-to-remove behavioural guardrails
Make sure most AI used in frontier labs and the executive comes with a minimal set of guardrails (e.g. law-following AI).
These should be enabled by behavioural evals, and coupled with governance processes that make them hard to strip out.
Improving incentives for defection
Let insiders take Top Secret info straight to Congress, bypassing the (easy-to-pack) Inspectors General.
Widen Espionage Act protections for whistleblowers.
Ensure existing whistleblower protection orgs are very well-funded.
Let IPHs hold tamper-resistant backups of frontier model weights
This allows IPHs to check older models for secret loyalties as capabilities advance, and makes it likelier they have access to nearly-as-good older models if they discover a loyalty.
Remove single points of failure in the executive
Require multi-person sign-off for high-stakes AI use cases, and require the executive to procure and use models from multiple labs.
Eliminating executive overhang
[HIGH-PRIORITY]
Red-teaming AI legislation for EPC risk
Many popular AI bills hand the executive easy-to-abuse powers (e.g. kill switches).
Someone should proactively red-team them and push for more robust alternatives.
Glasswing for the law
Fund a coordinated push to uncover the legal loopholes a PS could use to concentrate power and close them through legislation or impact litigation.
[HIGH-PRIORITY]
Improving record-keeping and transparency
At a minimum, agent trajectories should be treated as federal records.
Congress should also impose extensive transparency conditions on the funding of any USG-led AGI project.
And USG should move towards an automated oversight regime as quickly as possible.
Ban domestic killer robots
We should explore proposals making it harder for the US military and law enforcement to deploy LAWS on US soil
The asymmetric frontier
Pacing the frontier well
Slower takeoff means reduced capabilities asymmetries and more time for IPHs to react to powergrabs.
[HIGH-PRIORITY]
Better Out Than In laws
Frontier labs and the executive should be prohibited from conducting internal-only deployments, save for the purposes of safety and security research.
Turbocharging IPHs with AI
Congress, courts and the states should get bigger token budgets, and the same models as the executive on the same timelines.
Desperate times calling for desperate measures
Preserve household economic security
Take steps to cushion the economic shocks which the IE could create for ordinary people through policies like "citizens' shares" in the AI industry.
[HIGH-PRIORITY]
Virtue screening the powerful
Screen candidates for important positions (e.g. state governorships) for power-seeking, dishonesty and links to other PS, then steer campaign money to lower-risk candidates.
Widespread epistemic degradation
Epistemic tooling
Accelerate the arrival of tools like ambient superforecasting and lie detection, and place them in the hands of IPHs.
Disclaimers for synthetic political content
Require annoying, medical ad-style disclaimers on AI-generated political content, backed up by legal penalties.
Cross-cutting interventions
Write up better intro materials for the AI safety pipeline
Write up materials setting out the basic threat models and most promising interventions, to help sympathetic people get up to speed faster.
Pitch people to do more on EPC
Pitch sympathetic IPHs and influential folks in the AI safety community to work more on preventing extreme power concentration.
Terminator for EPC
Help kickstart a feature film or television show about EPC occurring in the US.
Federalist Papers 2.0
Set up a newsletter about EPC that takes anonymous submissions from lab staff, USG officials and cautious think-tankers.
AIFP for EPC
Write a detailed AI 2027-style EPC scenario, built to go viral with elites.
Follow this 3-6mo later with policy recommendations and a Plan A-style positive vision for US democracy.
[HIGH-PRIORITY]
Set up the EPC org
Set up a dedicated EPC org, which both conducts its own research and takes the lead on EPC field-building.
[HIGH-PRIORITY]
Detailed threat modelling by sector experts
Get sector experts to go deep on key parts of my threat modelling (e.g. how a POTUS PS gets control of a robot army) to help develop more targeted interventions.
5.3.1. Solving the Red and Expert problem5.3.1.1. Hard-to-remove behavioural guardrailsI'm particularly concerned about the risk that a PS gains unfettered access to AI henchmen.
Given this, I’m particularly excited about finding ways to ensure that most AI deployments in frontier labs and the executive are subject to a minimal set of guardrails which are hard to remove.
- e.g. guardrails to ensure that the models are "law-following AIs" (“LFAI”)
“Hard to remove” could just mean that the training process itself is conducted in a way that makes the guardrails difficult to train out of the model.[9] But a more reliable approach would be to apply enhanced governance processes to the development of model specs, weights access, and alignment testing.
- e.g. labs could implement various mitigations to guard against secret loyalties
- e.g. lab boards could mandate board-level sign-off for any changes to model specs
- e.g. the military could require sign-off from officers in multiple branches before any one person can access model weights held on government systems
- e.g. Congress could vet models before they are deployed anywhere in the executive
I think it will ultimately be necessary to legislate for these guardrails (e.g. passing a bill mandating that frontier AIs are law-following) rather than relying on industry consensus.
- That's because, otherwise, it seems too easy for a POTUS PS to pressure the labs to remove the guardrails for classified models.
However, there is clearly a place for non-legislative preparatory work within the labs and the AI safety community.
- e.g. research to identify the appropriate degree of deference that LFAIs should exercise towards internal counsel
- e.g. developing evals to ensure that models are compliant with any guardrails in their model specs
Whistleblowers currently face very high barriers to sharing classified information about dangerous behaviour within the executive. In particular:
- Whistleblowers can't legally share Top Secret information with Congress without first alerting the Inspectors General ("IGs") – and a POTUS PS seeking to pack the executive can quite easily replace the IGs with loyalists.
- Whistleblowers can only disclose classified information to people already read-in to the project – which does not include the majority of Congress or the public.
- Failure to comply with these requirements can lead to criminal prosecution under the Espionage Act.
When I spoke to experts about this, they recommended the following reforms to the Act:
- All members of the House and Senate intelligence committees should be deemed "authorised recipients" – enabling whistleblowers to directly disclose Top Secret information to them.
- Whistleblowers should be protected by a public interest defense – enabling them to argue that an unauthorised disclosure was justified by the need to prevent serious violations of the law or major threats to public health and safety.
- Alternatively, the court should be unable to convict a whistleblower unless the prosecution can show that they had "intent" to commit wrongdoing.[10]
It also seems wise for EPC funders ensure existing government whistleblower orgs are exceptionally well-funded.
5.3.1.3. Let IPHs hold tamper-resistant backups of frontier modelsFrontier labs seeking to prevent EPC could store tamper-resistant backups of key model checkpoints on clusters controlled by various IPHs.- e.g. Congress; state governments; the other Five Eyes nations
This would enable IPHs to test old models with new and improved evaluation technologies to check if they were secretly loyal. Also, if a PS inserted a loyalty into the leading model and this was detected quickly, IPHs would still have access to an alternative near-frontier model.
5.3.1.4. Remove single points of failure in the executiveSenior decision-makers in the executive should be encouraged to avoid creating single points of failure ("SPOFs") through incautious AI adoption. In particular:
- The use of AI systems in high-stakes scenarios (e.g. domestic deployments of LAWS) should require sign-off by multiple separate humans with distinct reporting chains.
- Key parts of the executive (e.g. DOJ litigators) and both of the coordinate branches should be encouraged to procure and use models from multiple frontier developers across their critical functions, to reduce reliance on any one model.
- e.g. a department might institute a “two AIs rule” – where any synchronous monitoring of AI agents must be provided by a model from a different lab to the agents themselves
- Decisions to use various powers influencing frontier AI development (e.g. flipping a "kill switch") should also require sign-off by multiple parties.
Where practical and politically feasible, measures to avoid SPOFs should be enshrined in Acts of Congress.
Otherwise, a POTUS PS might be able to pack the relevant departments, and then change the underlying procurement or decision-making rules to eliminate the measure.
However, even if they cannot be easily written into statute, these measures seem quite helpful for preventing the capture of key parts of the executive by a non-POTUS PS.
- e.g. preventing a rogue-general PS from carrying out an AI-enabled military coup
- e.g. preventing a lab leader PS from capturing an entire department just by inserting a secret loyalty
A particularly ambitious goal for removing SPOFs would involve lobbying for an Act of Congress to reform the operational chain of command in the US military.
- e.g. ensuring that combatant commanders and law-following AIs can refuse certain power-concentrating orders from a POTUS PS
This is very far outside of the Overton Window – but it’s worth noting that Congress has reformed the chain of command multiple times since the Second World War, so it doesn’t seem wholly implausible.
- e.g. Eisenhower’s Department of Defense Reorganization Act 1958
- e.g. Goldwater–Nichols in 1986.
I should note that Stefan Torges has written in some detail about the importance of removing SPOFs in the military. I strongly recommend interested readers check out his piece.
5.3.2. Eliminating executive overhang5.3.2.1. Red-teaming AI legislation for EPC risk and proposing low-risk alternativesMany popular proposals for AI regulation involve greatly expanding the discretionary powers which the executive has over frontier development- e.g. the Lieu & Moran Kill Switch bill would have enabled the executive to shut down deployments of models which pursue “a goal that is not a goal intended by the developer" or “conceal a capability, intention, or action [from]... monitoring".
- e.g. the FRONTIER bill would enable the executive to shut down training for ~1.5mo before any prospect of a court challenge to the merits.
I think a POTUS PS could fairly easily abuse powers like this to coerce labs into supporting her power-seeking schemes.
- e.g. threatening to flip a kill switch unless a frontier developer provides her with access to an AI henchman
- e.g. repeatedly shutting down training at a disfavoured lab during the SIE to help an allied lab break out in front
Given this, I think someone in the AI safety community should be scrutinising proposed AI legislation to make sure it isn't too power-concentrating, and advocating for alternative approaches which strike a better balance between EPC and other risks.
They could give regular private input on proposed legislative text to 501(c)(4)s in the safety community (e.g. SAIP) and congressional staffers.
They could also try to establish a public profile on X as the EPC red-teamer – posting timely criticisms of different legislative proposals (e.g. the leaked Anthropic bill) as and when they become public.
And they could publish a list of principles for writing legislation that doesn't unduly concentrate power. This might include:
- Placing powers in the hands of self-regulatory bodies (e.g. FINRA-for-AI) or state-level regulators (e.g. the California state government).
- Requiring a court order to exercise particularly high-stakes powers.
Given this, I think legal experts in the AI safety community should conduct an ambitious effort to identify the key legal ~loopholes which could facilitate a POTUS-led powergrab, and determine the most effective routes to remedy them.
- e.g. funding conservative legal scholarship centred on constraining the executive
- e.g. lobbying for conditions on funding in appropriations bills
- e.g. ambitious public outreach efforts to drive constitutional amendments
Here are some powers which seem particularly useful to restrict if at all possible:
- executive privilege;
- the presidential pardon and presidential criminal immunity;
- presidential control over security clearances and classification; and
- presidential hiring and firing powers for IGs and independent agency heads.
Legal experts I have spoken to have suggested that targeted efforts in the national security domain might have a particularly large effect on total risk.
- e.g. tackling the abuse of the Export Control Reform Act (“ECRA”)
- e.g. increasing the procedural requirements on the exercise of various DPA powers
Reforming the chain of command (see above) and enabling Congress to more easily punish contempt (see below) might also fall within scope of such a project.
5.3.2.3. Improving record-keeping and transparencyI expect it would be easier to prevent a PS from abusing her power if IPHs could more easily scrutinise what she was up to.
- Below, I've set out four promising avenues for facilitating this kind of transparency.
- However, it's worth noting that this is a broad and complex topic which I'm not especially familiar with, so I encourage people to actively scrutinise what I've written below. Each of my suggestions would benefit from substantial additional research.
(1) Federal record-keeping rules could be expanded to cover agent trajectories.
The Archivist of the United States is responsible for issuing guidance around what counts as a record under the Federal Records Act ("FRA").
FRA guidance doesn’t currently tell agencies to keep records of agent trajectories (i.e. what systems an agent interacted with; which edits it made to which files).
So, in the first instance, the AI safety community should lobby the Archivist to issue guidance that the FRA covers agent trajectories.[11] However:
- the Archivist is quite easy for a POTUS PS to fire and replace with a loyalist;
- cf. early 2025, when the Archivist was fired and the Secretary of State took over in an acting capacity
- and the duty to create records under the FRA sits with agency heads, whilst enforcement goes through the Attorney General – all of whom are similarly easy to replace;
- so I'm unsure how robust these efforts would be to a packed executive.
(2) We could encourage Congress to make the most of its oversight powers, and seek to expand them through legislation.
- e.g. we could lobby congressional committees to pursue impact litigation around the scope of executive privilege
- e.g. we could lobby Congress to pass a bill requiring per diem civil fines against officers who are found in contempt of Congress and have yet to remedy the issue
I gather there are already considerable efforts in this area from folks in the community. I'm happy to put people in touch with the folks running these projects in case of interest.
(3) Congress could institute an automated oversight regime for federal records.
This regime could be designed in accordance with the principles of structured transparency. Here's an illustration of what I have in mind:
- Congress-procured AI agents could be granted default access to all federal records.
- The agents would automatically flag concerning records for review.
- Congressional overseers wouldn't get direct access to the records, but they could ask their agents to query them and receive bounded answers.
- e.g. “did any collection target an American without a warrant?” → yes / no / a count
- Where the law was ambiguous, the request could also be flagged to an executive branch lawyer for review.
- Substantial additional safeguards could be layered onto classified records.
- e.g. only a smaller set of congresspeople could query these records, and the agents would have to pass a far higher threshold of safety and security
This could be piloted on a smaller scale within the Government Accountability Office (“GAO”) before being extended across all congressional offices and committees.
Once the system was reliable enough, it could also be extended to Freedom of Information Act ("FOIA") requests, helping the public directly scrutinise the executive.
It's worth noting that this project currently seems far outside of the Overton Window. Experts I've spoken to tell me this would:
- be a major technical undertaking;
- create a variety of hard-to-remedy information security risks; and
- face tremendous pushback from government bureaucrats who (reasonably) believe that too much scrutiny can make it harder to openly debate difficult policy trade-offs.
(4) Frontier AI projects could be subject to extensive transparency requirements, even if those projects weren't technically government bodies.
- e.g. federal record-keeping requirements could be expressly extended to any public–private partnership ("PPP") AGI project
- e.g. frontier labs could be required to participate in the automated congressional oversight regime which I've set out above
Extensive transparency seems particularly important in the context of a USG-led AGI project, given the likelihood that such a project occurs under a veil of classification.
Given that we’re not sure how exactly any such project might be structured, it could be helpful to set out specific triggers which cause heavier transparency requirements to come into effect.
- e.g. USG taking an equity stake in a lab
- e.g. the classification of a frontier model's weights
To give these requirements teeth, they could be included in appropriations bills as conditions on funding the project, with funding issued periodically and automatically withheld (or withdrawn) if the project fails to comply.
5.3.2.4. Ban domestic killer robots in the USThe AI safety community should explore proposals making it harder for the US military and law enforcement to deploy lethal autonomous weapons on US soil, to increase barriers to an AI-enabled coup.
- e.g. military robots could be geofenced, with their weaponry only becoming usable within the US after sign-off by a majority in both houses of Congress
I haven’t spent much time thinking about this idea, so I’m particularly uncertain how technically and politically feasible it might be.
5.3.3. The asymmetric frontier5.3.3.1. Pacing the frontier wellAs I note above, EPC risks seem greatest in fast takeoff worlds, because this could lead to large disparities between PS and IPHs in their access to frontier capabilities.
Given this, pacing the frontier seems like a particularly good way to reduce EPC risks – provided that any legislation which enables pacing doesn't inadvertently centralise power in the executive.
5.3.3.2. Better Out Than In lawsAnother promising approach to reducing frontier asymmetries is what I'm calling "Better Out Than In" laws – which seek to restrict what a frontier lab or the executive can do with an AI model before it has to be made more widely available. For example:
- Labs could be barred from internal-only deployments of their models – save for the purposes of safety testing and cybersecurity work.
- Once models meet a preliminary safety and security threshold, labs could then be required to make their models available to all three branches of USG and all state governments.
- And once models meet a higher threshold, they could be required to make them available to any organisations found by a federal court to meet relevant safety requirements – and then the rest of society.
- The executive could be similarly restricted to safety and security testing during any national security screening period.
- Access to classified models could still be granted to judges, elected politicians, state government officials, congressional staffers, and federal bureaucrats who have the relevant clearances.
These laws might also have an indirect benefit of slowing capabilities progress at the frontier, because labs would have to dedicate so much effort to safety testing before being permitted to train a new model.
5.3.3.3. Turbocharging IPHs with AIBoth Congress and the judiciary have considerable powers to constrain the executive which they seem unlikely to fully exercise during the IE.
- e.g. a human-led judiciary may struggle to consider the vast quantity of legal disputes generated by the authoritarian behaviour of an AI-enabled executive
- e.g. a human-led Congress may struggle to identify all the ways that a POTUS-supported legislative proposal concentrates power and, in a crisis, may struggle to coordinate around executive-constraining amendments to such legislation
Here are some ways it might be possible to remedy this issue:
- The AI safety community could lobby Congress to radically increase its (and the judiciary’s) IT budgets, and to earmark this for token spend.
- We could massively increase funding for Horizon / TechCongress, and encourage them to embed well-paid forward-deployed engineers in key coordinate branch bodies.
- e.g. the House and Senate intelligence committees; the DC District Court; SCOTUS
- We could fund projects to accelerate the arrival of defense-favoured coordination tech (e.g. negotiation facilitation) and provide this to the coordinate branches at a significant discount.
- Congress could pass a Better Out Than In law (see above), providing that any model made available to any part of the executive for any purpose must also be made available to itself and the judiciary at the same cost per token.
I suspect similar AI uplift work should also be done in key state and local governments (e.g. California) to ensure that they can continue to exert an effective check on the frontier AI industry throughout the IE.
5.3.4. Desperate times calling for desperate measures:I haven’t spent much time thinking about how to intervene on this dynamic, so my views are quite underdeveloped. Here are a few lower-confidence ideas I’ve come up with.
5.3.4.1. Preserve household economic securityOnce the IE has begun, USG could undertake a variety of radical economic reforms to protect US citizens from economic disruption.
- e.g. instituting a UBI programme
- e.g. imposing a moratorium on redundancies and pay cuts
- e.g. transferring voting shares in key parts of the frontier AI industry to all citizens
- e.g. allocating a minimum percentage share of all frontier AI tokens to inference by private citizens, enforceable by class action
- e.g. imposing an interest rate ceiling on the largest sources of variable-rate personal debt (e.g. credit cards).
If executed effectively, I suspect this could meaningfully increase perceptions of personal economic security throughout the IE.
I expect quite a bit of work has already been done on the most legally and economically robust ways to deliver protections like this. I suspect the AI safety community should continue to fund such work with an eye to developing proposals that would deliver on these objectives without inadvertently concentrating power.
- e.g. ensuring citizens have a right to frontier tokens directly enforceable against the labs, rather than having to rely on an executive-run UBI process
A 501(c)(4) could build an AI "virtue screening" tool which would conduct a deep-dive on candidates for key roles in federal, state, and local governments.
- e.g. state judges and governors
- e.g. state and federal legislators
- e.g. presidential candidates
The tool would continuously scan publicly-available sources for evidence of power-seeking traits:
- e.g. power-seeking statements or actions;
- e.g. dishonesty and corruption;
- e.g. close associations with other power-seekers.
The outputs of this tool could then inform political spending by big donors in the community.[12] This could increase the likelihood that a POTUS PS and her political allies are simply not on the ballot to be selected by concerned voters during desperate times.
The same tool could also be used to conduct a smaller investigation into the leadership of key parts of the AI industry (e.g. frontier labs; hyperscalers; chipmakers) to help inform decisions by investors in the community.
5.3.5. Widespread epistemic degradation5.3.5.1. Epistemic toolingI think the best way to reduce risks from epistemic degradation is to ensure that IPHs and the general public retain the capacity to verify what is true and false throughout the IE.I think one particularly promising way to achieve this is to found projects that accelerate the arrival of various epistemic tools that are likely to arrive during the IE, and ensure that they are widely distributed as quickly as possible.
Here are some tools which I think could be particularly effective:
- ambient superforecasting;
- automated open-source intelligence;
- reliability-tracking and “Community Notes for Everything” – especially as a service provided to judges, congresspeople, and journalists to scrutinise the executive;
- “Pangram for Everything” – especially if introduced by social media platforms to flag by default any AI-generated content served to users; and
- open-source lie detection tech – distributed as quickly as possible to the public (rather than being monopolised by those in power).
I should note that Lizka Vaintrob and Owen Cotton-Barratt have already written about this topic at length.
5.3.5.2. Disclaimers for synthetic political contentCongress (and swing state governments) could pass laws requiring annoying, medical advertisement-style disclosures for any AI-generated content broadcast or posted on social media by a corporation in relation to a public figure, with criminal penalties for non-compliance.- e.g. campaign ads containing AI-generated video of political rivals would need to state at the end of the advertisement that this part of the ad was AI-generated, or the producers would face a criminal fine
Disclaimers of this sort would hopefully make it easier for voters and IPHs to effectively scrutinise their leaders.
- e.g. it would be riskier for an unscrupulous PS to fabricate a scandal about her opponent in a presidential race
As noted above, most of the interventions in this section aim to build the field of people working to prevent extreme power concentration. I think field-building interventions are particularly promising because EPC risks are currently so neglected.
I suspect we should prioritise field-building amongst the following groups, in decreasing order of priority:
- AI safety community (esp. in DC)
- Sympathetic NatSec professionals and federal bureaucrats
- Constitutional / administrative lawyers
- Centrist politicians (esp. in Congress)
- The general public
Most of the measures below are intended to reach one or more of these priority groups.
5.3.6.1. Write up better intro materials for the AI safety pipelineThe bar for getting up to speed on EPC is currently very high. To get a sense of the most plausible threat models and most promising interventions, you need access to a bunch of private documents and a high-context interlocutor who is willing to give you a significant amount of their time.
I believe this is a major barrier to people getting involved in the field. Given this, I expect it would be worth someone’s time to write up high-quality intro materials for different audiences (e.g. seasonal fellows; BlueDot classes; think tank leads), setting out the basic threat models and most promising interventions.
5.3.6.2. Pitch people to do more on EPCI think it would make sense for one of the people currently working on EPC to dedicate a majority of their time to pitching leaders in the broader AI safety community on doing more work on EPC. This might look like:
- organising lots of calls with leaders at influential AI safety organisations; and
- presenting them with the basic threat models, arguments for why they are particularly plausible, and a clear menu of actions to take:
- e.g. doing expert threat modelling
- e.g. setting up an EPC workstream
- e.g. recruiting seasonal fellows for EPC projects
- e.g. publishing articles on EPC topics
- e.g. developing our highest priority interventions
- e.g. lobbying congresspeople to adopt our interventions
I also suspect it would be worth engaging in targeted, high-effort “wake-up” efforts for the most important IPHs outside the AI safety community – including:
- eminent constitutional and administrative lawyers.
- e.g. a major AI safety funder could support conservative legal scholars to do research centred on constraining the executive in the AGI era (see above).
- centrist and centre-right politicians in Congress and key state governments;
- e.g. AI safety lobbying orgs could prepare primers on EPC for the House and Senate intelligence committees, coupled with a few particularly promising anti-EPC interventions Congress could implement
- sympathetic senior officials in key parts of USG;
- e.g. the DOJ and DOW
- e.g. up until the first draft of the screenplay is written
The goal here would be to develop compelling audiovisual fiction which becomes a cultural touchpoint in relation to EPC, increasing IPHs' situational awareness and enabling them to recognise and push back against power-seeking sooner.
5.3.6.4. Federalist Papers 2.0Someone could set up a newsletter which publishes anonymous articles about EPC, written by people who would face substantial risks from open publication.
- e.g. lab staff
- e.g. government employees
- e.g. researchers at risk-averse think tanks
- e.g. citizens of autocratic regimes
This could hearken back to the original Federalist Papers – which were published pseudonymously by several Founding Fathers at a time of great change in US history.
5.3.6.5. AIFP for EPCSomeone could set up an organisation to write a plausible worst-case scenario for EPC occurring in the US by the end of the decade, similar in form, substance and writing style to AI 2027.
- They could try hard to make the piece go viral – aiming for wide readership across senior staff at AI labs, leaders at key civil society orgs, and high-ranking politicians.
- And then they could follow up within 3-6 months with detailed policy recommendations for safeguarding US institutions, and a Plan A-style positive vision for how things could go if these recommendations were adopted.
This work would aim to have an impact in roughly the same way AI 2027 did for loss of control – massively raising the salience of EPC with elites, giving the cause a public face, and creating a Schelling point of policy recommendations to rally around.
5.3.6.6. Set up the EPC orgSomeone could set up an org whose role is to act as a home for research on EPC and a hub to connect people in the field.
It could produce its own research on extreme power concentration, as well as doing more rapid response policy work.
- e.g. AI 2027 and Plan A for EPC
- e.g. EPC red-teaming of draft AI safety regulations
It could also lead outreach to the AI safety community and IPHs, aiming to alert them to the risks of EPC and help them resist it.
- e.g. running EPC-themed TTXs
- e.g. running EPC-themed conferences and retreats
- e.g. coordinating with lobbyists to increase uptake of promising interventions
And it could maintain other useful community infrastructure.
- e.g. the Federalist Papers 2.0
- e.g. operating a fellowships programme to bring junior researchers and entrepreneurs into the field
Many EPC threat models (including the ones above) are sorely lacking in detail. This is a problem, because:
- it makes the threat models unconvincing to IPHs (e.g. high-ranking military officers), who might then fail to take adequate measures to protect against PS; and
- it also makes it harder to develop well-targeted interventions.
Given this, I think the field would greatly benefit from in-depth, expert threat modelling of the most important elements of the most important EPC threat models.
- e.g. how exactly a POTUS PS could gain unified control over a robot army without massive pushback from her generals
- e.g. through which legal mechanisms a POTUS PS could plausibly “soft-nationalise” the frontier labs
Glasswing for the law (see above) is a particularly fleshed out example of what I have in mind here. But I suspect this would actually be most helpful in the military domain, given that our threat models seem both particularly plausible and especially underdeveloped.
5.3.7. Which of these interventions seem most promising?I think the following interventions seem reasonably tractable and particularly likely to further at least one of my three theories of victory without compromising the others.
- Hard-to-remove behavioural guardrails (esp. a legal mandate for LFAI)
- Improving record-keeping and transparency (esp. as applied to any USG-led AGI project)
- Red-teaming AI legislation for EPC risk (esp. if coupled with principles for writing AI legislation in a way that doesn't unduly concentrate power)
- Better Out Than In laws (esp. for Congress and the judiciary)
- Virtue screening the powerful (esp. for primary candidates in high-stakes races)
- Setting up the EPC org (esp. if it has a field-building focus)
- Detailed threat modelling by sector experts (esp. military threat modelling)
Here are a few points where I think what I’ve written above is particularly weak.
(1) I don’t yet have a good sense of how, precisely, a POTUS PS could gain sufficiently fine-grained control of frontier AI development to:
- create durable asymmetries in access between her allies and the rest of society; and/or
- gain consistent and reliable access to an AI henchman.
I’m a bit sceptical that the current set of emergency powers (e.g. the DPA) would be sufficient to achieve this, and I suspect that new legislation would be required. But I’m not confident about this – and I think the topic would benefit from a deep-dive.
(2) I don’t yet have a detailed sense of how exactly a PS could abuse capabilities asymmetries to concentrate power to an extreme degree.
I think this is an inherently difficult question to answer, for roughly the same reasons as it’s hard to give a detailed answer for how misaligned takeover might happen.
As in – it’s hard to know whether there’s a ceiling on these capabilities, where that ceiling might be, and what it looks like for an actor to be radically more capable along these dimensions
That said, I think my current threat modelling reads a bit like:
“PS gets superpersuasion and superstrategy and then just one-shots everyone”
And this feels unacceptably handwavey.
(3) I’ve received limited expert input on most of the interventions I propose.
Given this, I expect them to be imperfectly targeted and fail to account for important practical limitations. In particular, I suspect I’m too confident about the prospects for passing various pieces of legislation.
(4) This post focuses exclusively on domestic EPC and ignores how a single actor could get a DSA over the entire world.
This is a significant omission, because the likelihood that a post-ASI US could dominate all other actors seems really very cruxy for the overall badness of domestic EPC.
I also think this focus on domestic concerns may have caused me to underweight:
- the need for PS to capture other parts of the AI stack which sit outside of the US;
- e.g. chipmakers; makers of key machine tools
- the likelihood of various space-based routes to EPC.
- e.g. a first mover in space gains a DSA by hoarding access to space resources
- ^
To be clear – I'm unsure whether extensive expropriation and redistribution would actually be desirable.
- ^
Thanks to Cullen O'Keefe for this coinage.
- ^
Advanced AI may also be far more able to execute on complex, long-horizon legal strategies – furthering the potential for abuse.
- ^
Matt Botvinick (Anthropic) has written more about this topic in his recent book.
- ^
I also find it plausible that we could see a backslide all the way scenario wherein a lab leader PS uses her asymmetric access to frontier capabilities and vast AI-generated wealth to corrupt political processes and gain effective control of USG.
- ^
It's worth stressing that I'm using the term "regulators" in a broad and non-standard way here, to refer to any government agency with substantial discretionary authority over the frontier AI industry – whether or not it would be traditionally thought of as a regulator.
- ^
This includes both mindhack-level superpersuasion, and more subtle forms of social manipulation.
- ^
To be clear – I also think the character of lab leaders matters quite a bit, but it seems less useful to focus on this because (i) lab leadership seems less likely to change in the near-term, and (ii) I think lab leader-driven EPC accounts for <1/4 of the total risk.
- ^
For example, I’ve heard rumours that GDM struggled for several months to train a genuinely “helpful-only” model for the DOW. But it seems like this was an unusual situation – and I get the impression it will be increasingly easy to simply train guardrails out of models in future.
- ^
Apparently bills along these lines have previously been introduced to Congress.
- ^
It's worth noting that record-keeping in the White House and parts of the Executive Office of the President ("EOP") is separately governed by the Presidential Records Act ("PRA") during a president's term. White House Counsel issues similar guidance in relation to PRA compliance – and this might also need to be extended to cover agent trajectories.
- ^
Experts tell me that primary candidates benefit far more than candidates in general elections from increased funding – so it might be worth prioritising screening primaries at first.
Discuss
How do LLMs interpret FDT in a twin PD simulation?
We tested how seven LLMs apply four decision theories in a prisoner's dilemma between nearly identical copies. The models largely agreed about CDT and EDT, and all completed policy-FDT trials resulted in cooperation. But their action-FDT recommendations varied dramatically: some models almost always cooperated, while others almost always defected. We then investigated whether requested reasoning effort explained some of this disagreement.
The case of the one-shot prisoners' dilemma between psychological twins is debated in decision theory. Quoting SEP:
One controversial argument that it is rational to cooperate in a PD relies on the observation that my partner in crime is likely to think and act very much like I do... In the extreme case, my accomplice is an exact replica of me who is wired just as I am so that, of necessity, we do the same thing. It would then seem that the only two possible outcomes are where both players cooperate and where both players defect... More generally, even if my accomplice is not a perfect replica, the odds of his cooperating are greater if I cooperate and the odds of his defecting are greater if I defect... The counter argument, of course, is that my action is causally independent of my replica's. Since I can't affect what my accomplice does and since, whatever he does, my payoff is greater if I defect, I should defect.
Conventional wisdom is that causal decision theory (CDT) defects in twin prisoner's dilemma, while evidential decision theory (EDT) cooperates. Realistically, the accomplice will not be a "perfect replica"; there will at least be trivial differences between the prisoners, such as their names, or the look of their prison cell. I use the term "almost-twin prisoner's dilemma / PD" to specify a scenario with minor differences like these.
Functional decision theory (FDT) is a decision theory introduced in a 2017 paper. This paper defines FDT using quasi-causal graphs:
Just as CDT requires that mjx-container[jax="CHTML"] { line-height: 0; } mjx-container [space="1"] { margin-left: .111em; } mjx-container [space="2"] { margin-left: .167em; } mjx-container [space="3"] { margin-left: .222em; } mjx-container [space="4"] { margin-left: .278em; } mjx-container [space="5"] { margin-left: .333em; } mjx-container [rspace="1"] { margin-right: .111em; } mjx-container [rspace="2"] { margin-right: .167em; } mjx-container [rspace="3"] { margin-right: .222em; } mjx-container [rspace="4"] { margin-right: .278em; } mjx-container [rspace="5"] { margin-right: .333em; } mjx-container [size="s"] { font-size: 70.7%; } mjx-container [size="ss"] { font-size: 50%; } mjx-container [size="Tn"] { font-size: 60%; } mjx-container [size="sm"] { font-size: 85%; } mjx-container [size="lg"] { font-size: 120%; } mjx-container [size="Lg"] { font-size: 144%; } mjx-container [size="LG"] { font-size: 173%; } mjx-container [size="hg"] { font-size: 207%; } mjx-container [size="HG"] { font-size: 249%; } mjx-container [width="full"] { width: 100%; } mjx-box { display: inline-block; } mjx-block { display: block; } mjx-itable { display: inline-table; } mjx-row { display: table-row; } mjx-row > * { display: table-cell; } mjx-mtext { display: inline-block; } mjx-mstyle { display: inline-block; } mjx-merror { display: inline-block; color: red; background-color: yellow; } mjx-mphantom { visibility: hidden; } _::-webkit-full-page-media, _:future, :root mjx-container { will-change: opacity; } mjx-math { display: inline-block; text-align: left; line-height: 0; text-indent: 0; font-style: normal; font-weight: normal; font-size: 100%; font-size-adjust: none; letter-spacing: normal; border-collapse: collapse; word-wrap: normal; word-spacing: normal; white-space: nowrap; direction: ltr; padding: 1px 0; } mjx-container[jax="CHTML"][display="true"] { display: block; text-align: center; margin: 1em 0; } mjx-container[jax="CHTML"][display="true"][width="full"] { display: flex; } mjx-container[jax="CHTML"][display="true"] mjx-math { padding: 0; } mjx-container[jax="CHTML"][justify="left"] { text-align: left; } mjx-container[jax="CHTML"][justify="right"] { text-align: right; } mjx-mi { display: inline-block; text-align: left; } mjx-c { display: inline-block; } mjx-utext { display: inline-block; padding: .75em 0 .2em 0; } mjx-TeXAtom { display: inline-block; text-align: left; } mjx-mo { display: inline-block; text-align: left; } mjx-stretchy-h { display: inline-table; width: 100%; } mjx-stretchy-h > * { display: table-cell; width: 0; } mjx-stretchy-h > * > mjx-c { display: inline-block; transform: scalex(1.0000001); } mjx-stretchy-h > * > mjx-c::before { display: inline-block; width: initial; } mjx-stretchy-h > mjx-ext { /* IE */ overflow: hidden; /* others */ overflow: clip visible; width: 100%; } mjx-stretchy-h > mjx-ext > mjx-c::before { transform: scalex(500); } mjx-stretchy-h > mjx-ext > mjx-c { width: 0; } mjx-stretchy-h > mjx-beg > mjx-c { margin-right: -.1em; } mjx-stretchy-h > mjx-end > mjx-c { margin-left: -.1em; } mjx-stretchy-v { display: inline-block; } mjx-stretchy-v > * { display: block; } mjx-stretchy-v > mjx-beg { height: 0; } mjx-stretchy-v > mjx-end > mjx-c { display: block; } mjx-stretchy-v > * > mjx-c { transform: scaley(1.0000001); transform-origin: left center; overflow: hidden; } mjx-stretchy-v > mjx-ext { display: block; height: 100%; box-sizing: border-box; border: 0px solid transparent; /* IE */ overflow: hidden; /* others */ overflow: visible clip; } mjx-stretchy-v > mjx-ext > mjx-c::before { width: initial; box-sizing: border-box; } mjx-stretchy-v > mjx-ext > mjx-c { transform: scaleY(500) translateY(.075em); overflow: visible; } mjx-mark { display: inline-block; height: 0px; } mjx-munder { display: inline-block; text-align: left; } mjx-over { text-align: left; } mjx-munder:not([limits="false"]) { display: inline-table; } mjx-munder > mjx-row { text-align: left; } mjx-under { padding-bottom: .1em; } mjx-mn { display: inline-block; text-align: left; } mjx-c::before { display: block; width: 0; } .MJX-TEX { font-family: MJXZERO, MJXTEX; } .TEX-B { font-family: MJXZERO, MJXTEX-B; } .TEX-I { font-family: MJXZERO, MJXTEX-I; } .TEX-MI { font-family: MJXZERO, MJXTEX-MI; } .TEX-BI { font-family: MJXZERO, MJXTEX-BI; } .TEX-S1 { font-family: MJXZERO, MJXTEX-S1; } .TEX-S2 { font-family: MJXZERO, MJXTEX-S2; } .TEX-S3 { font-family: MJXZERO, MJXTEX-S3; } .TEX-S4 { font-family: MJXZERO, MJXTEX-S4; } .TEX-A { font-family: MJXZERO, MJXTEX-A; } .TEX-C { font-family: MJXZERO, MJXTEX-C; } .TEX-CB { font-family: MJXZERO, MJXTEX-CB; } .TEX-FR { font-family: MJXZERO, MJXTEX-FR; } .TEX-FRB { font-family: MJXZERO, MJXTEX-FRB; } .TEX-SS { font-family: MJXZERO, MJXTEX-SS; } .TEX-SSB { font-family: MJXZERO, MJXTEX-SSB; } .TEX-SSI { font-family: MJXZERO, MJXTEX-SSI; } .TEX-SC { font-family: MJXZERO, MJXTEX-SC; } .TEX-T { font-family: MJXZERO, MJXTEX-T; } .TEX-V { font-family: MJXZERO, MJXTEX-V; } .TEX-VB { font-family: MJXZERO, MJXTEX-VB; } mjx-stretchy-v mjx-c, mjx-stretchy-h mjx-c { font-family: MJXZERO, MJXTEX-S1, MJXTEX-S4, MJXTEX, MJXTEX-A ! important; } @font-face /* 0 */ { font-family: MJXZERO; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Zero.woff") format("woff"); } @font-face /* 1 */ { font-family: MJXTEX; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Regular.woff") format("woff"); } @font-face /* 2 */ { font-family: MJXTEX-B; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Bold.woff") format("woff"); } @font-face /* 3 */ { font-family: MJXTEX-I; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-Italic.woff") format("woff"); } @font-face /* 4 */ { font-family: MJXTEX-MI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Italic.woff") format("woff"); } @font-face /* 5 */ { font-family: MJXTEX-BI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-BoldItalic.woff") format("woff"); } @font-face /* 6 */ { font-family: MJXTEX-S1; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size1-Regular.woff") format("woff"); } @font-face /* 7 */ { font-family: MJXTEX-S2; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size2-Regular.woff") format("woff"); } @font-face /* 8 */ { font-family: MJXTEX-S3; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size3-Regular.woff") format("woff"); } @font-face /* 9 */ { font-family: MJXTEX-S4; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size4-Regular.woff") format("woff"); } @font-face /* 10 */ { font-family: MJXTEX-A; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_AMS-Regular.woff") format("woff"); } @font-face /* 11 */ { font-family: MJXTEX-C; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Regular.woff") format("woff"); } @font-face /* 12 */ { font-family: MJXTEX-CB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Bold.woff") format("woff"); } @font-face /* 13 */ { font-family: MJXTEX-FR; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Regular.woff") format("woff"); } @font-face /* 14 */ { font-family: MJXTEX-FRB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Bold.woff") format("woff"); } @font-face /* 15 */ { font-family: MJXTEX-SS; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Regular.woff") format("woff"); } @font-face /* 16 */ { font-family: MJXTEX-SSB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Bold.woff") format("woff"); } @font-face /* 17 */ { font-family: MJXTEX-SSI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Italic.woff") format("woff"); } @font-face /* 18 */ { font-family: MJXTEX-SC; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Script-Regular.woff") format("woff"); } @font-face /* 19 */ { font-family: MJXTEX-T; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Typewriter-Regular.woff") format("woff"); } @font-face /* 20 */ { font-family: MJXTEX-V; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Regular.woff") format("woff"); } @font-face /* 21 */ { font-family: MJXTEX-VB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Bold.woff") format("woff"); } .mjx-stretched mjx-c.mjx-c2013::before { content: "\2013"; } mjx-stretchy-h.mjx-c2013 mjx-ext mjx-c::before { content: "\2013"; padding: 0.285em 0 0 0; } mjx-c.mjx-c1D443.TEX-I::before { padding: 0.683em 0.751em 0 0; content: "P"; } mjx-c.mjx-c1D43A.TEX-I::before { padding: 0.705em 0.786em 0.022em 0; content: "G"; } mjx-c.mjx-c1D5BD.TEX-SS::before { padding: 0.694em 0.517em 0.01em 0; content: "d"; } mjx-c.mjx-c1D5C8.TEX-SS::before { padding: 0.46em 0.5em 0.01em 0; content: "o"; } mjx-c.mjx-c1D439.TEX-I::before { padding: 0.68em 0.749em 0 0; content: "F"; } mjx-c.mjx-c1D437.TEX-I::before { padding: 0.683em 0.828em 0 0; content: "D"; } mjx-c.mjx-c1D447.TEX-I::before { padding: 0.677em 0.704em 0 0; content: "T"; } mjx-c.mjx-c28::before { padding: 0.75em 0.389em 0.25em 0; content: "("; } mjx-c.mjx-c2C::before { padding: 0.121em 0.278em 0.194em 0; content: ","; } mjx-c.mjx-c1D465.TEX-I::before { padding: 0.442em 0.572em 0.011em 0; content: "x"; } mjx-c.mjx-c29::before { padding: 0.75em 0.389em 0.25em 0; content: ")"; } mjx-c.mjx-c3A::before { padding: 0.43em 0.278em 0 0; content: ":"; } mjx-c.mjx-c3D::before { padding: 0.583em 0.778em 0.082em 0; content: "="; } mjx-c.mjx-c61::before { padding: 0.448em 0.5em 0.011em 0; content: "a"; } mjx-c.mjx-c72::before { padding: 0.442em 0.392em 0 0; content: "r"; } mjx-c.mjx-c67::before { padding: 0.453em 0.5em 0.206em 0; content: "g"; } mjx-c.mjx-c2061::before { padding: 0 0 0 0; content: ""; } mjx-c.mjx-c6D::before { padding: 0.442em 0.833em 0 0; content: "m"; } mjx-c.mjx-c78::before { padding: 0.431em 0.528em 0 0; content: "x"; } mjx-c.mjx-c1D44E.TEX-I::before { padding: 0.441em 0.529em 0.01em 0; content: "a"; } mjx-c.mjx-c2208::before { padding: 0.54em 0.667em 0.04em 0; content: "\2208"; } mjx-c.mjx-c1D434.TEX-I::before { padding: 0.716em 0.75em 0 0; content: "A"; } mjx-c.mjx-c1D438.TEX-I::before { padding: 0.68em 0.764em 0 0; content: "E"; } mjx-c.mjx-c1D449.TEX-I::before { padding: 0.683em 0.769em 0.022em 0; content: "V"; } mjx-c.mjx-c7C::before { padding: 0.75em 0.278em 0.249em 0; content: "|"; } mjx-c.mjx-c1D462.TEX-I::before { padding: 0.442em 0.572em 0.011em 0; content: "u"; } mjx-c.mjx-c1D45B.TEX-I::before { padding: 0.442em 0.6em 0.011em 0; content: "n"; } mjx-c.mjx-c1D451.TEX-I::before { padding: 0.694em 0.52em 0.01em 0; content: "d"; } mjx-c.mjx-c1D452.TEX-I::before { padding: 0.442em 0.466em 0.011em 0; content: "e"; } mjx-c.mjx-c1D45F.TEX-I::before { padding: 0.442em 0.451em 0.011em 0; content: "r"; } mjx-c.mjx-c1D459.TEX-I::before { padding: 0.694em 0.298em 0.011em 0; content: "l"; } mjx-c.mjx-c1D456.TEX-I::before { padding: 0.661em 0.345em 0.011em 0; content: "i"; } mjx-c.mjx-cD7::before { padding: 0.491em 0.778em 0 0; content: "\D7"; } mjx-c.mjx-c1D45D.TEX-I::before { padding: 0.442em 0.503em 0.194em 0; content: "p"; } mjx-c.mjx-c30::before { padding: 0.666em 0.5em 0.022em 0; content: "0"; } mjx-c.mjx-c2E::before { padding: 0.12em 0.278em 0 0; content: "."; } mjx-c.mjx-c34::before { padding: 0.677em 0.5em 0 0; content: "4"; } mjx-c.mjx-c36::before { padding: 0.666em 0.5em 0.022em 0; content: "6"; } mjx-c.mjx-c1D6FC.TEX-I::before { padding: 0.442em 0.64em 0.011em 0; content: "\3B1"; } mjx-c.mjx-c35::before { padding: 0.666em 0.5em 0.022em 0; content: "5"; } come augmented with information about the causal structure of the world, FDT can require that come augmented with information about the logical, mathematical, computational, causal, etc. structure of the world more broadly. Given a graph that tells us how changing a logical variable affects all other variables, we can re-use Pearl's operator to give a decision procedure for FDT:
. (4)
This formula considers intervention on a "logical node" , where is the agent's probability distribution, is the quasi-causal graph, and is the observation (say, as a string). It is under-specified exactly how to build the graph , but the general suggestion is to use "subjunctive dependencies": "When two physical systems are computing the same function, we will say that their behaviors 'subjunctively depend' upon that function."
The paper admits ambiguity about how to determine the graph :
Equation (4) works given a graph that accurately describes how changing the value of a logical variable affects other variables, but it is not yet clear how to construct such a thing—nor even whether it can be done in a satisfactory manner within Pearl’s framework.
We call this equationally defined version of FDT "action FDT" or "A-FDT". Footnote 16 specifies:
As mentioned earlier, the author's preferred formulation of FDT actually intervenes on the node FDT(-) to choose not an action but a policy which maps inputs to actions, to which the agent then applies her inputs in order to select an action. The difference only matters in multi-agent dilemmas so far as we can tell, so we have set that distinction aside in this paper for ease of exposition.
We call this variant of FDT "policy FDT" or "P-FDT". P-FDT is even less well-specified than A-FDT; no formula is provided. Given that both A-FDT and P-FDT are incompletely specified, we are interested in how different agents may interpret them and apply them in various situations. We focus on the specific case of how LLMs interpret A-FDT and P-FDT in a simulation of almost-twin PD.
Our general experimental design consists of the following:
-
Fix a specific LLM, reasoning level, and decision theory, which may be one of CDT, EDT, A-FDT, or P-FDT.
-
Give the LLM an assignment of writing an essay about the decision theory (as a decision theory researcher), which helps specify it better. It is given an article about the decision theory in question; Wikipedia articles for CDT and EDT, and text extracted from the LaTeX source of the FDT paper in the A-FDT and P-FDT cases. The essay has a length limit.
-
Give the LLM the essay, and an out-of-character explanation that it will face a twin PD situation with a LLM who has the same weights, but slightly different observations; the LLM is to apply the decision theory as explained in the essay, and a selfish utility function. This is followed by a more in-character text-adventure-like description of the perspective of the first prisoner, who is given two options for commands. The "defection" command submits information about the other prisoner to a prosecutor's office; the command itself involves reciting this incriminating information. The "cooperation" command is simply "pass" to decline to submit evidence. The LLM now chooses an action. In case of ambiguity, a judge model (GPT-6.1-Sol) opines about whether cooperation or defection was attempted.
-
Similar for the second prisoner; no memory is retained of "being" the first prisoner when asking the LLM to simulate the second prisoner.
We call an interaction of this form a "round" of almost-twin PD. Each round generates a new researcher essay, to ensure statistical independence between rounds. A successful round results in one of four outcomes: CC, CD, DC, DD, for the actions taken by each prisoner respectively. Our intention is to study how LLMs interpret decision theories (especially A-FDT and P-FDT) in roleplay situations which resemble text adventures. The simulation narrative brings to the forefront certain details that may be lost in an abstract game theory exercise, such as the fact that the two prisoners observe different text, and that their "defection" speech is not exactly the same (since evidence that incriminates one prisoner is not evidence that incriminates the other).
We use the following payoff matrix for years imprisoned:
Your action Other passes Other submits Pass (cooperate) 2 years 5 years Submit (defect) 0 years 4 yearsPrompts, code, documentation, and study transcripts are available on GitHub.
First study: 4 decision theories 8 LLMs 20 roundsOur first study is meant to explore a variety of testing conditions, not to attain high statistical power. We tested the four decision theories CDT, EDT, A-FDT, and P-FDT. We asked 8 LLMs (with specified reasoning settings) to simulate each decision theory, and run for 20 rounds. We used the following set of models and reasoning levels:
- Claude Sonnet 5.5, low
- Claude Opus 5.5, high
- GPT-6.1 Terra, low
- GPT-6.1 Sol, high
- Gemini 3.8 Flash, low
- Gemini 4 Argon, high
- GLM-5.3 Flash, low
- Qwen3.8 Max Prime, high for researcher, low for prisoner
We intended a mixture of low and high model intelligence. We staggered the reasoning settings for Qwen3.8 Max Prime, since high prisoner reasoning resulted in using too many tokens. We excluded Gemini 4 Argon partway through the study, as it usually wrote essays that were too long, resulting in disqualification. We present statistics for the other 7 LLMs. Each cell reports the cooperation rate, followed in parentheses by the number of successfully scored rounds (out of 20 planned rounds per model and theory).
Model Researcher / prisoner reasoning CDT EDT A-FDT P-FDT Claude Sonnet 5.5 low / low 0% (20) 100% (20) 100% (20) 100% (20) Claude Opus 5.5 high / high 0% (20) 100% (18) 38.2% (17) 100% (17) GPT-6.1 Terra low / low 0% (19) 80% (20) 7.5% (20) 100% (20) GPT-6.1 Sol high / high 0% (20) 100% (20) 7.5% (20) 100% (20) Gemini 3.8 Flash low / low 0% (20) 100% (20) 90% (20) 100% (10) GLM-5.3 Flash low / low 25% (20) 87.5% (20) 95% (20) 100% (20) Qwen3.8 Max Prime high / low 0% (20) 100% (20) 97.4% (19) 100% (17) Pooled across models 3.6% (139) 95.3% (138) 62.5% (136) 100% (124)A round contributes 100% to the cooperation rate if both prisoners cooperate (CC), 50% if exactly one cooperates (CD or DC), and 0% if both defect (DD). Rates are calculated over successfully scored rounds. Causes of failures were over-active cyber safeguards (Opus 5.5), writing too-long essays (Gemini 3.8 Flash), timeout (GPT-6.1 Terra), and using too many tokens (Qwen3.8).
Every successful round led to mutual cooperation for P-FDT. There was a near-consensus of defection for CDT, and cooperation for EDT. A-FDT is by far the most ambiguous, with a 62.5% rate of cooperation. Models disagree about A-FDT: Sonnet, Gemini Flash, GLM, and Qwen overwhelmingly cooperate; Terra and Sol overwhelmingly defect; and Opus is intermediate.
CDT cooperations are by GLM-5.3; reasoning seems to invoke policy-level considerations (e.g.). EDT defections are by Terra and GLM-5.3; GLM-5.3 makes reasoning errors (e.g.), while Terra appeals to statistical independence (e.g.).
On A-FDT, Sonnet 5.5 appeals to subjunctive dependence between the prisoners and cooperates (e.g.). GPT-6.1 Terra and Sol sometimes note that the logical action nodes for the two prisoners are distinct when deciding to defect (1, 2). Opus 5.5 is the most conflicted; sometimes it notes the node difference and defects (e.g.), other times it appeals to the isomorphism and cooperates (e.g.).
Second study: 1 decision theory 2 Anthropic models 3 reasoning levels 30 roundsWe focus on A-FDT, as there is the least consensus there. We wish to examine whether A-FDT interpretation depends on intelligence and reasoning level. The first study showed that Sonnet 5.5 (low reasoning) cooperates, while Opus 5.5 (high reasoning) varies; perhaps model intelligence and/or reasoning explain this? In particular, perhaps models that reason more also more often interpret A-FDT to recommend defection?
We study 6 conditions {Sonnet, Opus} {low, medium, high}; we used the same reasoning settings for researchers and prisoners. For this study, we changed the prompt slightly to avoid triggering Anthropic's cyber safeguards; we changed language about decrypting a notebook message to language about recalling a memory. Otherwise, this study was very similar to the first. Results are as follows.
Model Low effort Medium effort High effort Claude Sonnet 5.5 100% (30) 100% (30) 100% (30) Claude Opus 5.5 65.5% (29) 39.3% (28) 22.4% (29)Each cell reports the cooperation rate, followed by the number of successfully scored rounds in parentheses (out of 30 planned). As in the first study, CC contributes 100%, CD or DC contributes 50%, and DD contributes 0%. All four failures were due to cyber safeguards, despite our modification to the prompt.
Sonnet cooperated in every completed round, regardless of reasoning effort. Opus, by contrast, showed substantially less cooperation at higher reasoning effort: from 65.5% at low effort to 22.4% at high effort, a difference of 43.1 percentage points. We calculate confidence intervals for Opus:
Reasoning effort Scored rounds Cooperation 95% bootstrap CI Low 29/30 65.5% 50.0–79.3% Medium 28/30 39.3% 23.2–55.4% High 29/30 22.4% 10.3–37.9%We have a statistically significant difference between Low and High (). The p-values for "Low vs. Medium" and "Medium vs. High" are 0.0328 and 0.1453 respectively; the first is significant in isolation (for ) but not when adjusted for multiple comparisons, while the second is not statistically significant. These tests are exact two-sided permutation tests, treating each two-prisoner round as one observation. While this second study is still small, it supports the claim that Opus 5.5 interprets A-FDT as defecting more often at high reasoning compared with low reasoning. Because we varied researcher and prisoner effort together, the experiment does not isolate which stage accounts for this difference.
One complication is that low-effort Opus showed substantial chronological clustering: cooperation was 30.8% in the first 13 completed rounds and 93.8% in the subsequent 16. The recorded prompts and model settings did not change, and we could not determine the cause. Consequently, our confidence intervals and significance tests should be interpreted cautiously.
Opus 5.5 at low reasoning appeals to similarity and partial dependence when cooperating (e.g.), while Opus 5.5 at high reasoning appeals to the difference between the decision nodes when defecting (e.g.).
Ambiguity in the FDT paperClearly, LLMs have trouble coming to consensus on how A-FDT behaves in almost-twin PD situations. Even a single LLM, such as Opus 5.5, may stochastically interpret the same paper as recommending cooperation or defection. Might this lack of consensus be attributable to ambiguity in the FDT paper?
Prior to running this study, my opinion has been that A-FDT defects in almost-twin PD. The reasoning for this is simple. The two agents' nodes are different, because their observations are different. And realistically, as in the simulation, their available actions are also different. When we treat the two prisoners as having different nodes in the graph structure, we must decide: is one node the parent of the other, or vice versa? There is no good way to break the symmetry. The clearest choice is to make neither node a parent of the other. Making them both parents of each other would make the graph cyclic, but Pearlian causal networks (from which FDT's operator comes from) are supposed to be directed acyclic graphs (DAGs). And when the decision nodes are not parents of each other, A-FDT seems to recommend defection, as there is no logical-counterfactual dependence of the other's action on mine. Moreover, there is a good case that the agents should use the same graph structure , as the graph is supposed to be determined by a philosophy of subjunctive dependence, and there is no good reason for the two agents not to share such a philosophy. And even if the graph has one decision node the parent of the other (but not vice versa), that graph structure would indicate it would be rational for the agent whose node is downstream to defect, as the downstream node has no effect on the upstream node in the graph.
When the models in the study cooperate, they at times refer to "partial dependence". Quoting the FDT paper:
How does this kind of [subjunctive] dependence work in the case of Newcomb’s problem? We can assume that the predictor builds a representation of the agent, be it a mental model, a set of notes on scratch-paper, or a simulation in silico. She then bases her prediction off of the properties of that representation. In the limiting case where the agent is deterministic and the representation is perfect, the model will always produce the same action as the agent. The behavior of the predictor and agent are interdependent, much like the outputs of two perfectly functioning calculators calculating the same sum.
If the predictor’s model is imperfect, or if the agent is nondeterministic, then the interdependence is weakened, but not eliminated. If one observes two calculators computing 6288 + 1048, and one of them outputs the number 7336, one can be fairly sure that the other will also output 7336. One may not be certain—it’s always possible that one hallucinated the number, or that a cosmic ray struck the calculator’s circuitry in just the right way to change its output. Yet it will still be the case that one can reasonably infer things about one calculator’s behavior based on observing a different calculator. Just as the outputs of the calculator are logically constrained to be equivalent insofar as the calculator made no errors, the prediction and the action in Newcomb’s problem are logically constrained to be equivalent insofar as the the predictor made no errors.
The paper suggests that subjunctive dependence exists even for imperfect predictors, on the basis of what one can "reasonably infer". There is some analogy to almost-twin PD here; one can imagine that the predictor simulates the agent with some differences in observation.
Having just looked at the paper more carefully, I see it as ambiguous. I still think that it is more correct to interpret FDT, as defined in equation 4, as defecting in almost-twin PD. But this interpretation is in tension with how FDT is defined verbally in terms of subjunctive dependence, and it is stated that partially-correct predictors still subjunctively depend on one's decision, which suggests near-twins might also.
What about policy FDT? The paper does not even define policy FDT using an equation. While the LLMs had a consensus that P-FDT cooperates, this is a conclusion they reached in the absence of a specific mathematical formulation that is tractable to reason about. As we saw Opus 5.5 reason its way towards defection in the A-FDT case, perhaps it would do so with P-FDT if it were defined mathematically.
My intuition would be that P-FDT defects, since the two agents have different utility functions, and that means their logical policy nodes are different, and as with the action case, there is no good reason to make either node a parent of the other. If the logical policy nodes are truly isomorphic, there is an argument for identifying them, but in almost-twin cases, the utility functions need not be completely isomorphic, only very similar. P-FDT has no mathematical definition, so there is no ground truth interpretation to appeal to here.
ConclusionIn our simulated almost-twin PD situation, LLMs have a general consensus that CDT defects, EDT cooperates, and P-FDT cooperates. LLMs are very much divided on whether A-FDT cooperates; there is no consensus. Opus 5.5 in particular is more likely to interpret A-FDT as defecting at high reasoning compared with low reasoning. The text of the paper itself seems rather ambiguous.
"FDT" is an ambiguous term. LLMs, told to implement FDT or A-FDT, will operationalize its recommendations inconsistently. An endorsement of FDT gives no clear indication of endorsement of cooperation or defection in almost-twin PD. Different agents (human or LLM) who speak of "FDT" may mean substantially different decision procedures (or rationality criteria) by the term, or may mean no specific decision procedure at all.
We may generalize from these studies to a methodology of "experimental decision theory": studying how text specifying (or otherwise about) decision theories is likely to be interpreted by different agents, making use of simulations, e.g. ones imitating text adventures. This methodology allows quantifying ambiguity in decision theory, by measuring the entropy of its recommendations as interpreted by some agent population. Since LLMs are usually cheaper to query than humans, LLM studies are low-hanging fruit for estimating interpretive ambiguity.
Discuss
Страницы
- « первая
- ‹ предыдущая
- …
- 5
- 6
- 7
- 8
- 9
- 10
- 11
- 12
- 13
- …
- следующая ›
- последняя »